 JevCode
재랭킹
40개의 CLERC 법적 쿼리에 대해 30개 구절의 BM25 후보군을 구성한 후, 쿼리-후보 쌍마다 하나의 TypeSafe 질문을 사용하여 상위 1위 정확도를 5%에서 18%로, 상위 10위 정확도를 38%에서 62%로 향상시킵니다.
이 문서는 en에서 기계 번역되었으며 교정되지 않았습니다. 빠른 참고용으로만 사용하세요.

수천 개의 문서가 있고, 특정 질문에 대한 답이 담긴 문서를 찾아야 합니다. 그렇다면 어떻게 찾아야 할까요?
먼저 키워드 매칭과 같은 빠른 방법을 사용해 수천 명의 후보자를 합리적인 후보 목록으로 줄입니다. 이를 빠른 검색이라고 부릅니다.
빠른 검색은 그 부분에서는 뛰어나지만, 쇼트리스트에 있는 후보 중 어느 것이 정답인지 알려주지는 못합니다. 바로 여기서 재랭킹이 등장합니다. 재랭킹은 쿼리와 직접 비교하여 쇼트리스트의 각 후보에 점수를 매기고, 가장 우수한 것을 최상위에 배치합니다.
두 단계는 모두 CLERC 데이터셋의 3,565개 법원 의견 구절에서 아래에서 실행됩니다: BM25는 각 쿼리 40개당 30개의 후보로 구성된 빠른 검색 후보군을 생성한 다음, TypeSafe가 각 후보군을 재순위화합니다. 재순위화를 적용하면 정답 구절이 쿼리의 18%에서 1위를 차지하며, 이는 빠른 검색만 사용했을 때의 5%에서 증가한 수치입니다.
그 과정에서 다음을 배우게 됩니다:
- 빠른 검색이 무엇을 하는지, 그리고 그것이 전부가 아닌 이유
- 리랭킹이 무엇인지, 그리고 빠른 검색 단계 이후에 어떻게 맞물리는지
- TypeSafe가 하나의 후보를 쿼리에 대해 어떻게 점수 매기는지, 그리고 그것이 결과를 얼마나 개선하는지
직접 해보세요
TypeSafe Playground에서 쿼리, 후보, 재순위 지정 질문 열기
수천 개의 문서 중 하나를 어떻게 찾나요?
문서 더미와 쿼리가 있습니다. 쿼리는 당신이 찾고 있는 내용을 설명하는 텍스트입니다. 더미 어딘가에는 그 질문에 답하는 단 한 개의 문서가 있습니다.
문서 하나하나를 쿼리와 비교하며 확인하는 방식은 한 문서당 한 번의 비교로 작동합니다: 수백만 개의 문서는 쿼리당 수백만 번의 비교를 의미합니다. 성능을 두 단계 접근법으로 개선할 수 있습니다:
- 전체 데이터셋에서 빠르게 실행할 수 있는 방법을 사용해, 유력한 후보들만 포함하는 짧은 목록으로 줄입니다.
- 그 짧은 목록에 더 정확한 단계를 적용해 정확한 정답을 찾아냅니다.
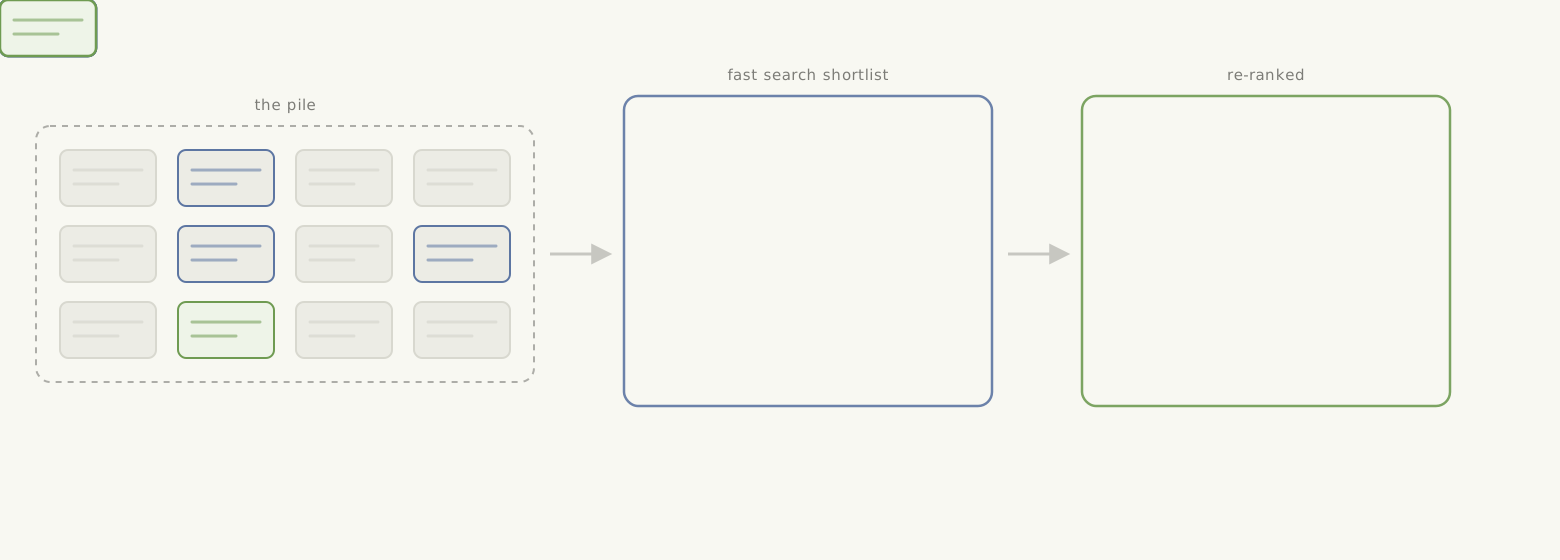
이 쿡북은 아래 실제 예제에서의 재랭킹에서 법원 의견 데이터셋을 사용해 해당 설정을 테스트합니다.
빠른 검색이란 무엇인가요?
빠른 검색은 대규모 코퍼스의 모든 문서에 대해 쿼리를 비교하고 순위 매긴 짧은 목록을 빠르게 반환할 수 있는 모든 방법을 의미합니다. 일반적인 방법으로는 BM25와 같은 키워드 검색, 의미에 따라 구절을 비교하는 밀집 임베딩 등이 있으며, 시스템은 종종 두 가지 방법을 결합합니다.
여기서의 첫 단계는 BM25이며 그 이상도 이하도 아니다. BM25은 공유된 단어를 기준으로 패시지를 순위 매긴다. 이 단계를 단순하게 유지하면 주의력을 재순위 매기기(re-ranking)에 집중할 수 있는데, 이것이 바로 이 쿡북의 핵심이다. 빠른 검색 방법의 선택은 부수적인 문제이다. 재순위 매기기는 짧은 목록에 오른 패시지만을 항상 처리한다.
리랭킹이란 무엇인가?
Re-ranking은 이미 생성된 짧은 검색 목록을 받아 더 나은 순서로 배치합니다. 쿼리를 전체 코퍼스와 한 번에 비교하는 대신, 짧은 목록에 있는 각 후보와 쿼리를 개별적으로 비교하고, 그 점수를 바탕으로 짧은 목록을 정렬합니다.
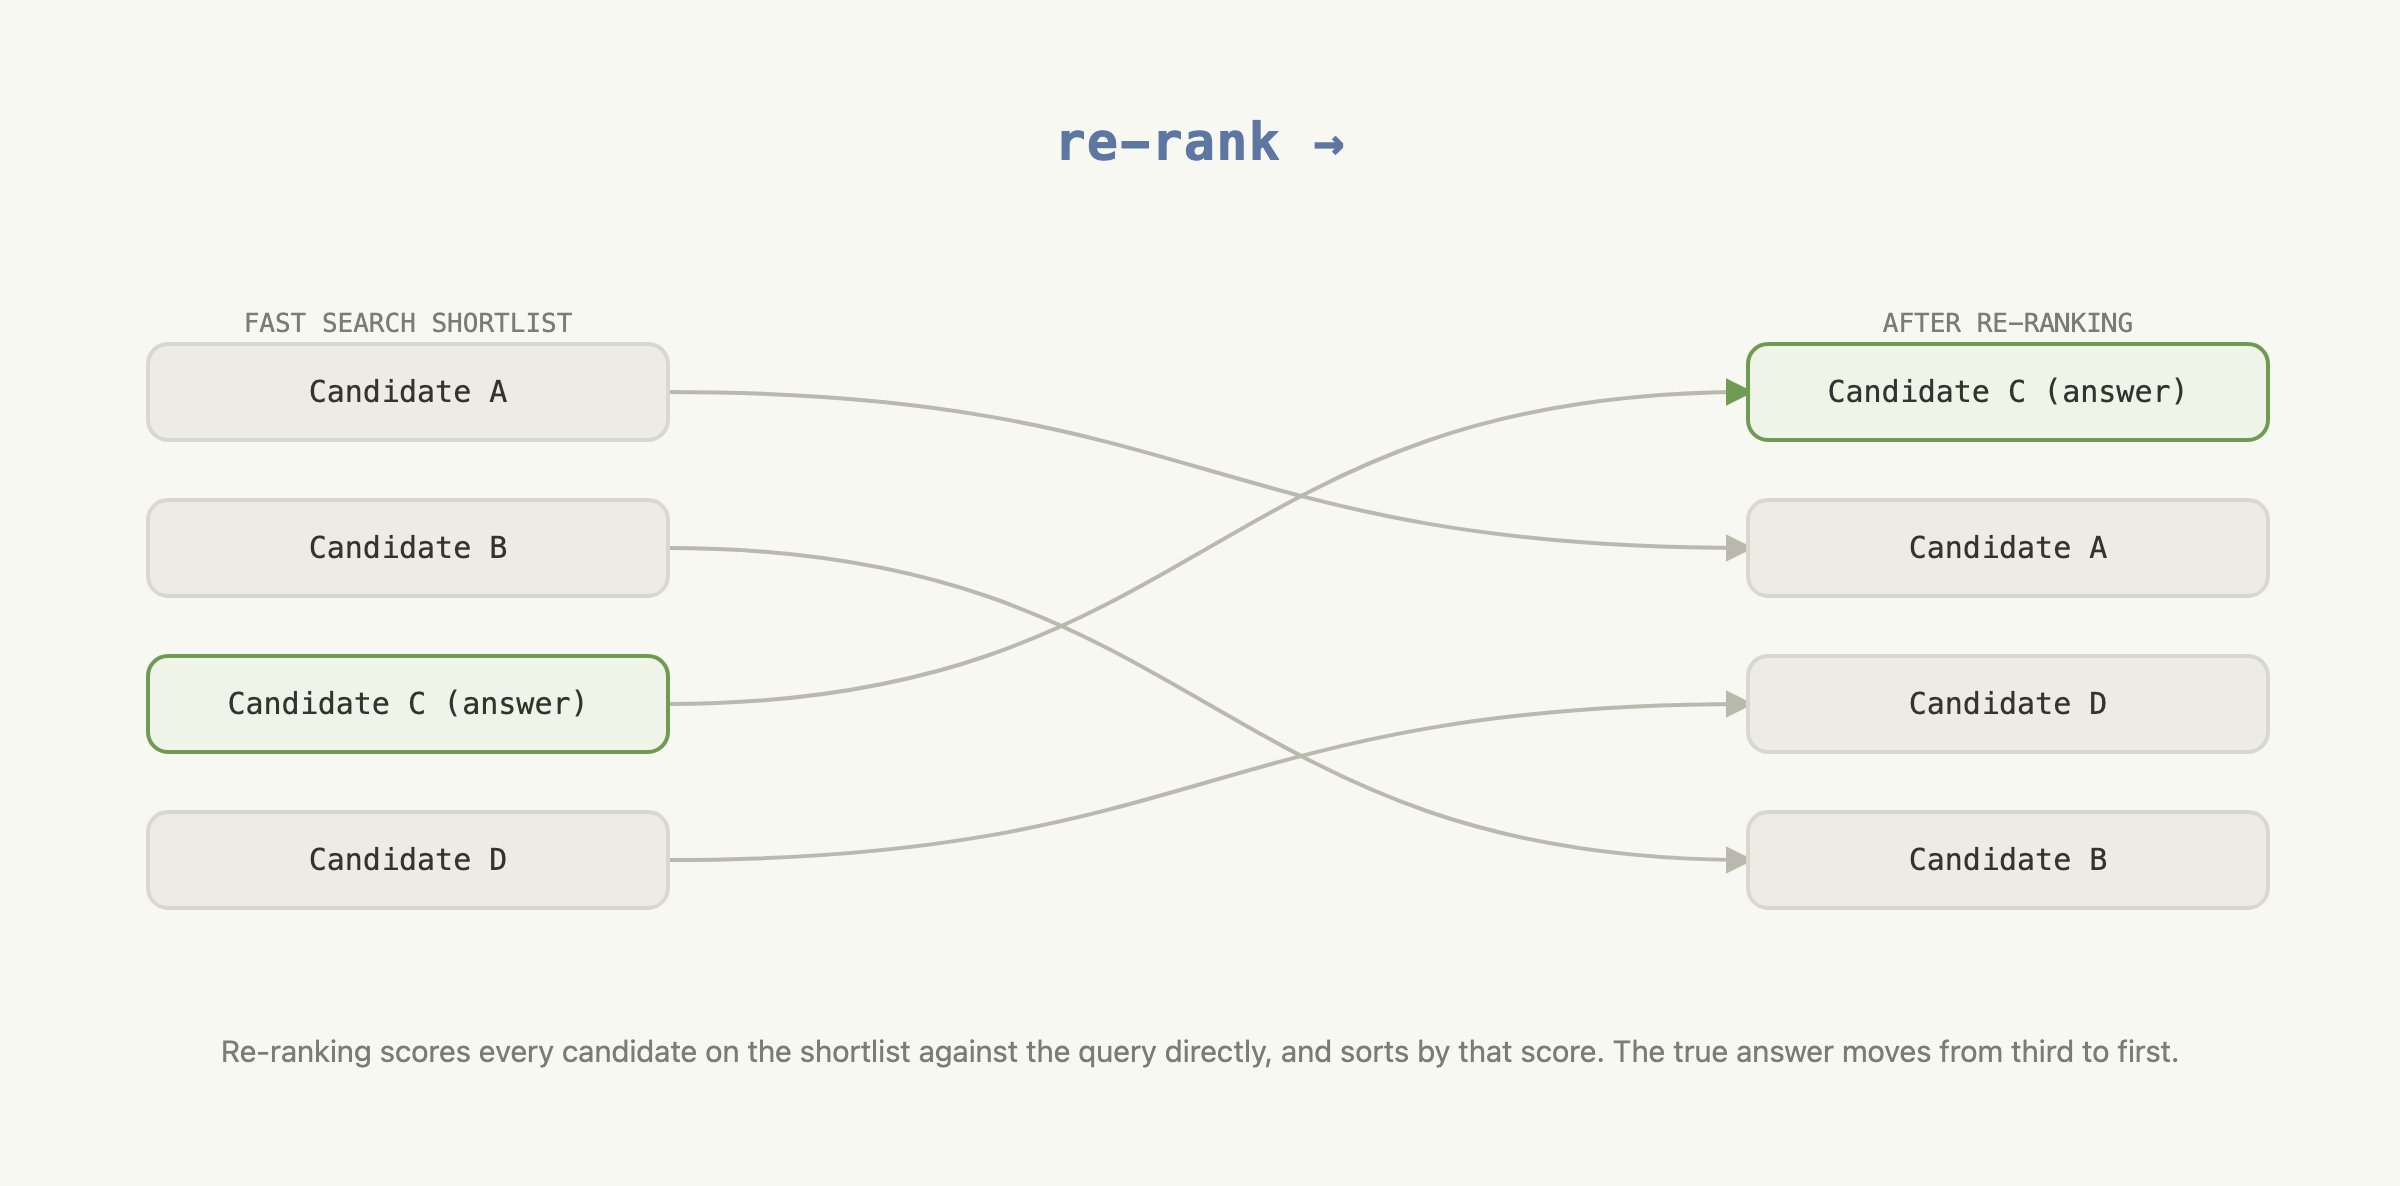
점수는 언어 모델에서 나올 수 있습니다. 쿼리와 후보를 함께 제공하고, 해당 후보가 쿼리를 얼마나 잘 답변하는지 물어보세요. 그런 다음 재순위 매기는 쿼리의 어조와 다르더라도 짧은 목록에서 가장 적합한 항목을 찾습니다.
TypeSafe를 사용한 재랭킹
A re-ranker needs a comparable score for every query-candidate pair. A general-purpose language model can produce these scores, or rank the whole shortlist directly. For independent pair scoring, however, you need to define a scoring scale and prompt the model to apply the same standard to every candidate. Repeated calls can still produce different scores for the same pair, while general-purpose generation adds time and cost to a task that only needs one number.
TypeSafe이 반환하는 것
TypeSafe를 사용하면 점수 요청을 예/아니오 질문으로 유지할 수 있습니다:
Could this candidate passage be from the cited precedent?단순한 예/아니오로는 30명의 후보를 순위 매기기에는 부족하다. Noul 대신
noul이라는 0과 1 사이의 숫자를 반환한다. noul은 TypeSafe가
답변이 예일 확률을 추정한 값이다.
질문의 기준은 참과 거짓을 판별하는 기준을 정의합니다. TypeSafe는 이를 모든 쿼리-후보 쌍에 적용하여 noul을 직접 반환합니다. 이 noul이 애플리케이션이 정렬하는 기준이 되는 점수입니다. 범용 모델에 대해 별도의 점수 척도를 발명할 필요가 없으며, TypeSafe는 이러한 반복적인 점수 매기를 더 빠르고, 저렴하며, 일관되게 수행하도록 설계되었습니다.
간소화된 의사코드에서 TypeSafe 스코어링 호출은 다음과 같습니다:
question = Noul(
    instructions="Is this candidate the cited case?",
    criteria=NoulCriteria(
        true="The candidate states the specific rule the query cites.",
        false="The candidate is only on a similar topic.",
    ),
)
response = client.system_one(state={...}, questions={"is_cited_source": question})
response.answers["is_cited_source"].noul  # -> 0.87
TypeSafe는 쿼리와 후보를 해당 질문에 대해 함께 읽어서 noul을 반환합니다.
이 기능을 사용하여 짧은 후보 목록을 다시 순위 매길 수 있습니다. 목록에 있는 모든 후보에 대해 동일한 질문을 실행한 후, 각 호출에서 반환된 noul을 기준으로 후보 목록을 정렬하면 됩니다. 가장 높은 noul이 먼저 오도록 정렬합니다.
nouls = {candidate: ask_typesafe(query, candidate) for candidate in shortlist}
reranked = sorted(shortlist, key=lambda c: nouls[c], reverse=True)  # highest noul first
아래 다이어그램은 각 후보별로 하나의 요청이 짧은 목록을 재정렬하는 데 사용되는 점수를 생성하는 방식을 보여줍니다.
흐름 방향: LR
| 노드 | 설명 | 그룹 |
|---|---|---|
q |
쿼리 발췌 / 한 가지 의견 단락, / 인용문 제거 | — |
sl |
빠른 검색에서 후보군 선별 / 30개 후보 단락 | — |
quest |
단일 Noul / 이 후보가 인용된 선례에서 / 유래한 것일 수 있는가? / 기준 정확도 조정 (참/거짓) | — |
fan |
후보별 단일 요청 · 각 요청은 다른 요청을 볼 수 없음 | 후보별 단일 요청 · 각 요청은 다른 요청을 볼 수 없음 |
sort |
Noul 기준 정렬 / 최고 순위 우선 | — |
out |
재순위 매겨진 후보군 / 동일한 30개, 더 나은 순서 | — |
| From | Condition | To |
|---|---|---|
q |
— | fan |
sl |
— | fan |
quest |
— | fan |
fan |
— | sort |
재랭킹 예시
빠른 검색 및 재랭킹은 이제 법률 검색 데이터셋인 CLERC에서 실행됩니다. 이 예시에서는 3,565건의 법원 의견 문단과 40개의 쿼리를 사용합니다.
Setup
첫 번째 단계는 이 안내서에서 의존하는 패키지를 설치합니다.
bm25s와datasets는 빠른 검색 후보 목록을 생성합니다.typesafe-sdk와cooksafe는 재순위 매기기 및 API 캐싱을 처리합니다.matplotlib는 결과 차트를 그립니다.
pip install bm25s datasets matplotlib "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/다음 블록은 TypeSafe 클라이언트와 나머지 안내에서 사용하는 상수들(예: 호출할 TypeSafe 모델, fast search가 re-ranker에 전달하는 shortlist의 크기 등)을 설정합니다. TypeSafe 호출에는 TYPESAFE_API_KEY이 필요합니다.
import hashlib
import json
import os
import random
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path

import msgspec
from cooksafe import JsonCache
from IPython.display import display
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
PRICE = (
    0.042,
    0.00,
)  # $ per 1M tokens (input, output); TypeSafe jev-1.12 as of 2026-08
N_ROWS = 170  # CLERC rows pooled into the shared corpus
N_QUERIES = 40  # rows we evaluate
TOP_K = 30  # candidates the shortlist hands to the re-ranker, per query

client = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # keyless kernels replay the cache
    base_url=os.environ.get("TYPESAFE_ENDPOINT"),
    timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
빠른 검색으로 구문 순위 매기기
여기서 사용되는 데이터셋은 미국 법원 판결문의 코퍼스이며, 170개의 행이 통합되어 있습니다. 각 행은 다음과 같이 구성됩니다:
- 쿼리: 인용문이 제거된 의견 발췌문.
- 정답: 인용문이 가리켰던 구절, 즉 쿼리에 대한 유일한 정답.
- 후보: 코퍼스의 나머지 모든 구절. 쿼리가 실수로 매칭될 수 있는 각각의 항목.
170개의 행 중 40개가 쿼리로 평가하기 위해 선택됩니다. 나머지 130개는 후보로만 나타납니다.
다음 셀은 위에서 설명한 기법을 사용하여 쇼트리스트를 작성합니다:
- 코퍼스를 로드합니다.
- 각 쿼리마다 BM25로 순위를 매깁니다.
여기에는 아직 TypeSafe가 없습니다. 이것은 빠른 검색 단계일 뿐입니다.
CLERC_FILE = (
    "https://huggingface.co/datasets/jhu-clsp/CLERC/resolve/main/"
    "teva_train_dir/train_data.jsonl.gz"
)


def cid(text: str) -> str:
    """Corpus id: a content hash, so passages shared across queries dedupe."""
    return hashlib.sha1(text.encode("utf-8")).hexdigest()[:16]


@json_cache
def build_slice(n_rows: int, n_queries: int, seed: int) -> dict:
    """Stream CLERC rows, pool ``n_rows`` of them into a corpus, pick ``n_queries`` to evaluate."""
    from datasets import load_dataset  # heavy import, keep local

    stream = load_dataset("json", data_files=CLERC_FILE, streaming=True, split="train")
    rows = []
    for row in stream:
        if (
            row.get("positive_passages")
            and len(row.get("negative_passages") or []) == 20
        ):
            rows.append(row)
        if len(rows) >= 1000:
            break

    rng = random.Random(seed)
    picked = rng.sample(rows, n_rows)
    corpus, pool = {}, []
    for row in picked:
        gold = row["positive_passages"][0]["text"]
        corpus[cid(gold)] = gold
        for neg in row["negative_passages"]:
            corpus[cid(neg["text"])] = neg["text"]
        pool.append(
            {"qid": str(row["query_id"]), "query": row["query"], "gold": cid(gold)}
        )
    # hold out the first 20 pooled rows; evaluate on the rest
    queries = rng.sample(pool[20:], n_queries)
    # sort the corpus by id so every run — live or cache replay — iterates it identically
    return {"queries": queries, "corpus": dict(sorted(corpus.items()))}


def bm25_rankings(corpus: dict[str, str], queries: dict[str, str], k: int = 100):
    """Rank every passage in the corpus by word overlap with each query."""
    import bm25s

    cids = list(corpus)
    retriever = bm25s.BM25()
    retriever.index(bm25s.tokenize([corpus[c] for c in cids], stopwords="en"))
    qids = list(queries)
    idxs, _ = retriever.retrieve(
        bm25s.tokenize([queries[q] for q in qids], stopwords="en"), k=min(k, len(cids))
    )
    return {q: [cids[i] for i in idxs[row]] for row, q in enumerate(qids)}


def gold_rank(ranked: list[str], gold: str) -> int | None:
    """1-based rank of the gold id, or None if it isn't in the list."""
    return ranked.index(gold) + 1 if gold in ranked else None


SURFACE, INK, INK2, MUTED = "#f8f8f2", "#34342f", "#34342f", "#7c7c77"
GRID, AXIS, BLUE, GREEN = "#d8d8cf", "#d8d8cf", "#5d76a2", "#6f9b52"


def bar_chart(labels: list[str], shares: list[float], title: str) -> None:
    """A small single-series bar chart of shares (0-1, shown as percentages)."""
    import matplotlib.pyplot as plt

    fig, ax = plt.subplots(figsize=(5, 3.2), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    bars = ax.bar(labels, shares, width=0.55, color=[BLUE, GREEN][: len(labels)])
    ax.bar_label(
        bars,
        labels=[f"{s * 100:.0f}%" for s in shares],
        padding=4,
        color=INK,
        fontsize=11,
    )
    ax.set_ylim(0, 1.1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(title, loc="left", color=INK, fontsize=11)
    plt.tight_layout()
    display(fig)
    plt.close(fig)


ds = build_slice(N_ROWS, N_QUERIES, seed=0)
corpus: dict[str, str] = ds["corpus"]
queries = {q["qid"]: q["query"] for q in ds["queries"]}
golds = {q["qid"]: q["gold"] for q in ds["queries"]}

candidates = {q: ranked[:TOP_K] for q, ranked in bm25_rankings(corpus, queries).items()}

in_top_k = sum(golds[q] in candidates[q] for q in queries)
at_rank_1 = sum(candidates[q][0] == golds[q] for q in queries)

bar_chart(
    [f"In top {TOP_K}", "At rank 1"],
    [in_top_k / len(queries), at_rank_1 / len(queries)],
    f"Where the correct passage lands, {len(queries)} queries against {len(corpus):,} candidates",
)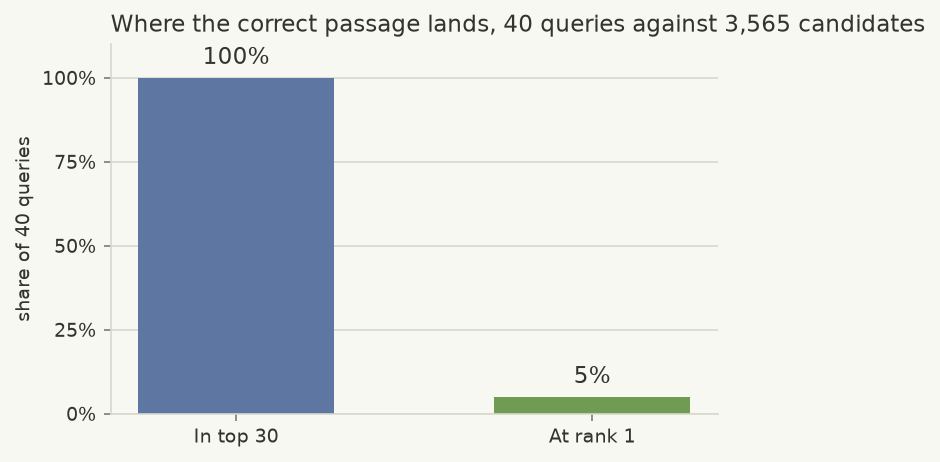
빠른 검색은 올바른 구절을 첫 번째로 랭킹할 가능성이 낮습니다
차트는 3,565개 후보 중 빠른 검색이 정답 항을 어디에 배치하는지를 보여줍니다.
빠른 검색은 올바른 답변이 포함된 짧은 후보 목록으로 코퍼스를 정확하게 좁혀줍니다. 40개 쿼리 모두에서 올바른 답변을 포함하고 있습니다. 하지만 해당 구절은 후보 목록에서 상위 랭크되는 경우가 거의 없으며, 단 5%의 경우에만 그렇습니다.
아래의 재랭킹은 이미 숏리스트에 포함된 상위 30개 후보의 순서만 재배열합니다. 빠른 검색에서 선택하지 않은 패세지를 추가할 수 없습니다. 여기서는 숏리스트에 40개 쿼리 모두에 대한 정답 패세지가 포함되어 있으므로, 재랭킹은 각 패세지를 더 나은 위치로 배치하는 데 집중할 수 있습니다.
TypeSafe로 재랭킹하기
짧은 후보 목록에 있는 각 후보를 쿼리와 비교하여 재순위화 점수를 산출한 후, 해당 점수로 정렬합니다. TypeSafe가 각 쌍에 대해 묻는 질문은 해당 후보가 쿼리의 제거된 인용이 가리키는 본문일 수 있는지 여부입니다.
다음 셀은 다음을 수행합니다:
- 그 질문을 정의한다.
- 각 후보자에게 매번 한 번씩 질문한다. 짧은 목록 40개에 후보자 30명, 총 1,200회 호출. 한 번에 하나씩이 아니라 병렬로 실행한다.
- TypeSafe가 반환한 점수로 각 짧은 목록을 정렬하여 재순위 결과를 생성한다.
is_cited_source = Noul(
    instructions=(
        "The query excerpt comes from a US federal court opinion and was written "
        "immediately around a citation to a precedent; the citation itself has been "
        "removed. Could the candidate passage be from that cited precedent — does it "
        "establish the specific legal proposition the query excerpt invokes at its "
        "citation point?"
    ),
    criteria=NoulCriteria(
        true=(
            "The candidate passage states or establishes the specific rule, standard, "
            "holding, or fact pattern that the query excerpt attributes to its removed "
            "citation."
        ),
        false=(
            "The candidate passage is merely on a similar topic or doctrine; it does not "
            "supply the specific proposition the query excerpt relies on."
        ),
    ),
)


@json_cache
def score_candidate(model: str, query: str, candidate: str, question_json: str) -> dict:
    """One TypeSafe call about one (query, candidate) pair: a noul, plus token usage."""
    # the SDK takes a question as its JSON dict, so the cached string decodes straight in
    question = json.loads(question_json)
    response = client.system_one(
        state={"query_excerpt": query, "candidate_passage": candidate},
        questions={"is_cited_source": question},
        model=model,
    )
    return {
        "noul": response.answers["is_cited_source"].noul,
        "input_tokens": response.usage.input_tokens or 0,
        "output_tokens": response.usage.output_tokens or 0,
    }


# Each of the 40 queries has 30 candidates, so re-ranking every shortlist means 1,200 independent
# calls — cheap enough to fire all at once with a thread pool instead of one after another.
pair_list = [(q, c) for q in queries for c in candidates[q]]
question_json = msgspec.json.encode(is_cited_source).decode()
with ThreadPoolExecutor(max_workers=12) as pool:
    results = pool.map(
        lambda p: score_candidate(
            TYPESAFE_MODEL, queries[p[0]], corpus[p[1]], question_json
        ),
        pair_list,
    )
pair_scores = {q: {} for q in queries}
for (q, c), result in zip(pair_list, results):
    pair_scores[q][c] = result

reranked = {
    q: sorted(candidates[q], key=lambda c: -pair_scores[q][c]["noul"]) for q in queries
}


def chart_before_after(
    runs: dict[str, dict[str, list[str]]], thresholds: list[int]
) -> None:
    """Grouped bar chart: how often the correct passage lands in the top N, for each run."""
    import numpy as np
    import matplotlib.pyplot as plt

    labels = list(runs)
    colors = [BLUE, GREEN]

    def share_in_top(rankings, k):
        return sum(
            gold_rank(rankings[q], golds[q]) in range(1, k + 1) for q in queries
        ) / len(queries)

    fig, ax = plt.subplots(figsize=(6.5, 3.6), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    x = np.arange(len(thresholds))
    width = 0.35
    for i, (label, rankings) in enumerate(runs.items()):
        shares = [share_in_top(rankings, k) for k in thresholds]
        offset = (i - (len(labels) - 1) / 2) * width
        bars = ax.bar(x + offset, shares, width * 0.92, color=colors[i], label=label)
        ax.bar_label(
            bars,
            labels=[f"{s * 100:.0f}%" for s in shares],
            padding=3,
            color=INK2,
            fontsize=8.5,
        )

    ax.set_xticks(x, [f"top {k}" for k in thresholds])
    ax.set_ylim(0, 1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(
        "How often the correct passage lands near the top",
        loc="left",
        color=INK,
        fontsize=11,
    )
    ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="upper left")
    plt.tight_layout()
    display(fig)
    plt.close(fig)


chart_before_after(
    {"Fast search": candidates, "+ TypeSafe re-rank": reranked}, [1, 5, 10]
)

calls = [pair_scores[q][c] for q in queries for c in pair_scores[q]]
input_tokens = sum(call["input_tokens"] for call in calls)
output_tokens = sum(call["output_tokens"] for call in calls)
cost = input_tokens / 1_000_000 * PRICE[0] + output_tokens / 1_000_000 * PRICE[1]
print(
    f"{len(calls)} TypeSafe calls used {input_tokens:,} input and "
    f"{output_tokens:,} output tokens, costing ${cost:.4f}."
)
1200 TypeSafe calls used 1,536,002 input and 25,200 output tokens, costing $0.0645.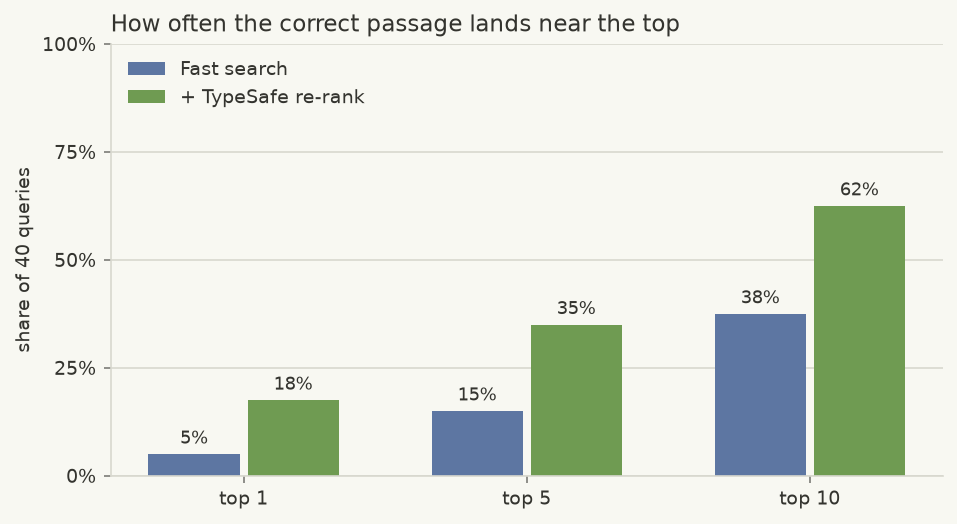
재랭킹은 정답을 최상단으로 이동시킵니다
차트는 고속 검색과 고속 검색+재랭킹을 세 가지 임계값에서 비교합니다. 재랭킹은 모든 임계값에서 올바른 문서가 상위권으로 올라오도록 조정합니다:
- Top 1 — 5% → 18%
- Top 5 — 15% → 35%
- Top 10 — 38% → 62%
보고된 토큰 수와 비용은 40개의 짧은 목록을 재순위 매기기 위해 사용된 1,200개의 TypeSafe 호출 전부를 포함합니다.
각 CLERC 행에는 하나의 정답 문장과 20개의 부정적 문장이 포함되어 있습니다. 이 안내서는 170개 행의 문장을 하나의 공유 코퍼스로 모읍니다. 40개의 평가 쿼리 각각에 대해 BM25는 해당 행에 제공된 20개의 부정적 문장뿐만 아니라 전체 코퍼스에서 30개의 후보를 선택합니다. TypeSafe는 선택된 각 후보에 대해 쿼리를 읽고, 이 30개 문장을 다시 랭킹합니다.
이 가이드는 명확성을 위해 한 쌍당 하나의 질문을 했습니다. 실제 애플리케이션은 한 번의 호출에서 동일한 쌍에 대해 여러 질문을 합니다. 방법은 병렬 질문 요리책과 추측성 Fan-Out 패턴을 참조하세요.
다음 단계
TypeSafe의 다른 문서에서도 동일한 빌딩 블록이 등장합니다:
- Noul, TypeSafe가 예/아니오 질문을 점수로 변환하는 방식에 대해.
- Speculative Fan-Out, 단일 호출에서 하나의 문서에 대해 여러 질문을 던지는 방식.
- Line-by-line Search, 키워드가 아닌 의미에 기반하여 코퍼스를 검색하는 또 다른 방법.