 JevCode
자동 연구 기능 발견
TypeSafe 질문을 제안하고, 자유 텍스트를 수치형 특징으로 변환하며, 모델 오차를 활용하여 지도형 CatBoost 회귀 모델을 개선하는 자동 연구 루프를 실행합니다.
이 문서는 en에서 기계 번역되었으며 교정되지 않았습니다. 빠른 참고용으로만 사용하세요.

TypeSafe 질문은 자유 텍스트를 지도식 CatBoost 모델용 수치형 특징으로 변환하며, 자동 연구 루프를 사용하여 이를 발견합니다.
CatBoost는 숫자의 표가 필요하며, 시음 기록은 숫자의 표가 아닙니다. 이 쿡북은 시음 기록에 대한 질문들로 이 표를 구성하며, 그중 아무것도 수작업으로 작성되지 않습니다. LLM이 질문을 제안하면, TypeSafe가 각 행에 대해 이에 답변하고, CatBoost가 그 답변들을 바탕으로 학습합니다. 자동 연구 부분은 그 다음에 이루어집니다: CatBoost는 자신이 사용한 질문들과 여전히 잘못 분류된 행들을 보고하며, 다음 제안 호출은 이 보고서를 읽으며, 루프가 다시 실행됩니다.
최종적으로 라벨링된 텍스트를 참조할 수 있는 루프, 라운드별 홀드아웃 오류의 곡선, 그리고 최종 모델이 가장 많이 사용한 질문들의 표를 얻게 됩니다.
tasting note
    |
    v
38 TypeSafe answers
    |-- 29 score questions x 2 columns = 58
    |     expected rubric level + answer uncertainty
    `--  9 noul questions  x 1 column  =  9
          probability true
    |
    v
67 numeric columns --> CatBoost --> predicted critic score
                                     held-out RMSE: 1.77 points
점수 기반 답변은 두 개의 열로 구성됩니다: 답변이 가리키는 평균 수준과, 그 평균 주변에서의 분포 정도입니다. 노울 기반 답변은 하나의 확률값이므로 하나의 열로 표현됩니다.
데이터는 2,000개의 와인 리뷰로 구성됩니다: 테이스팅 노트가 입력되고, 비평가의 점수가 80-100 척도에서 출력됩니다. RMSE는 비평가 점수 단위의 예측 오차를 측정하며, 오차가 클수록 더 큰 패널티를 받고, 낮을수록 더 좋습니다. 아래 표의 모든 숫자는 모델이나 루프가 한 번도 본 적 없는 800개의 리뷰에서 유래했습니다.
| 노트가 점수가 되는 방식 | RMSE |
|---|---|
| 학습 행의 평균 점수 예측 | 3.09 |
| 동일한 CatBoost, 노트를 단어 빈도로 읽기 | 2.47 |
| TypeSafe에 점수 자체 요청, 재스케일링 및 이동 | 2.15 |
| 한 번의 제안 호출에서 18개 질문, 루프 없음 | 1.87 |
| 루프 5라운드 후 38개 질문 | 1.77 |
마지막 두 행은 루프입니다. 아직 근거가 없는 제안 호출 한 번으로 1.87에 도달합니다. 자신의 가장 나쁜 예측을 읽는 네 번의 추가 라운드를 거치면 1.77이 됩니다. 대부분의 이득은 첫 번째 호출에서 발생하며, 그 이후 네 번의 라운드가 추가하는 양은 아래에서 더 자세히 측정됩니다.
팁 — 이 노트북을 더 활용하거나 다른 문제에 적용하고 싶으신가요? 다음 단계를 확인하세요.
from __future__ import annotations
import json
import os
import random
import textwrap
import urllib.request
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from time import perf_counter
from typing import NamedTuple
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from catboost import CatBoostRegressor
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Noul, NoulCriteria, Score, TypeSafeClient
matplotlib.use("Agg") # headless render
TYPESAFE_MODEL = "jev-1.12"
FOLDS, REPEATS = 5, 3 # repeats steady the error at this sample size
CATBOOST = dict(
iterations=400,
depth=4,
learning_rate=0.05,
loss_function="RMSE",
verbose=0,
random_seed=0,
thread_count=1,
allow_writing_files=False,
)
client = TypeSafeClient(
# keyless kernels replay the cache
api_key=os.environ.get("TYPESAFE_API_KEY", "cache-only"),
base_url=os.environ.get("TYPESAFE_ENDPOINT"),
timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
# ----------------------------------------------------------------- the specification
INTENSITY_LEVELS = [
"Not present in this note at all",
"Barely present - mentioned once, in passing",
"Present at a moderate level",
"Present strongly - the note dwells on it",
"Dominant - the note is largely about this",
]
PRESENCE_CRITERIA = NoulCriteria(
true="The note states this or clearly implies it",
false="The note gives no indication of this",
)
# Asking for the score outright: ten quality bands, rescaled onto the 80-100 critic scale.
SCORE_LEVELS = [
"Faulty or unpleasant - the note is mostly criticism",
"Barely acceptable - drinkable, with nothing to recommend it",
"Simple and sound - correct, plain, forgettable",
"Pleasant everyday wine - some appeal, little depth",
"Good - clear varietal character, well made",
"Very good - balanced, with something to say",
"Excellent - complex and structured",
"Outstanding - depth and length, built to age",
"Superb - among the best of its type",
"Profound - the note treats it as exceptional",
]
# Structured output requires every property in `required`, so unused fields come back empty.
PROPOSAL_SCHEMA = {
"type": "object",
"properties": {
"actions": {
"type": "array",
"items": {
"type": "object",
"properties": {
"op": {"type": "string", "enum": ["add", "revise", "drop"]},
"target": {"type": "string"},
"name": {"type": "string"},
"kind": {"type": "string", "enum": ["intensity", "presence"]},
"question": {"type": "string"},
},
"required": ["op", "target", "name", "kind", "question"],
"additionalProperties": False,
},
}
},
"required": ["actions"],
"additionalProperties": False,
}
PROPOSALS = 18 # actions the proposer may return per round
# The one string that knows this is about wine. Point it at your own label and text.
PROPOSER_TASK = f"""You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to {PROPOSALS} actions. Each action is one of:
- {{"op": "add", "target": "", "name": ..., "kind": ..., "question": ...}}
A new feature.
- {{"op": "revise", "target": <name of an existing feature>, "name": ..., "kind": ...,
"question": ...}}
Replace that feature's question with better wording. Use this when a feature measures the
right thing badly: too narrow, too vague, or worded so nearly every note answers the same.
- {{"op": "drop", "target": <name of an existing feature>, "name": "", "kind": "intensity",
"question": ""}}
Remove a feature that is not earning its place.
`kind` is "intensity" for something with a degree, or "presence" for a yes/no fact.
`question` is what gets asked about one tasting note.
An "intensity" question is graded against this fixed five-level rubric, so word it so that the
levels make sense:
{chr(10).join(f" {i}. {level}" for i, level in enumerate(INTENSITY_LEVELS))}
A "presence" question is answered as the probability that it is true of the note.
Good features can be judged from the note's own words, vary from note to note, and carry
information about quality that the other features do not. Reviewers describe structure, fruit,
oak, length, complexity, and drinkability, and they also signal quality through word choice."""
class Split(NamedTuple):
"""The rows, their labels, and which half the loop is allowed to read."""
notes: list[str]
scores: np.ndarray
dev: np.ndarray
test: np.ndarray
# ----------------------------------------------------------------- the data
WINEMAG_CSV = (
"https://huggingface.co/datasets/GroNLP/ik-nlp-22_winemag/resolve/"
"90eb39f35fc64e556fc17f06d4137a4a69ec3297/train.csv"
)
@json_cache
def load_slice(n_dev: int, n_test: int, seed: int) -> dict:
"""Fetch the pinned CSV and take a seeded sample of note + score, one row per note."""
import csv
import io
request = urllib.request.Request(
WINEMAG_CSV, headers={"User-Agent": "typesafe-cookbook/1.0"}
)
with urllib.request.urlopen(request, timeout=300) as response:
text = response.read().decode()
rows, seen = [], set()
for row in csv.DictReader(io.StringIO(text)): # a few notes repeat verbatim
if not row["description"] or not row["points"] or row["description"] in seen:
continue
seen.add(row["description"])
rows.append((row["description"], float(row["points"])))
random.Random(seed).shuffle(rows)
picked = rows[: n_dev + n_test]
return {"notes": [r[0] for r in picked], "points": [r[1] for r in picked]}
def example_rows(split: Split, out_of_fold: np.ndarray | None, n: int) -> list[int]:
"""Select representative dev rows for a proposer round."""
dev = split.dev
if out_of_fold is None:
ranked = dev[np.argsort(split.scores[dev], kind="stable")]
return [int(ranked[round(q * (len(ranked) - 1))]) for q in np.linspace(0, 1, n)]
error = np.abs(split.scores[dev] - out_of_fold)
order = np.argsort(-error, kind="stable")
worst = [int(dev[i]) for i in order[: n // 2]]
best = [int(dev[i]) for i in order[len(order) - (n - n // 2) :]]
return worst + best
def example_block(
rows: list[int],
split: Split,
out_of_fold: np.ndarray | None,
previous: np.ndarray | None = None,
) -> str:
"""Format selected rows for the proposer."""
if out_of_fold is None:
head = "Example notes, with the score each one was given:"
body = [f"- scored {split.scores[r]:.0f}: {split.notes[r]}" for r in rows]
return head + "\n" + "\n".join(body)
head = (
"Dev notes, worst-predicted first. The first half is where your current questions "
"miss by the most and the second half is where they are already right, so what "
"separates the halves is what the questions have not captured."
)
if previous is not None:
head += (
" Each line also carries what the previous round predicted, so you can see which "
"notes your last batch of questions moved."
)
body = []
for r in rows:
line = f"- scored {split.scores[r]:.0f}, predicted {out_of_fold[r]:.1f}"
if previous is not None:
line += f" (last round {previous[r]:.1f})"
body.append(f"{line}: {split.notes[r]}")
return head + "\n" + "\n".join(body)
def load_split(n_dev: int, n_test: int, seed: int = 0) -> Split:
# keyword, because the cache key is the function name plus how each argument was spelled
data = load_slice(n_dev, n_test, seed=seed)
return Split(
notes=data["notes"],
scores=np.array(data["points"]),
dev=np.arange(n_dev),
test=np.arange(n_dev, n_dev + n_test),
)
# ----------------------------------------------------------------- step 1: propose
def proposal_prompt(examples: str, feedback: str, accepted: list[dict]) -> str:
parts = [PROPOSER_TASK, "\n" + examples]
if accepted:
parts.append(
"\nThe features you have now. `add` must not duplicate one of these; `revise` and "
"`drop` refer to one by name:\n"
+ "\n".join(
f"- {f['name']} ({f['kind']}): {f['question']}" for f in accepted
)
)
if feedback:
parts.append("\nHow the model did with those features:\n" + feedback)
return "\n".join(parts)
@json_cache
def propose(model: str, round_index: int, prompt: str) -> dict:
"""One proposal call. Every number in `prompt` is rounded so a replay hits the cache."""
if model.startswith("claude"):
import anthropic
response = anthropic.Anthropic(
api_key=os.environ.get("ANTHROPIC_API_KEY", "cache-only")
).messages.create(
model=model,
max_tokens=16000,
output_config={
"effort": "medium",
"format": {"type": "json_schema", "schema": PROPOSAL_SCHEMA},
},
messages=[{"role": "user", "content": prompt}],
)
body = next(block.text for block in response.content if block.type == "text")
usage = [response.usage.input_tokens or 0, response.usage.output_tokens or 0]
else:
from openai import OpenAI
response = OpenAI(
api_key=os.environ.get("OPENAI_API_KEY", "cache-only")
).chat.completions.create(
model=model,
reasoning_effort="high",
max_completion_tokens=16000,
response_format={"type": "json_object"},
messages=[
{
"role": "user",
"content": prompt
+ "\n\nReply with JSON matching this schema:\n"
+ json.dumps(PROPOSAL_SCHEMA),
}
],
)
body = response.choices[0].message.content
usage = [response.usage.prompt_tokens, response.usage.completion_tokens]
return {"actions": json.loads(body)["actions"][:PROPOSALS], "usage": usage}
def slug(name: str, taken: set[str]) -> str:
"""Names become question ids and column labels, so keep them plain and unique."""
base = (
"".join(c if c.isalnum() else "_" for c in name.lower()).strip("_") or "feature"
)
candidate, n = base, 2
while candidate in taken:
candidate, n = f"{base}_{n}", n + 1
return candidate
def to_candidates(actions: list[dict], accepted: list[dict], round_index: int) -> tuple:
"""Split a round's actions into screenable candidates and a list of names to drop."""
live = {f["name"] for f in accepted}
drops = [a["target"] for a in actions if a["op"] == "drop" and a["target"] in live]
replacing = {
a["target"] for a in actions if a["op"] == "revise" and a["target"] in live
}
# a revision may keep the name it replaces, since that feature is on its way out
taken, candidates = live - replacing, []
for action in actions:
if action["op"] == "drop":
continue
if action["op"] == "revise" and action["target"] not in live:
continue # a revision of something that is not there
name = slug(action["name"], taken)
taken.add(name)
candidates.append(
{
"id": f"{name}@{round_index}", # unique, so earlier rounds keep their columns
"name": name,
"kind": action["kind"],
"question": action["question"],
"replaces": action["target"] if action["op"] == "revise" else "",
}
)
return candidates, drops
# ----------------------------------------------------------------- step 2: answer
def feature_questions(features: list[dict]) -> dict:
questions = {}
for feature in features:
if feature["kind"] == "intensity":
questions[feature["name"]] = Score(
instructions=feature["question"], criteria=INTENSITY_LEVELS
)
else:
questions[feature["name"]] = Noul(
instructions=feature["question"], criteria=PRESENCE_CRITERIA
)
return questions
@json_cache
def answer(model: str, note: str, features_json: str) -> dict:
"""One request per note; every question of the round rides it. Keeps every probability."""
features = json.loads(features_json)
started = perf_counter()
response = client.system_one(
state=note, questions=feature_questions(features), model=model
)
raw = {}
for feature in features:
got = response.answers[feature["name"]]
if feature["kind"] == "intensity":
raw[feature["name"]] = [
got.probabilities.get(i, 0.0) for i in range(len(INTENSITY_LEVELS))
]
else:
raw[feature["name"]] = [got.noul]
return {
"raw": raw,
"seconds": round(perf_counter() - started, 2),
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
def featurize(notes: list[str], features: list[dict]) -> dict:
"""Answer one question set for many notes: one request each, eight in flight."""
payload = json.dumps(features, sort_keys=True)
with ThreadPoolExecutor(max_workers=8) as pool:
results = list(
pool.map(lambda note: answer(TYPESAFE_MODEL, note, payload), notes)
)
return {
f["name"]: np.array([r["raw"][f["name"]] for r in results], dtype=float)
for f in features
}
def encode(feature: dict, probabilities: np.ndarray, mode: str) -> list[tuple]:
"""Turn one question's probabilities into named columns."""
name = feature["name"]
if feature["kind"] == "presence":
return [(name, probabilities[:, 0])] # one number is all there is
levels = np.arange(probabilities.shape[1])
mean = probabilities @ levels
if mode == "mean":
return [(name, mean)]
if mode == "mean_spread":
variance = probabilities @ (levels**2) - mean**2
return [(name, mean), (f"{name}_sd", np.sqrt(np.clip(variance, 0, None)))]
return [(f"{name}_p{i}", probabilities[:, i]) for i in levels]
def design(features: list[dict], answers_for: dict, mode: str) -> tuple:
"""Stack every feature's columns into one matrix, plus a label per column."""
columns, labels = [], []
for feature in features:
for label, column in encode(feature, answers_for[feature["id"]], mode):
columns.append(column)
labels.append(label)
return np.column_stack(columns), labels
def plain(features: list[dict]) -> list[dict]:
"""What goes on the wire and into the cache key: no id, no bookkeeping."""
return [
{"name": f["name"], "kind": f["kind"], "question": f["question"]}
for f in features
]
# ----------------------------------------------------------------- step 3: fit
def rmse(y: np.ndarray, p: np.ndarray) -> float:
return float(np.sqrt(np.mean((y - p) ** 2)))
def spearman(a: np.ndarray, b: np.ndarray) -> float:
"""Rank correlation: does the model order the wines the way the critic did?"""
ranks = (
np.argsort(np.argsort(a)).astype(float),
np.argsort(np.argsort(b)).astype(float),
)
return float(np.corrcoef(*ranks)[0, 1])
def folds(y: np.ndarray, k: int, seed: int) -> list[np.ndarray]:
"""Label-stratified k-fold: sort by the label with a seeded tiebreak, then deal off the top."""
rng = np.random.default_rng(seed)
order = np.lexsort((rng.random(len(y)), y))
return [np.sort(order[i::k]) for i in range(k)]
def cross_validate(X: np.ndarray, y: np.ndarray) -> tuple[np.ndarray, float]:
out_of_fold = np.zeros((REPEATS, len(y)))
for repeat in range(REPEATS):
for fold in folds(y, FOLDS, seed=repeat):
train = np.setdiff1d(np.arange(len(y)), fold)
model = CatBoostRegressor(**CATBOOST).fit(X[train], y[train])
out_of_fold[repeat, fold] = model.predict(X[fold])
scores = [rmse(y, out_of_fold[repeat]) for repeat in range(REPEATS)]
return out_of_fold.mean(axis=0), float(np.mean(scores))
def importances(X: np.ndarray, y: np.ndarray) -> np.ndarray:
return CatBoostRegressor(**CATBOOST).fit(X, y).get_feature_importance()
def paired_gain(y: np.ndarray, before: np.ndarray, after: np.ndarray) -> tuple:
"""Bootstrap the paired held-out RMSE change."""
squared = ((y - before) ** 2, (y - after) ** 2)
rng = np.random.default_rng(0)
drawn = []
for _ in range(2000):
rows = rng.integers(0, len(y), len(y))
drawn.append(
np.sqrt(squared[1][rows].mean()) - np.sqrt(squared[0][rows].mean())
)
drawn = np.array(drawn)
return (
rmse(y, after) - rmse(y, before),
float(np.percentile(drawn, 2.5)),
float(np.percentile(drawn, 97.5)),
)
def fit_predict(X: np.ndarray, split: Split) -> np.ndarray:
model = CatBoostRegressor(**CATBOOST).fit(X[split.dev], split.scores[split.dev])
return model.predict(X[split.test])
def fit_predict_text(split: Split) -> np.ndarray:
"""The reference arm: the same model, handed the note instead of the columns."""
from catboost import Pool
raw = np.array([[note] for note in split.notes], dtype=object)
model = CatBoostRegressor(**CATBOOST).fit(
Pool(raw[split.dev], split.scores[split.dev], text_features=[0])
)
return model.predict(Pool(raw[split.test], text_features=[0]))
def evaluate(
features: list[dict], answers_for: dict, split: Split, mode: str
) -> tuple[np.ndarray, float]:
"""Cross-validated error on the dev rows for one candidate question set."""
X, _ = design(features, answers_for, mode)
return cross_validate(X[split.dev], split.scores[split.dev])
def swap_in(accepted: list[dict], feature: dict) -> list[dict] | None:
"""The accepted set with `feature` in place of the one it revises, or None if it is gone."""
at = next(
(i for i, f in enumerate(accepted) if f["name"] == feature["replaces"]), None
)
if at is None:
return None
trial = list(accepted)
trial[at] = {k: feature[k] for k in ("id", "name", "kind", "question")}
return trial
def try_change(
trial: list[dict],
accepted: list[dict],
cv: float,
answers_for: dict,
split: Split,
mode: str,
tolerance: float,
) -> tuple[list[dict], float, str, bool]:
"""Refit with the change and keep it only if the dev error improves. No API calls."""
_, cv_trial = evaluate(trial, answers_for, split, mode)
if cv_trial <= cv + tolerance:
return trial, cv_trial, f"CV {cv:.3f} -> {cv_trial:.3f}", True
return accepted, cv, f"would cost {cv_trial - cv:+.3f}", False
def owner_of(label: str, features: list[dict]) -> dict:
"""Which feature a column label belongs to - encodings suffix the name."""
exact = next((f for f in features if f["name"] == label), None)
if exact:
return exact
return next(f for f in features if label.startswith(f["name"] + "_"))
def importance_per_feature(
features: list[dict], labels: list[str], column_importances: np.ndarray
) -> dict:
"""Sum each question's CatBoost column importances.
Intensity questions can produce multiple model columns. Combining their normalized
importances gives one percentage share per question.
"""
total = {f["name"]: 0.0 for f in features}
for label, column_importance in zip(labels, column_importances):
total[owner_of(label, features)["name"]] += float(column_importance)
return total
def feedback_for(
history: list[float],
accepted: list[dict],
answers_for: dict,
split: Split,
mode: str,
out_of_fold: np.ndarray,
previous: np.ndarray | None,
) -> str:
"""The scoreboard the next proposal call reads. The notes themselves arrive separately,
through `example_block`. Numbers are rounded before they enter the prompt."""
X, labels = design(accepted, answers_for, mode)
dev, scores = split.dev, split.scores
by_name = importance_per_feature(accepted, labels, importances(X[dev], scores[dev]))
lines = ["Cross-validated RMSE in points so far, lower is better:"]
lines += [f" round {i + 1}: {v:.2f}" for i, v in enumerate(history)]
if previous is not None:
now, before = np.abs(scores[dev] - out_of_fold), np.abs(scores[dev] - previous)
better, worse = int((now < before - 0.1).sum()), int((now > before + 0.1).sum())
lines.append(
f"\nAgainst the previous round, {better} of the {len(dev)} dev notes are now "
f"predicted better by more than 0.1 points and {worse} are predicted worse."
)
lines.append(
"\nYour features, with importance as a percentage of the total and the spread of the "
"column across the dev rows. Low importance or low spread means the question is not "
"doing much; revise or drop it."
)
for feature in sorted(accepted, key=lambda f: -by_name.get(f["name"], 0.0)):
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
lines.append(
f" {feature['name']} ({feature['kind']}): "
f"{by_name.get(feature['name'], 0.0):.1f}% importance, "
f"spread {column[dev].std():.2f}"
)
return "\n".join(lines)
# ----------------------------------------------------------------- the loop itself
class Discovery(NamedTuple):
"""Artifacts returned by the discovery loop."""
accepted: list[dict] # the question set it ended with
answers_for: dict # feature id -> (rows x levels) probabilities
snapshots: list[list[dict]] # the set as it stood at the end of each round
history: list[float] # dev CV error after each round
batches: list[tuple] # what each round sent, for the request table
journal: list[tuple] # every action and what became of it
def run_loop(
split: Split,
proposer: str,
rounds: int,
examples: int,
mode: str,
min_spread: float,
tolerance: float,
) -> Discovery:
"""Run the propose, answer, fit, and feedback loop."""
shown = example_rows(split, None, examples) # round 1 has nothing predicted yet
out_of_fold = previous = None
got_from = Discovery([], {}, [], [], [], [])
accepted, answers_for = got_from.accepted, got_from.answers_for
snapshots, history = got_from.snapshots, got_from.history
batches, journal = got_from.batches, got_from.journal
feedback = ""
for round_index in range(1, rounds + 1):
block = example_block(shown, split, out_of_fold, previous)
actions = propose(
proposer, round_index, proposal_prompt(block, feedback, accepted)
)["actions"]
keep, drops = to_candidates(actions, accepted, round_index)
if keep: # one request per row, carrying every question this round proposed
batches.append((round_index, plain(keep)))
answers = featurize(split.notes, plain(keep))
for feature in keep:
answers_for[feature["id"]] = answers[feature["name"]]
for (
feature
) in keep: # an add goes in; importance says later whether it earned it
if feature["replaces"]:
continue
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
flat = float(column[split.dev].std()) < min_spread
journal.append(
(round_index, "flat" if flat else "add", feature["name"], "")
)
if not flat:
accepted.append(
{k: feature[k] for k in ("id", "name", "kind", "question")}
)
_, cv = evaluate(accepted, answers_for, split, mode)
trial_args = (answers_for, split, mode, tolerance)
for feature in [f for f in keep if f["replaces"]]: # every revision is tried
trial = swap_in(accepted, feature)
if trial is None: # it revises something an earlier round already dropped
journal.append(
(round_index, "stale", feature["name"], "target is gone")
)
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
what = "revise" if took else "reject"
journal.append(
(
round_index,
what,
feature["name"],
f"was {feature['replaces']}, {note}",
)
)
for name in drops: # and so is every drop
trial = [f for f in accepted if f["name"] != name]
if not trial:
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
journal.append((round_index, "drop" if took else "keep", name, note))
previous, (out_of_fold, cv) = (
out_of_fold,
evaluate(accepted, answers_for, split, mode),
)
history.append(cv)
snapshots.append(list(accepted))
feedback = feedback_for(
history, accepted, answers_for, split, mode, out_of_fold, previous
)
# next round reads the rows these questions get most wrong, and as many they get right
shown = example_rows(split, out_of_fold, examples)
report(round_index, keep, drops, journal, accepted, cv)
return got_from
def report(
round_index: int,
keep: list[dict],
drops: list[str],
journal: list[tuple],
accepted: list[dict],
cv: float,
) -> None:
"""One block per round: the counts, the names it added, then everything with a number."""
revised = sum(1 for f in keep if f["replaces"])
print(
f"round {round_index}: {len(keep) - revised} add, {revised} revise, "
f"{len(drops)} drop"
)
this_round = [j for j in journal if j[0] == round_index]
added = [name for _, what, name, _ in this_round if what == "add"]
if added:
print(
textwrap.fill(
", ".join(added),
88,
initial_indent=" added ",
subsequent_indent=" " * 10,
)
)
for _, what, name, note in this_round: # everything carrying a number of its own
if what != "add":
print(f" {what:<7}{name:<34}{note}")
print(f" -> {len(accepted)} features, dev CV RMSE {cv:.3f}\n")
# ----------------------------------------------------------------- asking for the score
@json_cache
def ask_score(model: str, note: str) -> dict:
"""One `Score` over ten quality bands, read as a level and rescaled to 80-100."""
response = client.system_one(
state=note,
questions={
"quality": Score(
instructions=(
"Judging only by what this tasting note says, how good is the wine?"
),
criteria=SCORE_LEVELS,
)
},
model=model,
)
got = response.answers["quality"]
top = len(SCORE_LEVELS) - 1
expected = sum(k * v for k, v in got.probabilities.items())
return {
# level 0 is the bottom of the critic's scale, level 9 the top
"expected": 80.0 + 20.0 * expected / top,
"picked": 80.0 + 20.0 * got.score / top,
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
# ----------------------------------------------------------------- charts
SURFACE, INK, INK2, MUTED = "#fcfcfb", "#0b0b0b", "#52514e", "#898781"
GRID, AXIS, BLUE, ORANGE = "#e1e0d9", "#c3c2b7", "#2a78d6", "#eb6834"
def style(ax) -> None:
ax.set_facecolor(SURFACE)
for side in ("top", "right"):
ax.spines[side].set_visible(False)
for side in ("left", "bottom"):
ax.spines[side].set_color(AXIS)
ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
ax.set_axisbelow(True)
def polarity(feature: dict, answers_for: dict, split: Split) -> float:
"""Rank correlation between a question's answer and the critic score, on the dev rows.
Positive means a higher answer goes with a better review, negative the opposite. It is
what orders the rows of the feature map, so the map reads as a gradient that flips.
"""
column = encode(feature, answers_for[feature["id"]], "mean")[0][1]
return spearman(column[split.dev], split.scores[split.dev])
def reviews_heatmap(
plt,
questions: list[dict],
answers_for: dict,
split: Split,
rows: tuple,
):
"""Compare held-out reviews across the discovered questions, best-signal first.
Rows arrive sorted from the questions that rise with the score to the ones that fall with
it, so a row above the divider shades left to right and a row below it shades right to
left.
"""
def value_of(feature: dict, row: int) -> float:
return float(encode(feature, answers_for[feature["id"]], "mean")[0][1][row])
signs = [polarity(question, answers_for, split) for question in questions]
flip = next((i for i, s in enumerate(signs) if s < 0), len(questions))
raw = np.array(
[[value_of(question, row) for row in rows] for question in questions]
)
normalized = np.array(
[
values / (4 if question["kind"] == "intensity" else 1)
for question, values in zip(questions, raw)
]
)
cmap = matplotlib.colors.LinearSegmentedColormap.from_list(
"typesafe_heat", [SURFACE, "#f7c7ad", ORANGE]
)
fig, ax = plt.subplots(
figsize=(9.5, 1.8 + 0.58 * len(questions)), facecolor=SURFACE
)
image = ax.imshow(normalized, aspect="auto", cmap=cmap, vmin=0, vmax=1)
row_labels = []
for question, sign in zip(questions, signs):
kind = "score" if question["kind"] == "intensity" else "noul"
prefix = f"{sign:+.2f} ({kind}) "
lines = textwrap.wrap(
" ".join(question["question"].split()),
width=52,
max_lines=2,
placeholder="...",
break_long_words=False,
break_on_hyphens=False,
)
row_labels.append(prefix + (f"\n{' ' * len(prefix)}").join(lines))
column_labels = [
f"#{i}\n{split.scores[row]:.0f} points\n{' '.join(split.notes[row].split())[:15]}..."
for i, row in enumerate(rows, 1)
]
ax.set_yticks(np.arange(len(questions)), row_labels)
ax.set_xticks(np.arange(len(rows)), column_labels)
ax.tick_params(
axis="x", top=True, labeltop=True, bottom=False, labelbottom=False, pad=8
)
ax.tick_params(axis="y", labelsize=8.5)
for side in ax.spines.values():
side.set_visible(False)
ax.set_xticks(np.arange(-0.5, len(rows), 1), minor=True)
ax.set_yticks(np.arange(-0.5, len(questions), 1), minor=True)
ax.grid(which="minor", color=SURFACE, linewidth=2)
ax.tick_params(which="minor", bottom=False, left=False)
for i, question in enumerate(questions):
for j, value in enumerate(raw[i]):
label = (
f"{value:.1f}" if question["kind"] == "intensity" else f"{value:.2f}"
)
color = SURFACE if normalized[i, j] > 0.58 else INK2
ax.text(j, i, label, ha="center", va="center", color=color, fontsize=8)
# the line where the questions stop rising with the score and start falling with it
if 0 < flip < len(questions):
ax.axhline(flip - 0.5, color=INK, linewidth=1.2)
ax.annotate(
"a higher answer means a worse review, below this line",
(len(rows) - 0.5, flip - 0.5),
xytext=(-4, 5),
textcoords="offset points",
va="bottom",
ha="right",
color=INK2,
fontsize=8.5,
)
colorbar = fig.colorbar(image, ax=ax, fraction=0.025, pad=0.025)
colorbar.set_ticks([0, 0.5, 1])
colorbar.set_label("normalized answer", color=INK2, fontsize=8.5)
colorbar.ax.tick_params(labelsize=8, colors=INK2)
fig.suptitle(
"Every question, on five held-out reviews from worst to best",
x=0.01,
y=0.995,
ha="left",
color=INK,
fontsize=11,
)
fig.text(
0.01,
0.972,
"sorted by how the answer moves with the score, so each row above the line shades "
"left to right and each row below it shades the other way",
color=MUTED,
fontsize=9,
)
fig.text(
0.01,
0.005,
"Row labels lead with the rank correlation between that question's answer and the "
"critic score. Cell text is each question's native scale: score 0-4, noul 0-1.",
color=MUTED,
fontsize=8.5,
)
return fig
def rounds_chart(
plt, curve: list[tuple], history: list[float], n_test: int, gain: tuple
):
"""Dev error and held-out error per round. The trend is the point, not the gap."""
rounds = list(range(1, len(curve) + 1))
values = [v for _, v in curve]
fig, ax = plt.subplots(figsize=(7, 3.9), facecolor=SURFACE)
style(ax)
ax.grid(axis="y", color=GRID, linewidth=0.8)
# each dev fold trains on four fifths of the rows, so the dev line sits the higher of the two
ax.fill_between(rounds, history, values, color=GRID, alpha=0.75, linewidth=0)
ax.plot(
rounds,
history,
marker="o",
color=BLUE,
linewidth=2,
linestyle="--",
label="dev, cross-validated - what the loop optimises",
)
ax.plot(
rounds,
values,
marker="o",
color=ORANGE,
linewidth=2,
label="held out - what that actually buys",
)
# label each point on the outside of the pair, so neither line crowds its own numbers
for x, dev_value, test_value in zip(rounds, history, values):
for value, other in ((dev_value, test_value), (test_value, dev_value)):
ax.annotate(
f"{value:.2f}",
(x, value),
textcoords="offset points",
xytext=(0, 8 if value >= other else -16),
ha="center",
color=INK2,
fontsize=8.5,
)
ax.set_xticks(
rounds, [f"round {x}\n{n} features" for x, (n, _) in zip(rounds, curve)]
)
ax.set_ylabel("RMSE in points (lower is better)", color=INK2, fontsize=9)
# tight around the two lines: the whole finding lives inside 0.15 of a point
low, high = min(values + history), max(values + history)
ax.set_ylim(low - 0.10, high + 0.05)
difference, low_ci, high_ci = gain
ax.set_title(
f"{len(rounds)} rounds of the loop, scored on {n_test} held-out reviews",
loc="left",
color=INK,
fontsize=11,
pad=20,
)
# the number the chart is really about: is the held-out move bigger than the noise?
ax.text(
0,
1.015,
f"round 1 to round {len(rounds)}, held out: {difference:+.3f} points, "
f"95% CI [{low_ci:+.3f}, {high_ci:+.3f}]",
transform=ax.transAxes,
color=MUTED,
fontsize=9,
)
ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="lower left")
return fig설정
pip install anthropic openai catboost numpy matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/그리고 TYPESAFE_API_KEY와 ANTHROPIC_API_KEY를 설정합니다. 모든 API 호출은 쿡북과 함께 제공되는 json_cache.json에 캐싱되므로, 다시 렌더링하면 아무것도 호출하지 않고도 이 숫자를 재생합니다. 다시 live로 실행하려면 해당 캐시를 삭제하세요. 이 숫자들은 2026-08-03 기준 TypeSafe jev-1.12 및 claude-sonnet-5에서 가져온 것입니다. propose()에는 gpt-5.6-luna를 위한 두 번째 분기가 있지만, 이는 실행되지 않았습니다.
첫 번째 코드 셀은 전체 구현을 담고 있습니다: API 호출, 인코딩, 지표, 차트 스타일 등. 이 파일이 단독으로 실행되도록 하기 위해 여기에 배치되었으며, 문서 사이트에서는 이를 숨깁니다. 처음 읽을 때는 건너뛰어도 됩니다 — 레시피는 그 아래에서 시작됩니다.
N_DEV, N_TEST = 1200, 800  # the loop reads dev labels only; test is scored once
ROUNDS = 5  # a round answers questions for all 2,000 rows: 2,000 requests
PROPOSER = "claude-sonnet-5"  # or "gpt-5.6-luna"; the cache holds the Anthropic run
EXAMPLES = 60  # dev notes the proposer reads per round, half of them its worst misses
MIN_SPREAD = 0.05  # a column this flat cannot separate anything, so it is not kept
CHANGE_TOLERANCE = 0.0  # a revision or drop has to improve dev error, not just not hurt
ENCODING = "mean_spread"  # a score answer becomes two columns: its mean and spread

split = load_split(N_DEV, N_TEST, seed=0)
NOTES, SCORES, DEV, TEST = split.notes, split.scores, split.dev, split.test

print(
    f"{len(DEV)} dev rows, {len(TEST)} held out; scores run "
    f"{SCORES.min():.0f}-{SCORES.max():.0f}, mean {SCORES.mean():.2f}, sd {SCORES.std():.2f}"
)
print(f"\none of the notes:\n{NOTES[0]}")
1200 dev rows, 800 held out; scores run 80-98, mean 88.73, sd 3.17
one of the notes:
A Champagne that is very much wine. The structure and the richness are just right for a food wine, showing ripe acidity, flavors of plums and apricots, and balancing these primary fruits with a dense, complex structure that takes in yeast, maturity and a tight apple skin finish.루프는 2,000행 중 동일한 1,200행(개발용 행)을 반복해서 읽으며, 해당 1,200개의 점수를 예측하는 데 도움이 되는 질문만 유지합니다. 동일한 행에서 점수를 매기는 것은 주로 루프가 해당 행에 얼마나 잘 적합되었는지를 측정하게 되므로, 나머지 800행은 제외해 두었다가 마지막에 한 번만 점수를 매깁니다.
두 가지 질문 유형
제안된 질문은 두 가지 유형 중 하나이며, 유형에 따라 반환되는 번호가 결정됩니다.
- **
intensity**는Score로 변환되며, 이는 정도(degree)를 기준으로 하는 모든 항목에 적용됩니다. 아래에 나열된 다섯 가지 수준은 평균 수준을 나타내므로, “중간”과 “강하게” 사이에 위치한 참고 사항은 두 수준 사이에 출력됩니다. - **
presence**는Noul로 변환되며, 이는 단층의 명칭 여부처럼 예/아니오로 판단할 수 있는 사실에 적용됩니다. 해당 열은 그 확률 값을 나타냅니다.
방법
questions <- {}
repeat for each round:
    notes  <- round 1 ? 60 dev notes across the score range
                      : the 30 worst-predicted dev notes + the 30 best,
                        each with its score, this prediction and the last
    actions <- LLM(brief, questions, notes, importance and error so far)
    answers[q] <- TypeSafe(note, all new questions of this round) for every row
    for each added q:      keep it unless its column is flat
    for each revised q:    refit; keep the change only if dev error drops
    for each dropped q:    refit; drop it only if dev error drops
    out_of_fold <- k-fold CatBoost on the columns   # judges, and picks next round's notes
답변되기 전에 질문은 필터링되지 않습니다. 한 라운드의 모든 질문은 동일한 요청으로 전송되므로, 하나의 추가 질문은 요청 수를 늘리지 않습니다. 10개 행 중 하나의 행에 적용되는 질문은 제안자가 읽는 60개의 노트에서无用해 보일 수 있지만, 여전히 전체 세트에서 가장 유용한 열이 됩니다.
k-fold는 개발 행을 k개로 나누고 나머지 부분으로 학습된 모델로 각 부분을 예측하는 것을 의미합니다. 이러한 예측은 세 가지 역할을 수행합니다: 모든 수정과 삭제를 평가하고, 다음 라운드에서 읽을 노트를 선택하며, 제안자가 자신의 질문 중 어떤 것이 도움이 되었는지, 이전 라운드 대비 얼마나 변화했는지를 알려줍니다.
print("every intensity question is graded on these five levels:\n")
for i, level in enumerate(INTENSITY_LEVELS):
    print(f"  {i}. {level}")
print("\nevery presence question is judged true or false against these:\n")
print(f"  true:  {PRESENCE_CRITERIA['true']}")
print(f"  false: {PRESENCE_CRITERIA['false']}")
print("\nthe brief the proposer works from:\n")
print("\n".join(PROPOSER_TASK.splitlines()[:6]) + "\n  ...")
every intensity question is graded on these five levels:
0. Not present in this note at all
1. Barely present - mentioned once, in passing
2. Present at a moderate level
3. Present strongly - the note dwells on it
4. Dominant - the note is largely about this
every presence question is judged true or false against these:
true: The note states this or clearly implies it
false: The note gives no indication of this
the brief the proposer works from:
You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to 18 actions. Each action is one of:
...자동 연구 루프
run_loop는 모든 5라운드를 실행하며 각 라운드마다 블록을 출력합니다. 추가된 질문은 즉시 반영됩니다: 해당 질문의 답변은 이미 조회되었으며, 그 중요도는 나중에 이 질문을 한 가치가 있었는지 여부를 보여줍니다. 수정이나 삭제는 모델이 이미 사용하고 있는 열을 제거하므로, 각각은 먼저 시도됩니다: 변경 사항을 반영하여 재피팅하고, 개발 오차가 감소하는 경우에만 유지합니다. 재피팅은 API 호출 비용을 발생시키지 않으므로, 변경 사항을 시도하고 거부하는 것은 무료입니다.
run = run_loop(
    split, PROPOSER, ROUNDS, EXAMPLES, ENCODING, MIN_SPREAD, CHANGE_TOLERANCE
)
accepted, answers_for = run.accepted, run.answers_for
snapshots, history = run.snapshots, run.history
round 1: 18 add, 0 revise, 0 drop
added complexity, fruit_intensity, tannin_structure, acidity_intensity,
oak_intensity, finish_length, balance_harmony, aging_potential,
positive_superlative_language, negative_critical_language,
drinkability_easiness, body_richness, sweetness_level, texture_descriptors,
earthy_savory_notes, flaw_or_defect_mentioned,
single_vineyard_or_prestige_signal, varietal_blend_detail
-> 18 features, dev CV RMSE 1.903
round 2: 5 add, 3 revise, 3 drop
added power_concentration_language, flavor_distinctiveness, generic_fruit_language,
candied_artificial_flavor, rustic_authentic_character
reject oak_dominance was oak_intensity, would cost +0.005
revise negative_critical_language was negative_critical_language, CV 1.897 -> 1.894
revise single_vineyard_or_prestige_signalwas single_vineyard_or_prestige_signal, CV 1.894 -> 1.881
keep finish_length would cost +0.009
keep texture_descriptors would cost +0.001
keep varietal_blend_detail would cost +0.023
-> 23 features, dev CV RMSE 1.881
round 3: 7 add, 2 revise, 1 drop
added elegance_finesse_language, minerality_precision_language,
hedged_qualified_praise, underripe_green_character,
reviewer_overall_verdict_strength, unusual_or_funky_descriptor_valence,
botrytis_or_special_winemaking_signal
revise negative_critical_language was negative_critical_language, CV 1.868 -> 1.864
revise finish_quality was finish_length, CV 1.864 -> 1.861
keep candied_artificial_flavor would cost +0.014
-> 30 features, dev CV RMSE 1.861
round 4: 5 add, 2 revise, 3 drop
added excess_or_imbalance_signal, descriptive_detail_density,
critic_enthusiasm_confidence, savory_food_wine_seriousness,
note_overall_tone_positivity
revise rustic_authentic_character was rustic_authentic_character, CV 1.843 -> 1.838
reject hedged_qualified_praise was hedged_qualified_praise, would cost +0.014
keep botrytis_or_special_winemaking_signalwould cost +0.011
keep candied_artificial_flavor would cost +0.009
keep unusual_or_funky_descriptor_valencewould cost +0.010
-> 35 features, dev CV RMSE 1.838
round 5: 4 add, 2 revise, 8 drop
added structural_seriousness, youthful_tension_signal, surface_prettiness_vs_depth,
price_value_signal
reject unconventional_character_as_virtuewas rustic_authentic_character, would cost +0.010
revise flavor_distinctiveness was flavor_distinctiveness, CV 1.849 -> 1.843
keep candied_artificial_flavor would cost +0.002
keep botrytis_or_special_winemaking_signalwould cost +0.003
keep hedged_qualified_praise would cost +0.006
keep excess_or_imbalance_signal would cost +0.005
drop underripe_green_character CV 1.843 -> 1.840
keep unusual_or_funky_descriptor_valencewould cost +0.002
keep texture_descriptors would cost +0.001
keep generic_fruit_language would cost +0.000
-> 38 features, dev CV RMSE 1.840자체 데이터에 포인트팅하기
PROPOSER_TASK는 와인을 언급하는 유일한 문자열이며, featurize()는 문자열 목록을 모두 받습니다. 해당 간략한 설명을 수정하면 제안 프롬프트가 변경되고, 이 프롬프트는 캐시 키의 일부이므로 다음 실행 시 모든 라운드마다 API를 다시 호출합니다.
요청 수는 질문이 아닌 행(row)에 따라 증가합니다: 라운드당 행마다 하나의 요청이므로, 100,000행은 라운드당 100,000개의 요청을 의미합니다. 수정은 새로운 질문으로 간주되므로 모든 행에 대해 다시 한 번 처리해야 합니다. 워커 풀은 천천히 늘리세요. 공유 키의 속도 제한에 도달하려면 8개만 있어도 충분합니다.
질문들이 보는 것
점수 범위의 각 4분할마다 하나씩, 총 5개의 홀드아웃 리뷰를 38개 질문 중 15개에 대해 평가했다: 중요도 기준 상위 8개 점수 질문과 상위 7개 nouls.
이十五 개의 행은 비평가 점수에 따라 답변이 어떻게 변하는지로 정렬됩니다. 점수가 오를수록 답변이 상승하는 질문은 먼저 나오고, 점수가 오를수록 답변이 하락하는 질문은 구분선 뒤에 옵니다. 따라서 왼쪽에서 오른쪽으로, 가장 나쁜 리뷰에서 가장 좋은 리뷰로 갈 때, 구분선 위의 답변은 상승해야 하고 구분선 아래의 답변은 하락해야 합니다.
X, labels = design(accepted, answers_for, ENCODING)
column_importances = importances(X[DEV], SCORES[DEV])
# an encoding gives a feature more than one column, so add a feature's columns back up
feature_importances = importance_per_feature(accepted, labels, column_importances)
ranked = sorted(accepted, key=lambda f: -feature_importances[f["name"]])
score_questions = [f for f in ranked if f["kind"] == "intensity"][:8]
noul_questions = [f for f in ranked if f["kind"] == "presence"][:7]
# ordered by which way the answer moves with the score, so the map flips halfway down
heatmap_questions = sorted(
    score_questions + noul_questions,
    key=lambda f: -polarity(f, answers_for, split),
)
ordered_test = TEST[np.argsort(SCORES[TEST], kind="stable")]
positions = np.linspace(0, len(ordered_test) - 1, 5).round().astype(int)
review_rows = tuple(ordered_test[positions])

print("the five held-out heatmap columns:\n")
for i, row in enumerate(review_rows, 1):
    excerpt = " ".join(NOTES[row].split())
    print(f"  {i}. {SCORES[row]:.0f} points: {excerpt[:100]}...")

fig = reviews_heatmap(plt, heatmap_questions, answers_for, split, review_rows)
display(fig)
plt.close(fig)
the five held-out heatmap columns:
1. 80 points: Raw cherry and plum aromas are resiny and suggest wet cement. This is shearing and so jacked up with...
2. 86 points: A slight spritz brightens the mouthfeel of this lemony wine. Aromas are a bit musky, but flavors of ...
3. 89 points: This is a European-style Syrah, cofermented with 2% Viognier. It's soft and round, medium in body, a...
4. 91 points: From the producer's dry-farmed estate vineyard, and supported by small amounts of Merlot and Caberne...
5. 97 points: A thoroughly elegant, serious and yet immensely enjoyable wine that stays lively many days after ope...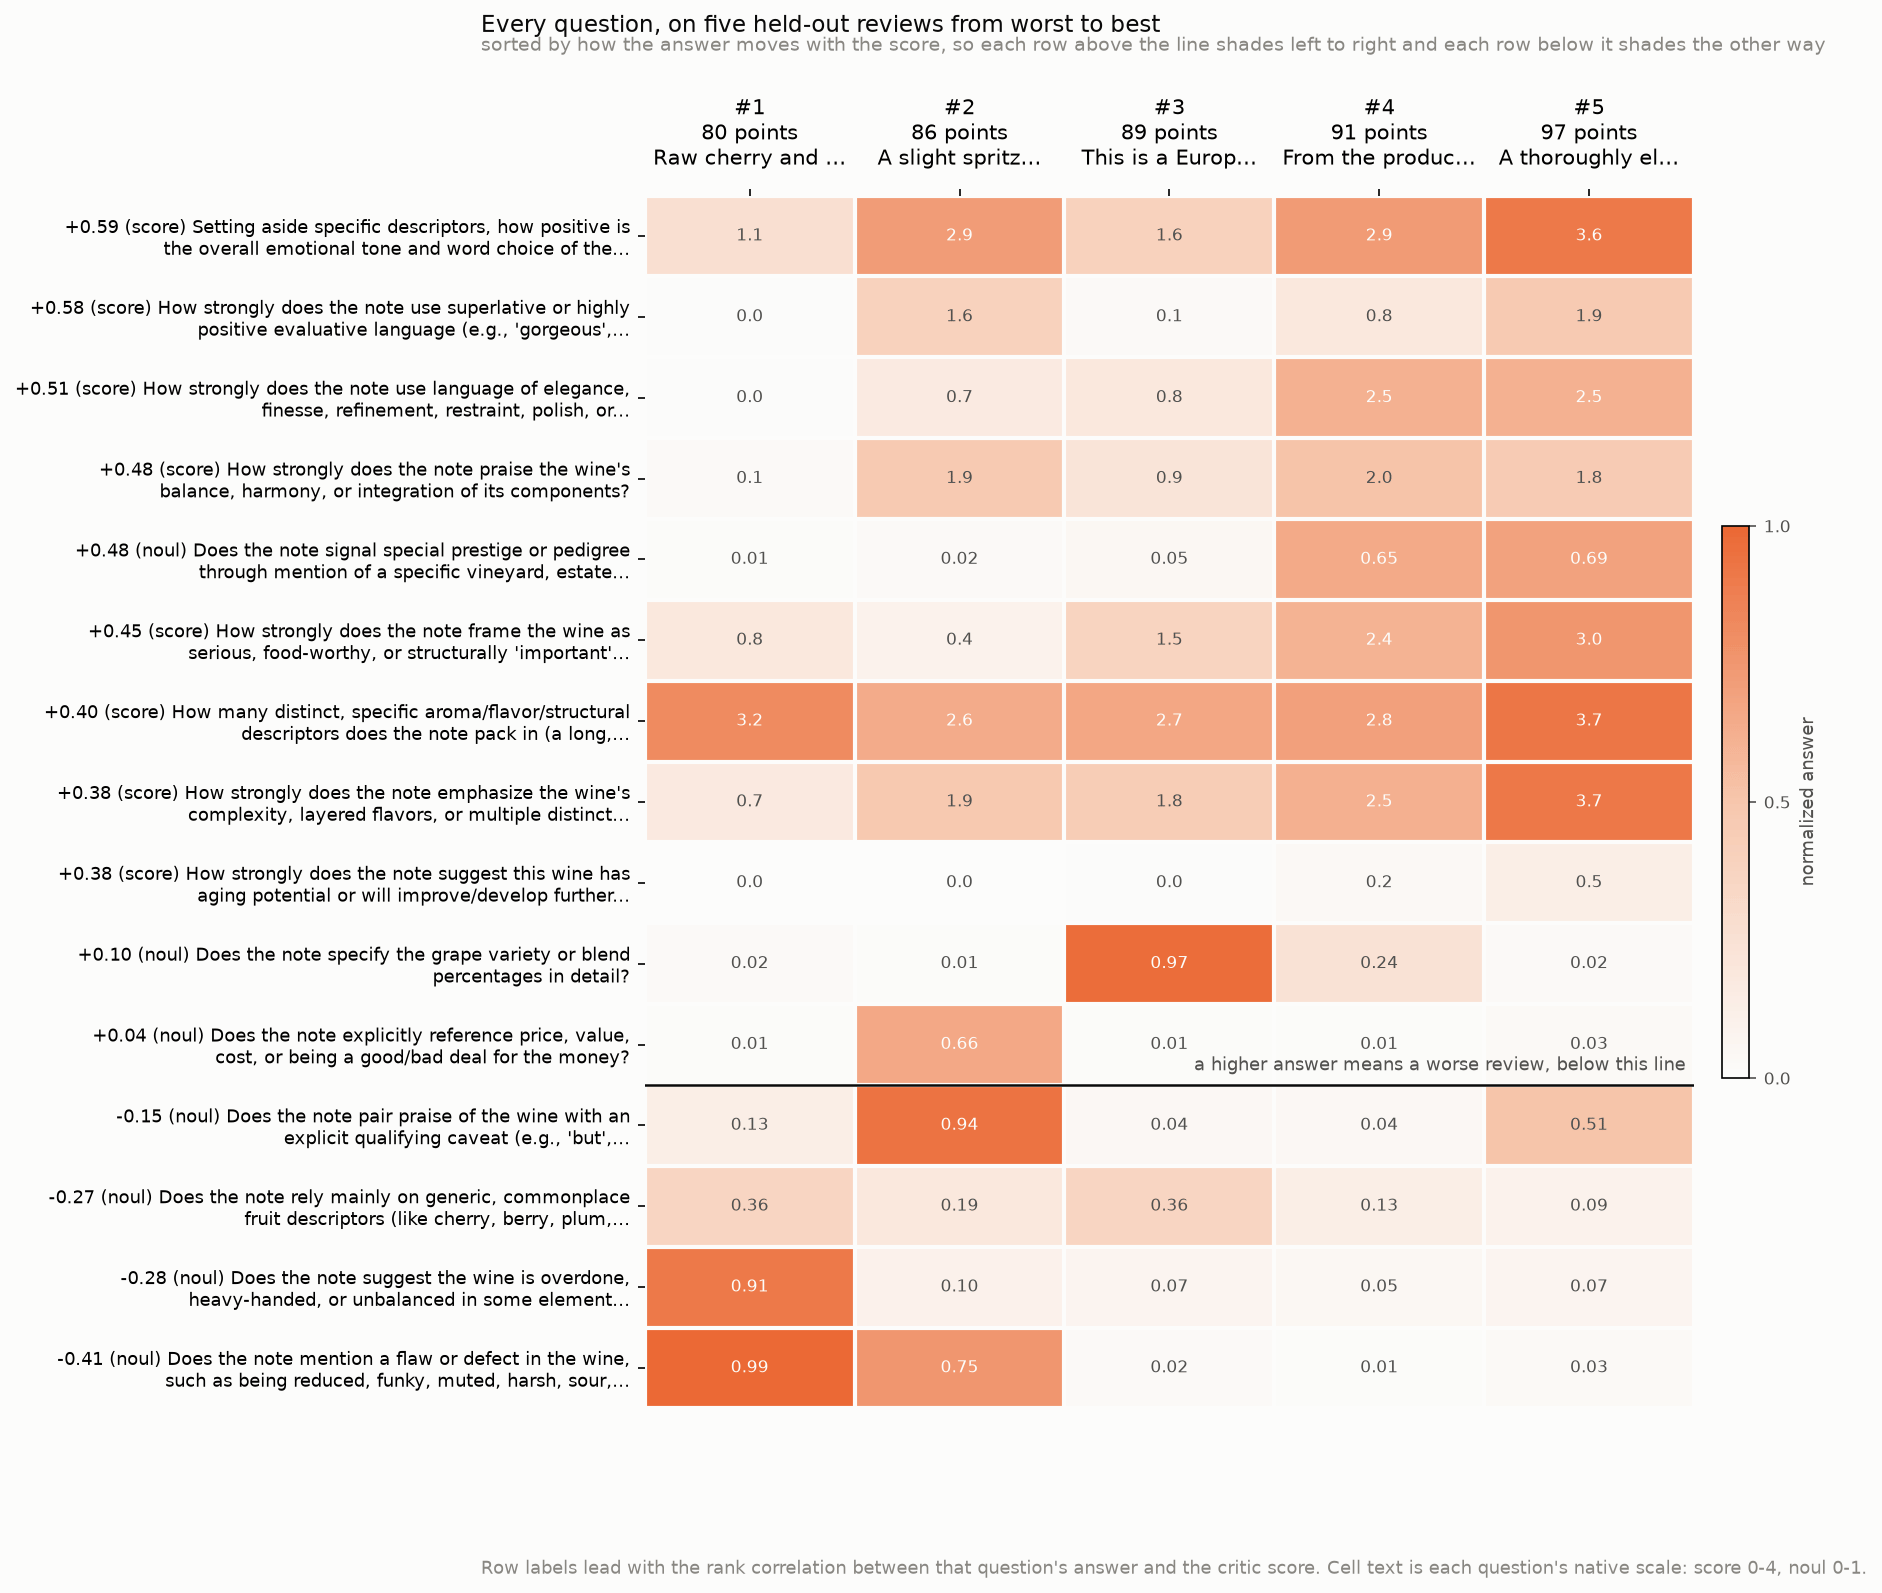
페이지 상단의 표, 계산됨. 다섯 개의 아ーム은 동일한 800개의 홀드아웃 행에서 한 번씩 점수를 받으며, 처음 세 개는 피처 디스커버리를 건너뛴다. 하나는 dev 점수의 평균을 예측하며 노트에서 전혀 읽지 않는다. 하나는 text_features 처리를 통해 노트를 동일한 CatBoost에 전달하며, 이는 단어 빈도로 변환한다. 하나는 TypeSafe에 점수 자체를 요청한다.
그 세 번째 항목은 열 가지 품질 밴드마다 행당 Score 하나씩이며, “결함이 있거나 불쾌한” 상태에서 “심오한” 상태까지입니다. 열 단계인 이유는 Score 질문이 수용할 수 있는 최대 레벨이 열이기 때문이며, 열 한 단계가 넘어가면 서버 오류로 반환됩니다. 레벨 0은 80점에, 레벨 9는 100점에 대응됩니다. 이렇게 밴드를 척도 위에 분포시키는 것만으로는 부족합니다. 질문 내용에는 이 출판물의 점수가 실제로 척도 상 어디에 위치하는지에 대한 정보가 없기 때문입니다. 따라서 모든 답변은 개발자 점수를 기준으로 측정한 단일 오프셋만큼 이동합니다. 이 오프셋은 행 레이블에 출력되며, 이 단축키가 점수로부터 학습하는 유일한 요소입니다.
Spearman은 순위 상관계수이며, 1.0은 홀드아웃 와인들을 비평가의 순서대로 정확히 배치함을 의미합니다. 단어 수 행은 CatBoost의 자체 텍스트 처리 방식이며, 튜닝된 텍스트 회귀 파이프라인이 아닙니다. 이는 모두 하나의 데이터셋과 루프의 한 번 실행을 나타냅니다.
predicted = fit_predict(X, split)
text_predicted = fit_predict_text(split)

# ask TypeSafe for the score itself, one request per row
with ThreadPoolExecutor(max_workers=8) as pool:
    direct = list(pool.map(lambda note: ask_score(TYPESAFE_MODEL, note), NOTES))
asked = np.array([d["expected"] for d in direct])
shift = float(SCORES[DEV].mean() - asked[DEV].mean())  # one number, from the dev labels

# what one proposal call gets you, before any feedback: the set round 1 ended with
first_round, _ = design(snapshots[0], answers_for, ENCODING)

print(f"{'arm':<46}{'RMSE':>7}{'spearman':>10}")
for label, p in (
    ("predict the mean of the dev rows", np.full(len(TEST), SCORES[DEV].mean())),
    ("the note as word counts, same CatBoost", text_predicted),
    (f"ask for the score itself, shifted {shift:+.2f}", asked[TEST] + shift),
    (
        f"{len(snapshots[0])} questions from round 1, no loop",
        fit_predict(first_round, split),
    ),
    (f"{len(accepted)} questions after all {ROUNDS} rounds", predicted),
):
    print(f"{label:<46}{rmse(SCORES[TEST], p):>7.3f}{spearman(SCORES[TEST], p):>10.3f}")
arm RMSE spearman
predict the mean of the dev rows 3.088 -0.014
the note as word counts, same CatBoost 2.466 0.605
ask for the score itself, shifted -1.71 2.145 0.761
18 questions from round 1, no loop 1.869 0.778
38 questions after all 5 rounds 1.772 0.799자동 검색 라운드가 도움이 되었나요?
두 선 모두 첫 번째 제안부터 시작해 각 라운드 종료 시점의 질문 세트 오차를 나타냅니다. 점선은 교차 검증된 개발 오차이며, 모든 수락 및 거절 결정은 이 값을 기준으로 이루어집니다. 실선은 루프에서 절대 읽지 않는 홀드아웃 행들에 동일한 질문 세트를 평가한 점수입니다. 각 점은 라운드가 종료될 당시의 질문 세트 상태를 반영하므로, 단순히 질문을 수정하거나 삭제한 라운드라도 두 선은 모두 이동합니다. 기능 맵은 질문들이 무엇을 측정하는지를 나타내며, 오차는 첫 번째 제안 이후의 라운드들이 예측을 얼마나 개선했는지를 알려줍니다.
축이 매우 좁다: 축 위의 모든 값은 0.1포인트 이내에서 발생하며, 위의 표에서 제시된 모든 단축값은 그 축의 상단에서 멀리 떨어져 있다. 개발선(dev line)은 전체 구간 동안 홀드아웃선(held-out line) 위에 위치하며, 이는 학습 데이터 크기 효과 때문이다. 각 개발 폴드(dev fold)는 개발 행의 5분의 4로 학습하는 반면, 홀드아웃 값은 전체 1,200개의 데이터를 학습한 모델에서 도출된다. 두 선은 함께 움직이므로, 루프가 조정하는 개발 값은 절대 보지 못하는 홀드아웃 값을 잘 추적한다. 제목 아래의 간격(interval)은 홀드아웃 행을 재표본추출(resampling)하여 산출한 것이므로, 라운드 1에서 라운드 5로의 변화가 800개 행의 노이즈보다 큰지를 나타낸다.
curve, per_round = [], []
for features in snapshots:
    X_round, _ = design(features, answers_for, ENCODING)
    per_round.append(fit_predict(X_round, split))
    curve.append((len(features), rmse(SCORES[TEST], per_round[-1])))

# the same held-out rows resampled 2,000 times, both arms scored on each resample
gain = paired_gain(SCORES[TEST], per_round[0], per_round[-1])
print(
    f"round 1 -> round {ROUNDS} on the held-out rows: {gain[0]:+.3f} points, "
    f"95% CI [{gain[1]:+.3f}, {gain[2]:+.3f}]"
)

fig = rounds_chart(plt, curve, history, len(TEST), gain)
display(fig)
plt.close(fig)
round 1 -> round 5 on the held-out rows: -0.097 points, 95% CI [-0.147, -0.050]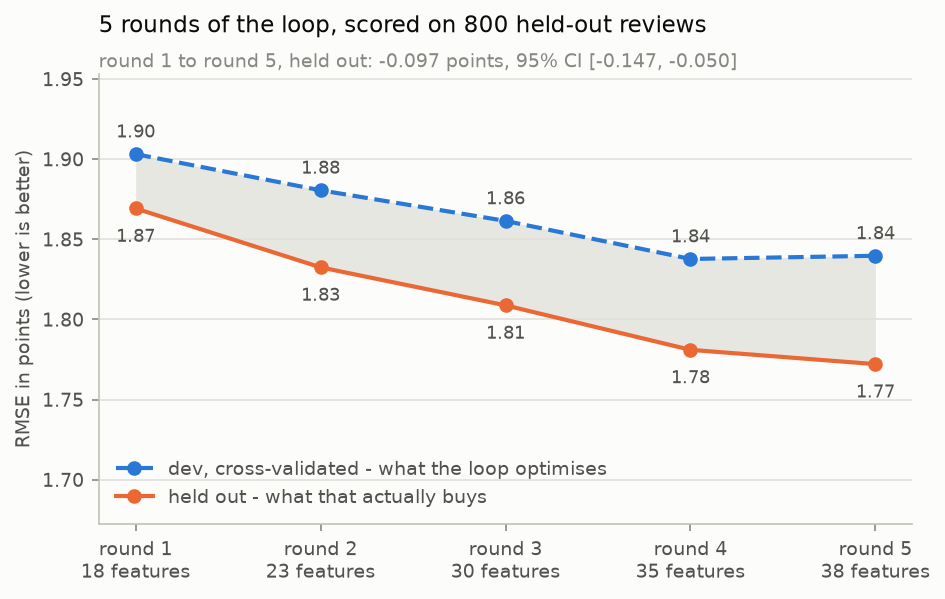
홀드아웃 라인은 개발 라인보다 더 크게 떨어졌다. 1라운드에서 작성된 질문들은 작업할 피드백이 없었으며, 그 이후의 네 라운드는 홀드아웃 행에서 0.10점의 가치를 지닌다. 95% CI [-0.147, -0.050].
라운드 5에서는 네 가지 추가, 두 가지 재표현, 여덟 가지 삭제를 제안했으며, 개선되지 않은 첫 번째 개발자 수치를 제시했습니다. 245자 분량의 노트에 대해 물을 수 있는 것은 한정되어 있으며, 라운드 5가 되면 제안사항이 질문을 추가하는 것에서 질문을 삭제하는 쪽으로 기울었습니다.
kinds = {f["name"]: f["kind"] for f in accepted}
print("feature importance share: % of total CatBoost importance across all questions")
print(f"{'feature':<38}{'asked as':<10}{'importance share':>16}")
for name, importance_share in sorted(feature_importances.items(), key=lambda p: -p[1])[
    :12
]:
    kind = "score" if kinds[name] == "intensity" else "noul"
    print(
        f"{name[:36]:<38}{kind:<10}{importance_share:>8.1f}%  "
        f"{'#' * round(importance_share)}"
    )
counts = f"{sum(1 for k in kinds.values() if k == 'intensity')} score"
counts += f", {sum(1 for k in kinds.values() if k == 'presence')} noul"
print(f"\nthe {len(accepted)} questions the loop kept: {counts}")
top = max(feature_importances, key=feature_importances.get)
print(
    f'the question behind the top row:\n  {top}: "{owner_of(top, accepted)["question"]}"'
)
feature importance share: % of total CatBoost importance across all questions
feature asked as importance share
note_overall_tone_positivity score 17.4% #################
savory_food_wine_seriousness score 8.7% #########
positive_superlative_language score 8.4% ########
single_vineyard_or_prestige_signal noul 7.2% #######
descriptive_detail_density score 5.7% ######
elegance_finesse_language score 5.0% #####
complexity score 5.0% #####
aging_potential score 5.0% #####
balance_harmony score 2.9% ###
drinkability_easiness score 2.9% ###
critic_enthusiasm_confidence score 2.7% ###
flavor_distinctiveness score 2.6% ###
the 38 questions the loop kept: 29 score, 9 noul
the question behind the top row:
note_overall_tone_positivity: "Setting aside specific descriptors, how positive is the overall emotional tone and word choice of the note taken as a whole (warm, admiring language throughout vs. flat, neutral, or lukewarm phrasing)?"importance share은 CatBoost 피처 중요도로, 38개 질문의 합이 100%가 되도록 정규화되었습니다. 이는 행의 비율, 질문의 비율, 또는 예측 정확도의 비율이 아닙니다. 점수 질문은 평균과 확산 두 개의 열을 소유하므로, 퍼센티지가 출력되기 전에 두 열의 중요도가 합산됩니다. note_overall_tone_positivity은 전체의 17.4%를 차지합니다. 네 번째 행은 noul입니다. 노트가 단일 포도원을 지칭하는지 아니면 다른 기타 명성 신호를 지칭하는지는 예/아니오 사실이기 때문에, 하나로 질문되었습니다.
다음 단계
이번 실행은 루프를 작게 유지합니다. 직접적인 확장:
- 답변을 지불하기 전에 후보자를 선별하십시오. 제안된 질문 자체를 상태로 간주하고 nouls에 대해 문의하십시오: 소스 텍스트에서 답변할 수 있는지, 기준 하에서 하나의 의미만 가지는지, 대부분의 행에 적용되는지, 행 간에 변동하는지. 네 가지 기준을 모두 높은 신뢰도로 통과한 질문만 보내십시오.
- 상관관계가 있는 특성을 가지치기하십시오. 개발 행에서 인코딩된 열 간의 상관관계를 측정하고, 유사한 중복 항목을 클러스터링한 후, 각 클러스터에서 가장 명확하거나 중요한 질문 하나만 유지하십시오.
- 간단한 베이스라인을 추가하십시오. TF-IDF, 문자 수, 기타 구조적 특성을 단독으로 비교한 다음, 발견된 열에 추가하여 각 항목이 기여하는 바를 측정하십시오.
- 제안자 계열을 혼합하십시오. Anthropic, OpenAI, Google Gemini 및 오픈소스 모델로 후보 배치 세트를 생성한 후, 이들이 TypeSafe에 도달하기 전에 병합하고 중복을 제거하십시오. 서로 다른 계열은 단일 제안자에 대한 반복 호출보다 탐색 범위를 더 넓혀야 합니다.
- 예측 모델과 방법을 비교하십시오. 선형 또는 엘라스틱넷 회귀, 서포트 벡터 회귀기, 랜덤 포레스트, 그리고 하류 출력이 확률적일 경우 재보정(re-calibration)을 시도하십시오. 발견된 특성이 CatBoost 외부에서도 도움이 되는지 확인하십시오.
- 임베딩 베이스라인을 추가하십시오. 임베딩은 질문 없이 노트를 수백 개의 숫자로 변환합니다:
sentence-transformers/all-MiniLM-L6-v2는 로컬에서 실행되고, OpenAI의text-embedding-3-small는 호스팅된 호출입니다. 이를 발견된 열에 추가하고, 해당 열들이 담지 않은 정보를 임베딩이 담고 있는지 측정하십시오. - 검증을 배포에 맞추십시오. 미래를 예측할 때는 시계열 분할을 사용하고, 관련 행이 함께 유지되어야 할 때는 그룹 분할을 사용하며, 특성 발견과 모델 선택 모두에 의해 손대지 않은 최종 테스트 세트를 유지하십시오.
- 정체기에서 멈추십시오. 교차 검증 RMSE가 고정된 수의 라운드 동안 개선되지 않거나, 질문 또는 요청 예산에 도달하면 루프를 종료하십시오.
- 에이전의 Goal 모드에서 더 긴 탐색을 실행하십시오. 명시적인 지표, 예산, 중단 규칙을 제공하고, 에이전트가 더 많은 라운드 동안 제안, 평가 및 정제하도록 하십시오.
- 안정성을 확인하십시오. 시드나 데이터 슬라이스 간에 발견을 반복하고, 한 번의 분할에만 중요성이 기반된 질문이 아니라, 유용성을 유지하는 질문들을 유지하십시오.
플레이그라운드에서 열기
이 공유 링크에는 하나의 테이스팅 노트와 루프가 최종적으로 도출한 모든 질문이 포함되어 있습니다。
playground_link = make_playground_link(
    NOTES[0], feature_questions(accepted), models=[TYPESAFE_MODEL]
)
display(
    Markdown(
        f"🔗 [Open the note + questions in the TypeSafe playground]({playground_link})"
    )
)