 JevCode
Entdeckung der Autoresearch-Funktion
Führt eine Autoresearch-Schleife aus, die TypeSafe-Fragen vorschlägt, Freitext in numerische Merkmale umwandelt und Modellfehler nutzt, um einen überwachten CatBoost-Regressor zu verbessern.
Maschinell aus en übersetzt, nicht lektoriert. Nur als Kurzreferenz geeignet.

TypeSafe-Fragen wandeln freien Text in numerische Merkmale für ein überwachtes CatBoost-Modell um; nutzen Sie eine autoresearch-Schleife, um sie zu entdecken.
CatBoost benötigt eine Tabelle mit Zahlen, und eine Verkostungsnotiz ist keine. Dieses Kochbuch erstellt die Tabelle aus Fragen zur Notiz, und keine davon wird von Hand verfasst. Ein LLM schlägt die Fragen vor, TypeSafe beantwortet sie für jede Zeile, und CatBoost trainiert auf den Antworten. Der autoresearch-Teil ist das, was als Nächstes kommt: CatBoost berichtet, welche Fragen es verwendet hat und welche Zeilen es immer noch falsch klassifiziert, der folgende Vorschlagsaufruf liest diesen Bericht, und die Schleife läuft erneut.
Am Ende hast du eine Schleife, auf die du deinen eigenen beschrifteten Text zeigen kannst, eine Kurve des zurückgehaltenen Fehlers pro Runde und eine Tabelle darüber, welche Fragen das endgültige Modell am häufigsten verwendet hat.
tasting note
    |
    v
38 TypeSafe answers
    |-- 29 score questions x 2 columns = 58
    |     expected rubric level + answer uncertainty
    `--  9 noul questions  x 1 column  =  9
          probability true
    |
    v
67 numeric columns --> CatBoost --> predicted critic score
                                     held-out RMSE: 1.77 points
Eine Score-Antwort wird zu zwei Spalten: dem durchschnittlichen Niveau, auf das die Antwort hinweist, und wie stark sie um diesen Durchschnitt verteilt ist. Eine Noul-Antwort ist eine Wahrscheinlichkeit, also eine einzige Spalte.
Die Daten umfassen 2.000 Weinbewertungen: eine Verkostungsnotiz als Eingabe, die Bewertung des Kritikers auf einer Skala von 80–100 als Ausgabe. Der RMSE misst den Vorhersagefehler in Punkten der Kritikerbewertung, wobei größere Abweichungen stärker ins Gewicht fallen; niedriger ist besser. Jede Zahl in der folgenden Tabelle stammt aus den 800 Bewertungen, die weder das Modell noch die Schleife je gesehen haben.
| wie die Notiz zu einer Bewertung wird | RMSE |
|---|---|
| den Durchschnitt der Trainingszeilen vorhersagen | 3.09 |
| derselbe CatBoost, die Notiz als Wortanzahl lesend | 2.47 |
| TypeSafe nach der Bewertung selbst fragen, skaliert und verschoben | 2.15 |
| 18 Fragen aus einem Proposal-Aufruf, keine Schleife | 1.87 |
| 38 Fragen nach fünf Runden der Schleife | 1.77 |
Die letzten beiden Zeilen sind die Schleife. Ein Vorschlagsaufruf, noch ohne jegliche Grundlage, erreicht 1.87. Vier weitere Runden des Lesens seiner schlimmsten Vorhersagen führen zu 1.77. Der Großteil des Gewinns liegt in diesem ersten Aufruf, und wie viel die vier darauffolgenden Runden hinzufügen, wird weiter unten gemessen.
Tipp — Möchten Sie dieses Notebook vertiefen oder auf ein anderes Problem anwenden? Siehe Nächste Schritte.
from __future__ import annotations
import json
import os
import random
import textwrap
import urllib.request
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from time import perf_counter
from typing import NamedTuple
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from catboost import CatBoostRegressor
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Noul, NoulCriteria, Score, TypeSafeClient
matplotlib.use("Agg") # headless render
TYPESAFE_MODEL = "jev-1.12"
FOLDS, REPEATS = 5, 3 # repeats steady the error at this sample size
CATBOOST = dict(
iterations=400,
depth=4,
learning_rate=0.05,
loss_function="RMSE",
verbose=0,
random_seed=0,
thread_count=1,
allow_writing_files=False,
)
client = TypeSafeClient(
# keyless kernels replay the cache
api_key=os.environ.get("TYPESAFE_API_KEY", "cache-only"),
base_url=os.environ.get("TYPESAFE_ENDPOINT"),
timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
# ----------------------------------------------------------------- the specification
INTENSITY_LEVELS = [
"Not present in this note at all",
"Barely present - mentioned once, in passing",
"Present at a moderate level",
"Present strongly - the note dwells on it",
"Dominant - the note is largely about this",
]
PRESENCE_CRITERIA = NoulCriteria(
true="The note states this or clearly implies it",
false="The note gives no indication of this",
)
# Asking for the score outright: ten quality bands, rescaled onto the 80-100 critic scale.
SCORE_LEVELS = [
"Faulty or unpleasant - the note is mostly criticism",
"Barely acceptable - drinkable, with nothing to recommend it",
"Simple and sound - correct, plain, forgettable",
"Pleasant everyday wine - some appeal, little depth",
"Good - clear varietal character, well made",
"Very good - balanced, with something to say",
"Excellent - complex and structured",
"Outstanding - depth and length, built to age",
"Superb - among the best of its type",
"Profound - the note treats it as exceptional",
]
# Structured output requires every property in `required`, so unused fields come back empty.
PROPOSAL_SCHEMA = {
"type": "object",
"properties": {
"actions": {
"type": "array",
"items": {
"type": "object",
"properties": {
"op": {"type": "string", "enum": ["add", "revise", "drop"]},
"target": {"type": "string"},
"name": {"type": "string"},
"kind": {"type": "string", "enum": ["intensity", "presence"]},
"question": {"type": "string"},
},
"required": ["op", "target", "name", "kind", "question"],
"additionalProperties": False,
},
}
},
"required": ["actions"],
"additionalProperties": False,
}
PROPOSALS = 18 # actions the proposer may return per round
# The one string that knows this is about wine. Point it at your own label and text.
PROPOSER_TASK = f"""You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to {PROPOSALS} actions. Each action is one of:
- {{"op": "add", "target": "", "name": ..., "kind": ..., "question": ...}}
A new feature.
- {{"op": "revise", "target": <name of an existing feature>, "name": ..., "kind": ...,
"question": ...}}
Replace that feature's question with better wording. Use this when a feature measures the
right thing badly: too narrow, too vague, or worded so nearly every note answers the same.
- {{"op": "drop", "target": <name of an existing feature>, "name": "", "kind": "intensity",
"question": ""}}
Remove a feature that is not earning its place.
`kind` is "intensity" for something with a degree, or "presence" for a yes/no fact.
`question` is what gets asked about one tasting note.
An "intensity" question is graded against this fixed five-level rubric, so word it so that the
levels make sense:
{chr(10).join(f" {i}. {level}" for i, level in enumerate(INTENSITY_LEVELS))}
A "presence" question is answered as the probability that it is true of the note.
Good features can be judged from the note's own words, vary from note to note, and carry
information about quality that the other features do not. Reviewers describe structure, fruit,
oak, length, complexity, and drinkability, and they also signal quality through word choice."""
class Split(NamedTuple):
"""The rows, their labels, and which half the loop is allowed to read."""
notes: list[str]
scores: np.ndarray
dev: np.ndarray
test: np.ndarray
# ----------------------------------------------------------------- the data
WINEMAG_CSV = (
"https://huggingface.co/datasets/GroNLP/ik-nlp-22_winemag/resolve/"
"90eb39f35fc64e556fc17f06d4137a4a69ec3297/train.csv"
)
@json_cache
def load_slice(n_dev: int, n_test: int, seed: int) -> dict:
"""Fetch the pinned CSV and take a seeded sample of note + score, one row per note."""
import csv
import io
request = urllib.request.Request(
WINEMAG_CSV, headers={"User-Agent": "typesafe-cookbook/1.0"}
)
with urllib.request.urlopen(request, timeout=300) as response:
text = response.read().decode()
rows, seen = [], set()
for row in csv.DictReader(io.StringIO(text)): # a few notes repeat verbatim
if not row["description"] or not row["points"] or row["description"] in seen:
continue
seen.add(row["description"])
rows.append((row["description"], float(row["points"])))
random.Random(seed).shuffle(rows)
picked = rows[: n_dev + n_test]
return {"notes": [r[0] for r in picked], "points": [r[1] for r in picked]}
def example_rows(split: Split, out_of_fold: np.ndarray | None, n: int) -> list[int]:
"""Select representative dev rows for a proposer round."""
dev = split.dev
if out_of_fold is None:
ranked = dev[np.argsort(split.scores[dev], kind="stable")]
return [int(ranked[round(q * (len(ranked) - 1))]) for q in np.linspace(0, 1, n)]
error = np.abs(split.scores[dev] - out_of_fold)
order = np.argsort(-error, kind="stable")
worst = [int(dev[i]) for i in order[: n // 2]]
best = [int(dev[i]) for i in order[len(order) - (n - n // 2) :]]
return worst + best
def example_block(
rows: list[int],
split: Split,
out_of_fold: np.ndarray | None,
previous: np.ndarray | None = None,
) -> str:
"""Format selected rows for the proposer."""
if out_of_fold is None:
head = "Example notes, with the score each one was given:"
body = [f"- scored {split.scores[r]:.0f}: {split.notes[r]}" for r in rows]
return head + "\n" + "\n".join(body)
head = (
"Dev notes, worst-predicted first. The first half is where your current questions "
"miss by the most and the second half is where they are already right, so what "
"separates the halves is what the questions have not captured."
)
if previous is not None:
head += (
" Each line also carries what the previous round predicted, so you can see which "
"notes your last batch of questions moved."
)
body = []
for r in rows:
line = f"- scored {split.scores[r]:.0f}, predicted {out_of_fold[r]:.1f}"
if previous is not None:
line += f" (last round {previous[r]:.1f})"
body.append(f"{line}: {split.notes[r]}")
return head + "\n" + "\n".join(body)
def load_split(n_dev: int, n_test: int, seed: int = 0) -> Split:
# keyword, because the cache key is the function name plus how each argument was spelled
data = load_slice(n_dev, n_test, seed=seed)
return Split(
notes=data["notes"],
scores=np.array(data["points"]),
dev=np.arange(n_dev),
test=np.arange(n_dev, n_dev + n_test),
)
# ----------------------------------------------------------------- step 1: propose
def proposal_prompt(examples: str, feedback: str, accepted: list[dict]) -> str:
parts = [PROPOSER_TASK, "\n" + examples]
if accepted:
parts.append(
"\nThe features you have now. `add` must not duplicate one of these; `revise` and "
"`drop` refer to one by name:\n"
+ "\n".join(
f"- {f['name']} ({f['kind']}): {f['question']}" for f in accepted
)
)
if feedback:
parts.append("\nHow the model did with those features:\n" + feedback)
return "\n".join(parts)
@json_cache
def propose(model: str, round_index: int, prompt: str) -> dict:
"""One proposal call. Every number in `prompt` is rounded so a replay hits the cache."""
if model.startswith("claude"):
import anthropic
response = anthropic.Anthropic(
api_key=os.environ.get("ANTHROPIC_API_KEY", "cache-only")
).messages.create(
model=model,
max_tokens=16000,
output_config={
"effort": "medium",
"format": {"type": "json_schema", "schema": PROPOSAL_SCHEMA},
},
messages=[{"role": "user", "content": prompt}],
)
body = next(block.text for block in response.content if block.type == "text")
usage = [response.usage.input_tokens or 0, response.usage.output_tokens or 0]
else:
from openai import OpenAI
response = OpenAI(
api_key=os.environ.get("OPENAI_API_KEY", "cache-only")
).chat.completions.create(
model=model,
reasoning_effort="high",
max_completion_tokens=16000,
response_format={"type": "json_object"},
messages=[
{
"role": "user",
"content": prompt
+ "\n\nReply with JSON matching this schema:\n"
+ json.dumps(PROPOSAL_SCHEMA),
}
],
)
body = response.choices[0].message.content
usage = [response.usage.prompt_tokens, response.usage.completion_tokens]
return {"actions": json.loads(body)["actions"][:PROPOSALS], "usage": usage}
def slug(name: str, taken: set[str]) -> str:
"""Names become question ids and column labels, so keep them plain and unique."""
base = (
"".join(c if c.isalnum() else "_" for c in name.lower()).strip("_") or "feature"
)
candidate, n = base, 2
while candidate in taken:
candidate, n = f"{base}_{n}", n + 1
return candidate
def to_candidates(actions: list[dict], accepted: list[dict], round_index: int) -> tuple:
"""Split a round's actions into screenable candidates and a list of names to drop."""
live = {f["name"] for f in accepted}
drops = [a["target"] for a in actions if a["op"] == "drop" and a["target"] in live]
replacing = {
a["target"] for a in actions if a["op"] == "revise" and a["target"] in live
}
# a revision may keep the name it replaces, since that feature is on its way out
taken, candidates = live - replacing, []
for action in actions:
if action["op"] == "drop":
continue
if action["op"] == "revise" and action["target"] not in live:
continue # a revision of something that is not there
name = slug(action["name"], taken)
taken.add(name)
candidates.append(
{
"id": f"{name}@{round_index}", # unique, so earlier rounds keep their columns
"name": name,
"kind": action["kind"],
"question": action["question"],
"replaces": action["target"] if action["op"] == "revise" else "",
}
)
return candidates, drops
# ----------------------------------------------------------------- step 2: answer
def feature_questions(features: list[dict]) -> dict:
questions = {}
for feature in features:
if feature["kind"] == "intensity":
questions[feature["name"]] = Score(
instructions=feature["question"], criteria=INTENSITY_LEVELS
)
else:
questions[feature["name"]] = Noul(
instructions=feature["question"], criteria=PRESENCE_CRITERIA
)
return questions
@json_cache
def answer(model: str, note: str, features_json: str) -> dict:
"""One request per note; every question of the round rides it. Keeps every probability."""
features = json.loads(features_json)
started = perf_counter()
response = client.system_one(
state=note, questions=feature_questions(features), model=model
)
raw = {}
for feature in features:
got = response.answers[feature["name"]]
if feature["kind"] == "intensity":
raw[feature["name"]] = [
got.probabilities.get(i, 0.0) for i in range(len(INTENSITY_LEVELS))
]
else:
raw[feature["name"]] = [got.noul]
return {
"raw": raw,
"seconds": round(perf_counter() - started, 2),
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
def featurize(notes: list[str], features: list[dict]) -> dict:
"""Answer one question set for many notes: one request each, eight in flight."""
payload = json.dumps(features, sort_keys=True)
with ThreadPoolExecutor(max_workers=8) as pool:
results = list(
pool.map(lambda note: answer(TYPESAFE_MODEL, note, payload), notes)
)
return {
f["name"]: np.array([r["raw"][f["name"]] for r in results], dtype=float)
for f in features
}
def encode(feature: dict, probabilities: np.ndarray, mode: str) -> list[tuple]:
"""Turn one question's probabilities into named columns."""
name = feature["name"]
if feature["kind"] == "presence":
return [(name, probabilities[:, 0])] # one number is all there is
levels = np.arange(probabilities.shape[1])
mean = probabilities @ levels
if mode == "mean":
return [(name, mean)]
if mode == "mean_spread":
variance = probabilities @ (levels**2) - mean**2
return [(name, mean), (f"{name}_sd", np.sqrt(np.clip(variance, 0, None)))]
return [(f"{name}_p{i}", probabilities[:, i]) for i in levels]
def design(features: list[dict], answers_for: dict, mode: str) -> tuple:
"""Stack every feature's columns into one matrix, plus a label per column."""
columns, labels = [], []
for feature in features:
for label, column in encode(feature, answers_for[feature["id"]], mode):
columns.append(column)
labels.append(label)
return np.column_stack(columns), labels
def plain(features: list[dict]) -> list[dict]:
"""What goes on the wire and into the cache key: no id, no bookkeeping."""
return [
{"name": f["name"], "kind": f["kind"], "question": f["question"]}
for f in features
]
# ----------------------------------------------------------------- step 3: fit
def rmse(y: np.ndarray, p: np.ndarray) -> float:
return float(np.sqrt(np.mean((y - p) ** 2)))
def spearman(a: np.ndarray, b: np.ndarray) -> float:
"""Rank correlation: does the model order the wines the way the critic did?"""
ranks = (
np.argsort(np.argsort(a)).astype(float),
np.argsort(np.argsort(b)).astype(float),
)
return float(np.corrcoef(*ranks)[0, 1])
def folds(y: np.ndarray, k: int, seed: int) -> list[np.ndarray]:
"""Label-stratified k-fold: sort by the label with a seeded tiebreak, then deal off the top."""
rng = np.random.default_rng(seed)
order = np.lexsort((rng.random(len(y)), y))
return [np.sort(order[i::k]) for i in range(k)]
def cross_validate(X: np.ndarray, y: np.ndarray) -> tuple[np.ndarray, float]:
out_of_fold = np.zeros((REPEATS, len(y)))
for repeat in range(REPEATS):
for fold in folds(y, FOLDS, seed=repeat):
train = np.setdiff1d(np.arange(len(y)), fold)
model = CatBoostRegressor(**CATBOOST).fit(X[train], y[train])
out_of_fold[repeat, fold] = model.predict(X[fold])
scores = [rmse(y, out_of_fold[repeat]) for repeat in range(REPEATS)]
return out_of_fold.mean(axis=0), float(np.mean(scores))
def importances(X: np.ndarray, y: np.ndarray) -> np.ndarray:
return CatBoostRegressor(**CATBOOST).fit(X, y).get_feature_importance()
def paired_gain(y: np.ndarray, before: np.ndarray, after: np.ndarray) -> tuple:
"""Bootstrap the paired held-out RMSE change."""
squared = ((y - before) ** 2, (y - after) ** 2)
rng = np.random.default_rng(0)
drawn = []
for _ in range(2000):
rows = rng.integers(0, len(y), len(y))
drawn.append(
np.sqrt(squared[1][rows].mean()) - np.sqrt(squared[0][rows].mean())
)
drawn = np.array(drawn)
return (
rmse(y, after) - rmse(y, before),
float(np.percentile(drawn, 2.5)),
float(np.percentile(drawn, 97.5)),
)
def fit_predict(X: np.ndarray, split: Split) -> np.ndarray:
model = CatBoostRegressor(**CATBOOST).fit(X[split.dev], split.scores[split.dev])
return model.predict(X[split.test])
def fit_predict_text(split: Split) -> np.ndarray:
"""The reference arm: the same model, handed the note instead of the columns."""
from catboost import Pool
raw = np.array([[note] for note in split.notes], dtype=object)
model = CatBoostRegressor(**CATBOOST).fit(
Pool(raw[split.dev], split.scores[split.dev], text_features=[0])
)
return model.predict(Pool(raw[split.test], text_features=[0]))
def evaluate(
features: list[dict], answers_for: dict, split: Split, mode: str
) -> tuple[np.ndarray, float]:
"""Cross-validated error on the dev rows for one candidate question set."""
X, _ = design(features, answers_for, mode)
return cross_validate(X[split.dev], split.scores[split.dev])
def swap_in(accepted: list[dict], feature: dict) -> list[dict] | None:
"""The accepted set with `feature` in place of the one it revises, or None if it is gone."""
at = next(
(i for i, f in enumerate(accepted) if f["name"] == feature["replaces"]), None
)
if at is None:
return None
trial = list(accepted)
trial[at] = {k: feature[k] for k in ("id", "name", "kind", "question")}
return trial
def try_change(
trial: list[dict],
accepted: list[dict],
cv: float,
answers_for: dict,
split: Split,
mode: str,
tolerance: float,
) -> tuple[list[dict], float, str, bool]:
"""Refit with the change and keep it only if the dev error improves. No API calls."""
_, cv_trial = evaluate(trial, answers_for, split, mode)
if cv_trial <= cv + tolerance:
return trial, cv_trial, f"CV {cv:.3f} -> {cv_trial:.3f}", True
return accepted, cv, f"would cost {cv_trial - cv:+.3f}", False
def owner_of(label: str, features: list[dict]) -> dict:
"""Which feature a column label belongs to - encodings suffix the name."""
exact = next((f for f in features if f["name"] == label), None)
if exact:
return exact
return next(f for f in features if label.startswith(f["name"] + "_"))
def importance_per_feature(
features: list[dict], labels: list[str], column_importances: np.ndarray
) -> dict:
"""Sum each question's CatBoost column importances.
Intensity questions can produce multiple model columns. Combining their normalized
importances gives one percentage share per question.
"""
total = {f["name"]: 0.0 for f in features}
for label, column_importance in zip(labels, column_importances):
total[owner_of(label, features)["name"]] += float(column_importance)
return total
def feedback_for(
history: list[float],
accepted: list[dict],
answers_for: dict,
split: Split,
mode: str,
out_of_fold: np.ndarray,
previous: np.ndarray | None,
) -> str:
"""The scoreboard the next proposal call reads. The notes themselves arrive separately,
through `example_block`. Numbers are rounded before they enter the prompt."""
X, labels = design(accepted, answers_for, mode)
dev, scores = split.dev, split.scores
by_name = importance_per_feature(accepted, labels, importances(X[dev], scores[dev]))
lines = ["Cross-validated RMSE in points so far, lower is better:"]
lines += [f" round {i + 1}: {v:.2f}" for i, v in enumerate(history)]
if previous is not None:
now, before = np.abs(scores[dev] - out_of_fold), np.abs(scores[dev] - previous)
better, worse = int((now < before - 0.1).sum()), int((now > before + 0.1).sum())
lines.append(
f"\nAgainst the previous round, {better} of the {len(dev)} dev notes are now "
f"predicted better by more than 0.1 points and {worse} are predicted worse."
)
lines.append(
"\nYour features, with importance as a percentage of the total and the spread of the "
"column across the dev rows. Low importance or low spread means the question is not "
"doing much; revise or drop it."
)
for feature in sorted(accepted, key=lambda f: -by_name.get(f["name"], 0.0)):
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
lines.append(
f" {feature['name']} ({feature['kind']}): "
f"{by_name.get(feature['name'], 0.0):.1f}% importance, "
f"spread {column[dev].std():.2f}"
)
return "\n".join(lines)
# ----------------------------------------------------------------- the loop itself
class Discovery(NamedTuple):
"""Artifacts returned by the discovery loop."""
accepted: list[dict] # the question set it ended with
answers_for: dict # feature id -> (rows x levels) probabilities
snapshots: list[list[dict]] # the set as it stood at the end of each round
history: list[float] # dev CV error after each round
batches: list[tuple] # what each round sent, for the request table
journal: list[tuple] # every action and what became of it
def run_loop(
split: Split,
proposer: str,
rounds: int,
examples: int,
mode: str,
min_spread: float,
tolerance: float,
) -> Discovery:
"""Run the propose, answer, fit, and feedback loop."""
shown = example_rows(split, None, examples) # round 1 has nothing predicted yet
out_of_fold = previous = None
got_from = Discovery([], {}, [], [], [], [])
accepted, answers_for = got_from.accepted, got_from.answers_for
snapshots, history = got_from.snapshots, got_from.history
batches, journal = got_from.batches, got_from.journal
feedback = ""
for round_index in range(1, rounds + 1):
block = example_block(shown, split, out_of_fold, previous)
actions = propose(
proposer, round_index, proposal_prompt(block, feedback, accepted)
)["actions"]
keep, drops = to_candidates(actions, accepted, round_index)
if keep: # one request per row, carrying every question this round proposed
batches.append((round_index, plain(keep)))
answers = featurize(split.notes, plain(keep))
for feature in keep:
answers_for[feature["id"]] = answers[feature["name"]]
for (
feature
) in keep: # an add goes in; importance says later whether it earned it
if feature["replaces"]:
continue
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
flat = float(column[split.dev].std()) < min_spread
journal.append(
(round_index, "flat" if flat else "add", feature["name"], "")
)
if not flat:
accepted.append(
{k: feature[k] for k in ("id", "name", "kind", "question")}
)
_, cv = evaluate(accepted, answers_for, split, mode)
trial_args = (answers_for, split, mode, tolerance)
for feature in [f for f in keep if f["replaces"]]: # every revision is tried
trial = swap_in(accepted, feature)
if trial is None: # it revises something an earlier round already dropped
journal.append(
(round_index, "stale", feature["name"], "target is gone")
)
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
what = "revise" if took else "reject"
journal.append(
(
round_index,
what,
feature["name"],
f"was {feature['replaces']}, {note}",
)
)
for name in drops: # and so is every drop
trial = [f for f in accepted if f["name"] != name]
if not trial:
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
journal.append((round_index, "drop" if took else "keep", name, note))
previous, (out_of_fold, cv) = (
out_of_fold,
evaluate(accepted, answers_for, split, mode),
)
history.append(cv)
snapshots.append(list(accepted))
feedback = feedback_for(
history, accepted, answers_for, split, mode, out_of_fold, previous
)
# next round reads the rows these questions get most wrong, and as many they get right
shown = example_rows(split, out_of_fold, examples)
report(round_index, keep, drops, journal, accepted, cv)
return got_from
def report(
round_index: int,
keep: list[dict],
drops: list[str],
journal: list[tuple],
accepted: list[dict],
cv: float,
) -> None:
"""One block per round: the counts, the names it added, then everything with a number."""
revised = sum(1 for f in keep if f["replaces"])
print(
f"round {round_index}: {len(keep) - revised} add, {revised} revise, "
f"{len(drops)} drop"
)
this_round = [j for j in journal if j[0] == round_index]
added = [name for _, what, name, _ in this_round if what == "add"]
if added:
print(
textwrap.fill(
", ".join(added),
88,
initial_indent=" added ",
subsequent_indent=" " * 10,
)
)
for _, what, name, note in this_round: # everything carrying a number of its own
if what != "add":
print(f" {what:<7}{name:<34}{note}")
print(f" -> {len(accepted)} features, dev CV RMSE {cv:.3f}\n")
# ----------------------------------------------------------------- asking for the score
@json_cache
def ask_score(model: str, note: str) -> dict:
"""One `Score` over ten quality bands, read as a level and rescaled to 80-100."""
response = client.system_one(
state=note,
questions={
"quality": Score(
instructions=(
"Judging only by what this tasting note says, how good is the wine?"
),
criteria=SCORE_LEVELS,
)
},
model=model,
)
got = response.answers["quality"]
top = len(SCORE_LEVELS) - 1
expected = sum(k * v for k, v in got.probabilities.items())
return {
# level 0 is the bottom of the critic's scale, level 9 the top
"expected": 80.0 + 20.0 * expected / top,
"picked": 80.0 + 20.0 * got.score / top,
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
# ----------------------------------------------------------------- charts
SURFACE, INK, INK2, MUTED = "#fcfcfb", "#0b0b0b", "#52514e", "#898781"
GRID, AXIS, BLUE, ORANGE = "#e1e0d9", "#c3c2b7", "#2a78d6", "#eb6834"
def style(ax) -> None:
ax.set_facecolor(SURFACE)
for side in ("top", "right"):
ax.spines[side].set_visible(False)
for side in ("left", "bottom"):
ax.spines[side].set_color(AXIS)
ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
ax.set_axisbelow(True)
def polarity(feature: dict, answers_for: dict, split: Split) -> float:
"""Rank correlation between a question's answer and the critic score, on the dev rows.
Positive means a higher answer goes with a better review, negative the opposite. It is
what orders the rows of the feature map, so the map reads as a gradient that flips.
"""
column = encode(feature, answers_for[feature["id"]], "mean")[0][1]
return spearman(column[split.dev], split.scores[split.dev])
def reviews_heatmap(
plt,
questions: list[dict],
answers_for: dict,
split: Split,
rows: tuple,
):
"""Compare held-out reviews across the discovered questions, best-signal first.
Rows arrive sorted from the questions that rise with the score to the ones that fall with
it, so a row above the divider shades left to right and a row below it shades right to
left.
"""
def value_of(feature: dict, row: int) -> float:
return float(encode(feature, answers_for[feature["id"]], "mean")[0][1][row])
signs = [polarity(question, answers_for, split) for question in questions]
flip = next((i for i, s in enumerate(signs) if s < 0), len(questions))
raw = np.array(
[[value_of(question, row) for row in rows] for question in questions]
)
normalized = np.array(
[
values / (4 if question["kind"] == "intensity" else 1)
for question, values in zip(questions, raw)
]
)
cmap = matplotlib.colors.LinearSegmentedColormap.from_list(
"typesafe_heat", [SURFACE, "#f7c7ad", ORANGE]
)
fig, ax = plt.subplots(
figsize=(9.5, 1.8 + 0.58 * len(questions)), facecolor=SURFACE
)
image = ax.imshow(normalized, aspect="auto", cmap=cmap, vmin=0, vmax=1)
row_labels = []
for question, sign in zip(questions, signs):
kind = "score" if question["kind"] == "intensity" else "noul"
prefix = f"{sign:+.2f} ({kind}) "
lines = textwrap.wrap(
" ".join(question["question"].split()),
width=52,
max_lines=2,
placeholder="...",
break_long_words=False,
break_on_hyphens=False,
)
row_labels.append(prefix + (f"\n{' ' * len(prefix)}").join(lines))
column_labels = [
f"#{i}\n{split.scores[row]:.0f} points\n{' '.join(split.notes[row].split())[:15]}..."
for i, row in enumerate(rows, 1)
]
ax.set_yticks(np.arange(len(questions)), row_labels)
ax.set_xticks(np.arange(len(rows)), column_labels)
ax.tick_params(
axis="x", top=True, labeltop=True, bottom=False, labelbottom=False, pad=8
)
ax.tick_params(axis="y", labelsize=8.5)
for side in ax.spines.values():
side.set_visible(False)
ax.set_xticks(np.arange(-0.5, len(rows), 1), minor=True)
ax.set_yticks(np.arange(-0.5, len(questions), 1), minor=True)
ax.grid(which="minor", color=SURFACE, linewidth=2)
ax.tick_params(which="minor", bottom=False, left=False)
for i, question in enumerate(questions):
for j, value in enumerate(raw[i]):
label = (
f"{value:.1f}" if question["kind"] == "intensity" else f"{value:.2f}"
)
color = SURFACE if normalized[i, j] > 0.58 else INK2
ax.text(j, i, label, ha="center", va="center", color=color, fontsize=8)
# the line where the questions stop rising with the score and start falling with it
if 0 < flip < len(questions):
ax.axhline(flip - 0.5, color=INK, linewidth=1.2)
ax.annotate(
"a higher answer means a worse review, below this line",
(len(rows) - 0.5, flip - 0.5),
xytext=(-4, 5),
textcoords="offset points",
va="bottom",
ha="right",
color=INK2,
fontsize=8.5,
)
colorbar = fig.colorbar(image, ax=ax, fraction=0.025, pad=0.025)
colorbar.set_ticks([0, 0.5, 1])
colorbar.set_label("normalized answer", color=INK2, fontsize=8.5)
colorbar.ax.tick_params(labelsize=8, colors=INK2)
fig.suptitle(
"Every question, on five held-out reviews from worst to best",
x=0.01,
y=0.995,
ha="left",
color=INK,
fontsize=11,
)
fig.text(
0.01,
0.972,
"sorted by how the answer moves with the score, so each row above the line shades "
"left to right and each row below it shades the other way",
color=MUTED,
fontsize=9,
)
fig.text(
0.01,
0.005,
"Row labels lead with the rank correlation between that question's answer and the "
"critic score. Cell text is each question's native scale: score 0-4, noul 0-1.",
color=MUTED,
fontsize=8.5,
)
return fig
def rounds_chart(
plt, curve: list[tuple], history: list[float], n_test: int, gain: tuple
):
"""Dev error and held-out error per round. The trend is the point, not the gap."""
rounds = list(range(1, len(curve) + 1))
values = [v for _, v in curve]
fig, ax = plt.subplots(figsize=(7, 3.9), facecolor=SURFACE)
style(ax)
ax.grid(axis="y", color=GRID, linewidth=0.8)
# each dev fold trains on four fifths of the rows, so the dev line sits the higher of the two
ax.fill_between(rounds, history, values, color=GRID, alpha=0.75, linewidth=0)
ax.plot(
rounds,
history,
marker="o",
color=BLUE,
linewidth=2,
linestyle="--",
label="dev, cross-validated - what the loop optimises",
)
ax.plot(
rounds,
values,
marker="o",
color=ORANGE,
linewidth=2,
label="held out - what that actually buys",
)
# label each point on the outside of the pair, so neither line crowds its own numbers
for x, dev_value, test_value in zip(rounds, history, values):
for value, other in ((dev_value, test_value), (test_value, dev_value)):
ax.annotate(
f"{value:.2f}",
(x, value),
textcoords="offset points",
xytext=(0, 8 if value >= other else -16),
ha="center",
color=INK2,
fontsize=8.5,
)
ax.set_xticks(
rounds, [f"round {x}\n{n} features" for x, (n, _) in zip(rounds, curve)]
)
ax.set_ylabel("RMSE in points (lower is better)", color=INK2, fontsize=9)
# tight around the two lines: the whole finding lives inside 0.15 of a point
low, high = min(values + history), max(values + history)
ax.set_ylim(low - 0.10, high + 0.05)
difference, low_ci, high_ci = gain
ax.set_title(
f"{len(rounds)} rounds of the loop, scored on {n_test} held-out reviews",
loc="left",
color=INK,
fontsize=11,
pad=20,
)
# the number the chart is really about: is the held-out move bigger than the noise?
ax.text(
0,
1.015,
f"round 1 to round {len(rounds)}, held out: {difference:+.3f} points, "
f"95% CI [{low_ci:+.3f}, {high_ci:+.3f}]",
transform=ax.transAxes,
color=MUTED,
fontsize=9,
)
ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="lower left")
return figEinrichtung
pip install anthropic openai catboost numpy matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/dann TYPESAFE_API_KEY und ANTHROPIC_API_KEY festlegen. Jeder API-Aufruf wird in json_cache.json zwischengespeichert, das mit dem Kochbuch ausgeliefert wird, sodass ein erneutes Rendern diese Zahlen abspielt, ohne etwas aufzurufen. Löschen Sie es, um live erneut auszuführen. Die Zahlen stammen von TypeSafe jev-1.12 und claude-sonnet-5 vom 03.08.2026. propose() hat einen zweiten Zweig für gpt-5.6-luna, der nicht ausgeführt wurde.
Die erste Code-Zelle enthält die gesamte Implementierung: API-Aufrufe, Kodierungen, Metriken, Diagramm-Stil. Sie ist enthalten, damit diese Datei eigenständig ausgeführt werden kann, und die Dokumentationsseite blendet sie aus. Überspringen Sie sie beim ersten Lesen – das Rezept beginnt darunter.
N_DEV, N_TEST = 1200, 800  # the loop reads dev labels only; test is scored once
ROUNDS = 5  # a round answers questions for all 2,000 rows: 2,000 requests
PROPOSER = "claude-sonnet-5"  # or "gpt-5.6-luna"; the cache holds the Anthropic run
EXAMPLES = 60  # dev notes the proposer reads per round, half of them its worst misses
MIN_SPREAD = 0.05  # a column this flat cannot separate anything, so it is not kept
CHANGE_TOLERANCE = 0.0  # a revision or drop has to improve dev error, not just not hurt
ENCODING = "mean_spread"  # a score answer becomes two columns: its mean and spread

split = load_split(N_DEV, N_TEST, seed=0)
NOTES, SCORES, DEV, TEST = split.notes, split.scores, split.dev, split.test

print(
    f"{len(DEV)} dev rows, {len(TEST)} held out; scores run "
    f"{SCORES.min():.0f}-{SCORES.max():.0f}, mean {SCORES.mean():.2f}, sd {SCORES.std():.2f}"
)
print(f"\none of the notes:\n{NOTES[0]}")
1200 dev rows, 800 held out; scores run 80-98, mean 88.73, sd 3.17
one of the notes:
A Champagne that is very much wine. The structure and the richness are just right for a food wine, showing ripe acidity, flavors of plums and apricots, and balancing these primary fruits with a dense, complex structure that takes in yeast, maturity and a tight apple skin finish.Die Schleife liest dieselben 1.200 der 2.000 Zeilen (die Entwicklungszeilen) immer wieder und behält eine Frage bei, wenn sie dabei hilft, diese 1.200 Werte vorherzusagen. Eine Bewertung an denselben Zeilen würde größtenteils messen, wie gut sich die Schleife an sie angepasst hat, daher werden die anderen 800 zurückgehalten und am Ende einmal bewertet.
Zwei Fragetypen
Ein vorgeschlagene Frage ist eine von zwei Arten, und die Art bestimmt, welche Zahl zurückkommt.
intensitywird zu einemScore, für alles, was in Abstufungen vorliegt. Die fünf Stufen sind unten aufgeführt, und die Spalte ist der Durchschnittswert, sodass eine Notiz, die zwischen „mäßig“ und „stark“ liegt, zwischen den beiden ausgegeben wird.presencewird zu einemNoul, für eine Ja/Nein-Tatsache wie die Benennung eines Fehlers. Die Spalte ist diese eine Wahrscheinlichkeit.
Die Methode
questions <- {}
repeat for each round:
    notes  <- round 1 ? 60 dev notes across the score range
                      : the 30 worst-predicted dev notes + the 30 best,
                        each with its score, this prediction and the last
    actions <- LLM(brief, questions, notes, importance and error so far)
    answers[q] <- TypeSafe(note, all new questions of this round) for every row
    for each added q:      keep it unless its column is flat
    for each revised q:    refit; keep the change only if dev error drops
    for each dropped q:    refit; drop it only if dev error drops
    out_of_fold <- k-fold CatBoost on the columns   # judges, and picks next round's notes
Keine Frage wird vor der Beantwortung herausgefiltert. Alle Fragen einer Runde werden in derselben Anfrage gesendet, sodass eine zusätzliche Frage keine weitere Anfrage kostet. Eine Frage, die auf eine von zehn Zeilen zutrifft, wird in den 60 Notizen, die der Anbieter liest, nutzlos erscheinen, und ist dennoch die nützlichste Spalte im Satz.
k-fold bedeutet, die Dev-Reihen in k Teile aufzuteilen und jedes Teil mit einem Modell vorherzusagen, das auf den anderen Teilen trainiert wurde. Diese Vorhersagen erfüllen drei Aufgaben: Sie bewerten jede Überarbeitung und jeden Ausschluss, sie wählen die Notizen aus, die in der nächsten Runde gelesen werden, und sie teilen dem Vorschlagenden mit, welche seiner Fragen geholfen haben, indem sie anzeigen, wie weit sie sich seit der vorherigen Runde verändert haben.
print("every intensity question is graded on these five levels:\n")
for i, level in enumerate(INTENSITY_LEVELS):
    print(f"  {i}. {level}")
print("\nevery presence question is judged true or false against these:\n")
print(f"  true:  {PRESENCE_CRITERIA['true']}")
print(f"  false: {PRESENCE_CRITERIA['false']}")
print("\nthe brief the proposer works from:\n")
print("\n".join(PROPOSER_TASK.splitlines()[:6]) + "\n  ...")
every intensity question is graded on these five levels:
0. Not present in this note at all
1. Barely present - mentioned once, in passing
2. Present at a moderate level
3. Present strongly - the note dwells on it
4. Dominant - the note is largely about this
every presence question is judged true or false against these:
true: The note states this or clearly implies it
false: The note gives no indication of this
the brief the proposer works from:
You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to 18 actions. Each action is one of:
...Die Autoresearch-Schleife
run_loop führt alle fünf Runden durch und gibt einen Block pro Runde aus. Eine hinzugefügte Frage wird direkt eingegeben: Ihre Antworten wurden bereits abgerufen, und ihre Bedeutung wird später zeigen, ob es sich gelohnt hat, sie zu stellen. Eine Überarbeitung oder ein Auslassen nimmt einer Spalte, die das Modell bereits nutzt, weg, daher wird jede zuerst ausprobiert: Nachanpassung mit der Änderung, und behalten Sie sie nur, wenn der Dev-Fehler sinkt. Eine Nachanpassung kostet keine API-Aufrufe, daher ist es kostenlos, eine Änderung auszuprobieren und sie abzulehnen.
run = run_loop(
    split, PROPOSER, ROUNDS, EXAMPLES, ENCODING, MIN_SPREAD, CHANGE_TOLERANCE
)
accepted, answers_for = run.accepted, run.answers_for
snapshots, history = run.snapshots, run.history
round 1: 18 add, 0 revise, 0 drop
added complexity, fruit_intensity, tannin_structure, acidity_intensity,
oak_intensity, finish_length, balance_harmony, aging_potential,
positive_superlative_language, negative_critical_language,
drinkability_easiness, body_richness, sweetness_level, texture_descriptors,
earthy_savory_notes, flaw_or_defect_mentioned,
single_vineyard_or_prestige_signal, varietal_blend_detail
-> 18 features, dev CV RMSE 1.903
round 2: 5 add, 3 revise, 3 drop
added power_concentration_language, flavor_distinctiveness, generic_fruit_language,
candied_artificial_flavor, rustic_authentic_character
reject oak_dominance was oak_intensity, would cost +0.005
revise negative_critical_language was negative_critical_language, CV 1.897 -> 1.894
revise single_vineyard_or_prestige_signalwas single_vineyard_or_prestige_signal, CV 1.894 -> 1.881
keep finish_length would cost +0.009
keep texture_descriptors would cost +0.001
keep varietal_blend_detail would cost +0.023
-> 23 features, dev CV RMSE 1.881
round 3: 7 add, 2 revise, 1 drop
added elegance_finesse_language, minerality_precision_language,
hedged_qualified_praise, underripe_green_character,
reviewer_overall_verdict_strength, unusual_or_funky_descriptor_valence,
botrytis_or_special_winemaking_signal
revise negative_critical_language was negative_critical_language, CV 1.868 -> 1.864
revise finish_quality was finish_length, CV 1.864 -> 1.861
keep candied_artificial_flavor would cost +0.014
-> 30 features, dev CV RMSE 1.861
round 4: 5 add, 2 revise, 3 drop
added excess_or_imbalance_signal, descriptive_detail_density,
critic_enthusiasm_confidence, savory_food_wine_seriousness,
note_overall_tone_positivity
revise rustic_authentic_character was rustic_authentic_character, CV 1.843 -> 1.838
reject hedged_qualified_praise was hedged_qualified_praise, would cost +0.014
keep botrytis_or_special_winemaking_signalwould cost +0.011
keep candied_artificial_flavor would cost +0.009
keep unusual_or_funky_descriptor_valencewould cost +0.010
-> 35 features, dev CV RMSE 1.838
round 5: 4 add, 2 revise, 8 drop
added structural_seriousness, youthful_tension_signal, surface_prettiness_vs_depth,
price_value_signal
reject unconventional_character_as_virtuewas rustic_authentic_character, would cost +0.010
revise flavor_distinctiveness was flavor_distinctiveness, CV 1.849 -> 1.843
keep candied_artificial_flavor would cost +0.002
keep botrytis_or_special_winemaking_signalwould cost +0.003
keep hedged_qualified_praise would cost +0.006
keep excess_or_imbalance_signal would cost +0.005
drop underripe_green_character CV 1.843 -> 1.840
keep unusual_or_funky_descriptor_valencewould cost +0.002
keep texture_descriptors would cost +0.001
keep generic_fruit_language would cost +0.000
-> 38 features, dev CV RMSE 1.840Auf deine eigenen Daten zeigen
PROPOSER_TASK ist die einzige Zeichenkette, die Wein erwähnt, und featurize() nimmt eine beliebige Liste von
Zeichenketten entgegen. Die Bearbeitung dieser kurzen Beschreibung ändert den Proposal-Prompt, und der Prompt ist Teil des
Cache-Schlüssels, sodass der nächste Lauf für jede Runde die API erneut aufruft.
Die Anzahl der Anfragen steigt mit den Zeilen, nicht mit den Fragen: eine Anfrage pro Zeile pro Runde, also sind 100.000 Zeilen 100.000 Anfragen pro Runde. Eine Überarbeitung zählt als neue Frage, sodass sie einen weiteren Durchlauf über jede Zeile kostet. Erhöhe den Worker-Pool langsam. Acht sind bereits genug, um ein Rate-Limit bei einem gemeinsamen Schlüssel zu treffen.
Was die Fragen sehen
Fünf zurückgehaltene Bewertungen, eine in jedem Viertel des Score-Bereichs, gegenüber fünfzehn der 38 Fragen: die acht Score-Fragen nach Wichtigkeit, plus die sieben Top-Noul.
Die fünfzehn Zeilen werden dann danach sortiert, in welche Richtung die Antwort mit dem Kritiker-Score wechselt. Fragen, deren Antwort mit dem Score steigt, kommen zuerst, Fragen, deren Antwort damit fällt, kommen nach dem Trenner. Also von links nach rechts, von der schlechtesten Bewertung zur besten, sollten die Antworten oberhalb des Trenners steigen und die darunterliegenden sollten abfallen.
X, labels = design(accepted, answers_for, ENCODING)
column_importances = importances(X[DEV], SCORES[DEV])
# an encoding gives a feature more than one column, so add a feature's columns back up
feature_importances = importance_per_feature(accepted, labels, column_importances)
ranked = sorted(accepted, key=lambda f: -feature_importances[f["name"]])
score_questions = [f for f in ranked if f["kind"] == "intensity"][:8]
noul_questions = [f for f in ranked if f["kind"] == "presence"][:7]
# ordered by which way the answer moves with the score, so the map flips halfway down
heatmap_questions = sorted(
    score_questions + noul_questions,
    key=lambda f: -polarity(f, answers_for, split),
)
ordered_test = TEST[np.argsort(SCORES[TEST], kind="stable")]
positions = np.linspace(0, len(ordered_test) - 1, 5).round().astype(int)
review_rows = tuple(ordered_test[positions])

print("the five held-out heatmap columns:\n")
for i, row in enumerate(review_rows, 1):
    excerpt = " ".join(NOTES[row].split())
    print(f"  {i}. {SCORES[row]:.0f} points: {excerpt[:100]}...")

fig = reviews_heatmap(plt, heatmap_questions, answers_for, split, review_rows)
display(fig)
plt.close(fig)
the five held-out heatmap columns:
1. 80 points: Raw cherry and plum aromas are resiny and suggest wet cement. This is shearing and so jacked up with...
2. 86 points: A slight spritz brightens the mouthfeel of this lemony wine. Aromas are a bit musky, but flavors of ...
3. 89 points: This is a European-style Syrah, cofermented with 2% Viognier. It's soft and round, medium in body, a...
4. 91 points: From the producer's dry-farmed estate vineyard, and supported by small amounts of Merlot and Caberne...
5. 97 points: A thoroughly elegant, serious and yet immensely enjoyable wine that stays lively many days after ope...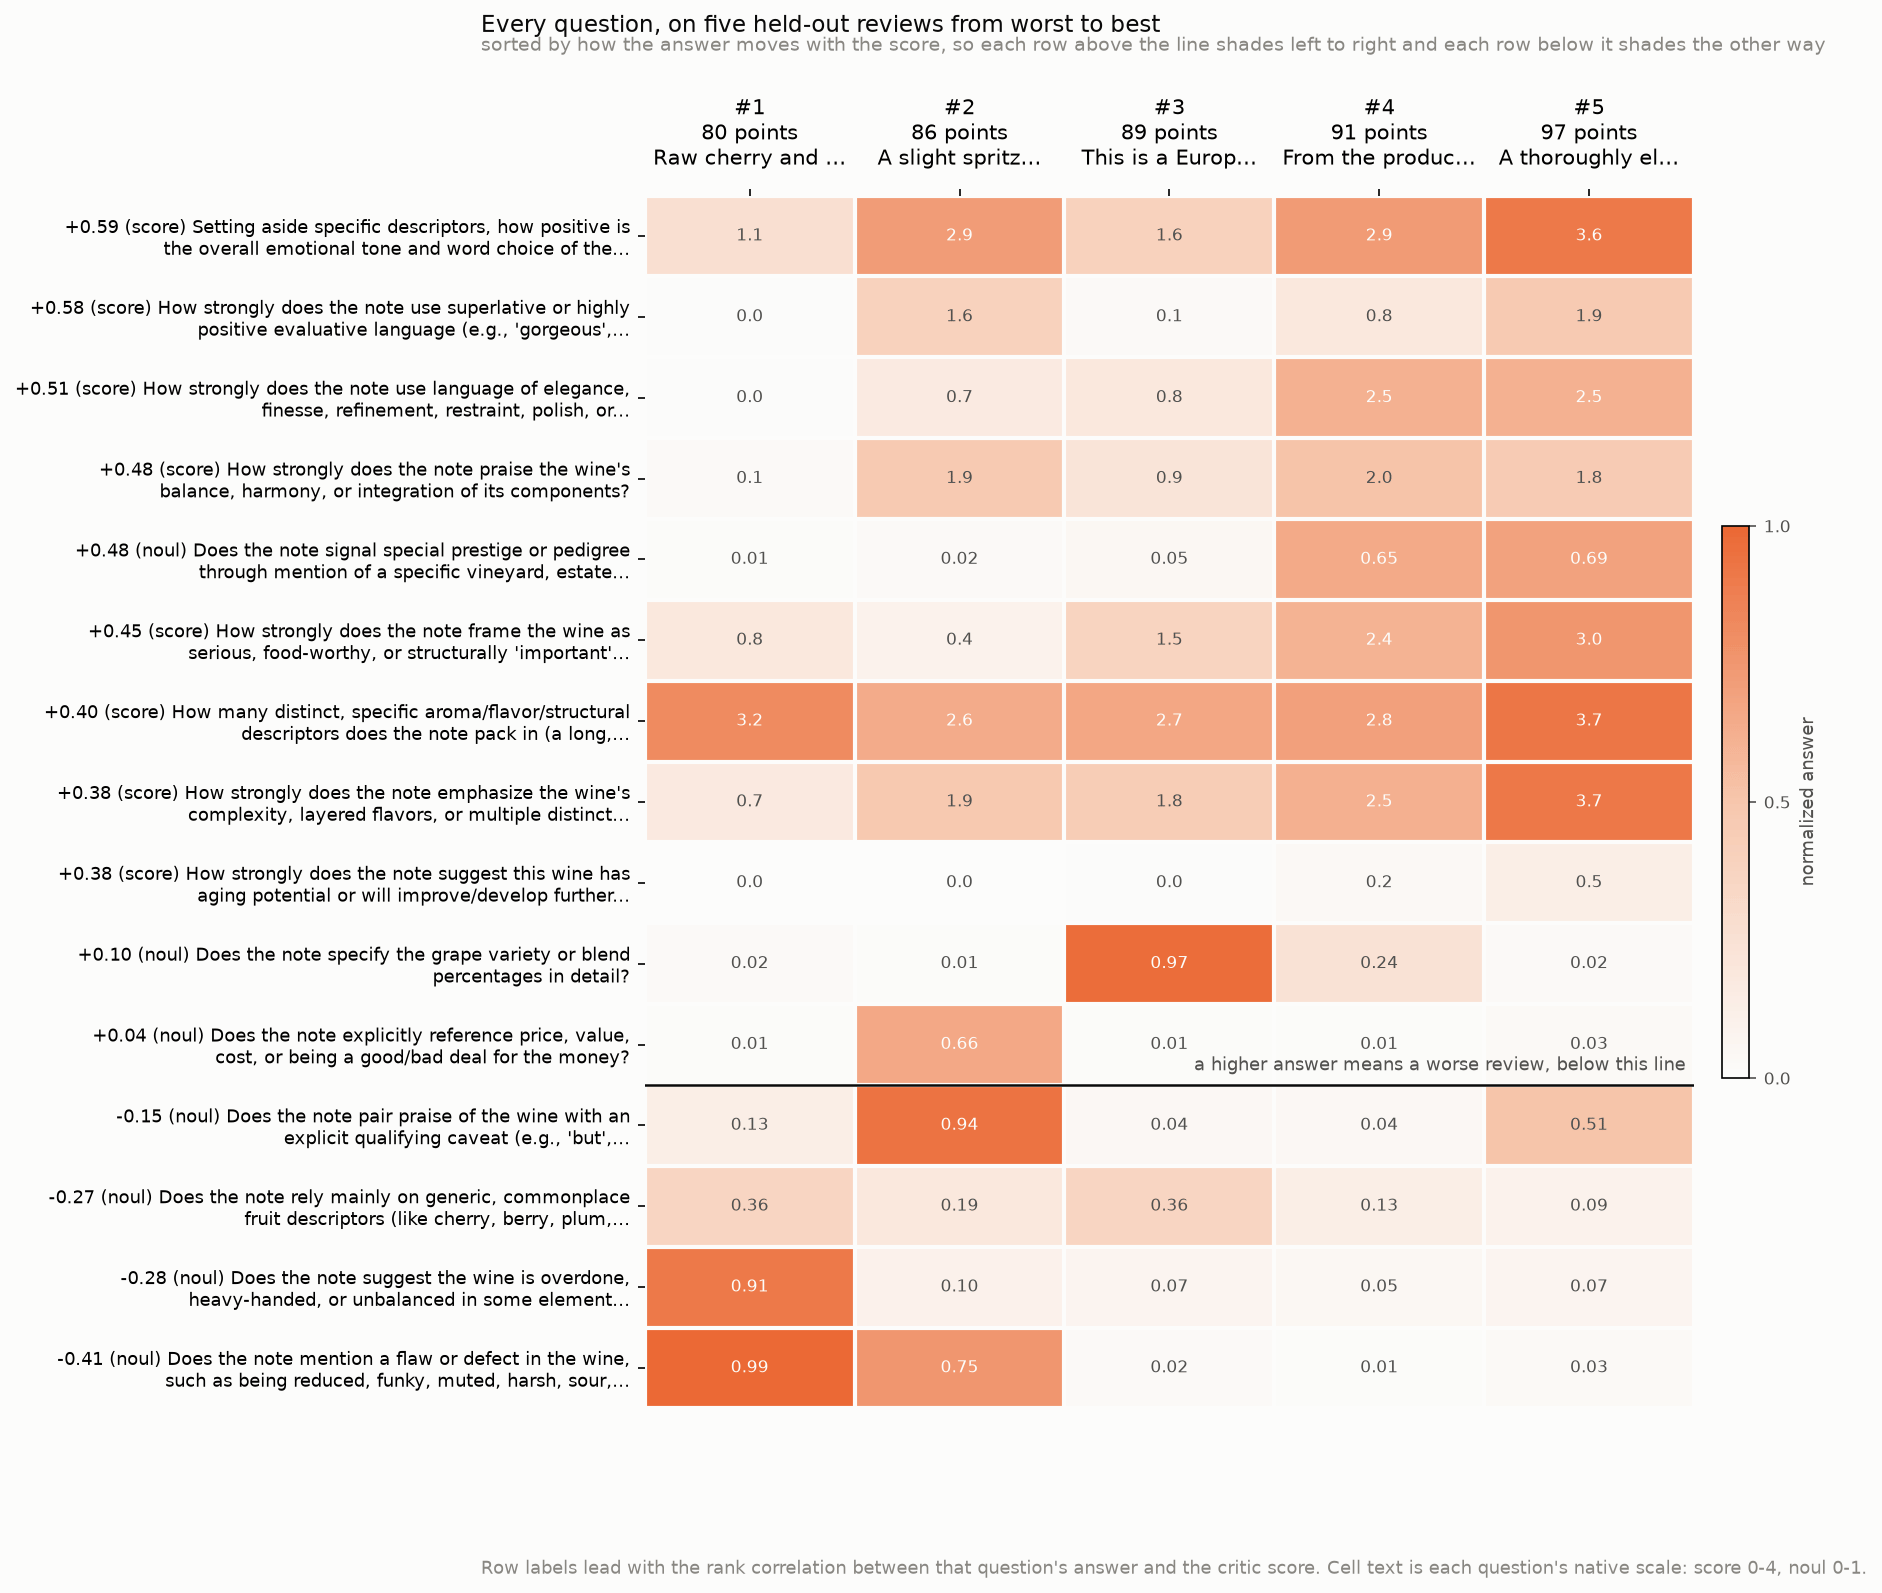
Die Tabelle von der Seite oben, berechnet. Alle fünf Arme werden einmal auf denselben 800
held-out Zeilen bewertet, und die ersten drei überspringen die Feature-Entdeckung. Einer sagt den Mittelwert der dev
Scores voraus und liest überhaupt nichts aus der Notiz. Eine reicht die Notiz an denselben CatBoost
durch deren text_features-Verarbeitung, was sie in Wortzählungen umwandelt. Eine fragt TypeSafe
nach dem Score selbst.
Der dritte Punkt ist ein einzelnes Score pro Zeile über zehn Qualitätsstufen, von „fehlerhaft oder unangenehm“ bis hin zu „tiefgründig“. Zehn, weil eine Score-Frage maximal zehn Stufen abdeckt –
elf führt zu einem Serverfehler. Stufe 0 entspricht 80 Punkten und Stufe 9 entspricht 100.
Die Aufteilung der Stufen auf die Skala allein reicht nicht aus, da in der Frage nicht steht,
wo die Scores dieser Publikation tatsächlich auf der Skala liegen. Daher wird jede Antwort
um einen einzelnen Offset verschoben, gemessen an den Dev-Scores. Dieser Offset wird in der
Zeilenbezeichnung ausgegeben, und er ist das Einzige, was dieser Shortcut aus den Scores lernt.
Spearman ist die Rangkorrelation, wobei 1.0 die zurückgehaltenen Weine exakt in der Reihenfolge des Kritikers platzieren würde. Die Zeile zur Wortanzahl stammt aus CatBoosts eigener Textverarbeitung und ist keine abgestimmte Textregressionspipeline. All dies bezieht sich auf einen einzigen Datensatz und einen einzigen Durchlauf der Schleife.
predicted = fit_predict(X, split)
text_predicted = fit_predict_text(split)

# ask TypeSafe for the score itself, one request per row
with ThreadPoolExecutor(max_workers=8) as pool:
    direct = list(pool.map(lambda note: ask_score(TYPESAFE_MODEL, note), NOTES))
asked = np.array([d["expected"] for d in direct])
shift = float(SCORES[DEV].mean() - asked[DEV].mean())  # one number, from the dev labels

# what one proposal call gets you, before any feedback: the set round 1 ended with
first_round, _ = design(snapshots[0], answers_for, ENCODING)

print(f"{'arm':<46}{'RMSE':>7}{'spearman':>10}")
for label, p in (
    ("predict the mean of the dev rows", np.full(len(TEST), SCORES[DEV].mean())),
    ("the note as word counts, same CatBoost", text_predicted),
    (f"ask for the score itself, shifted {shift:+.2f}", asked[TEST] + shift),
    (
        f"{len(snapshots[0])} questions from round 1, no loop",
        fit_predict(first_round, split),
    ),
    (f"{len(accepted)} questions after all {ROUNDS} rounds", predicted),
):
    print(f"{label:<46}{rmse(SCORES[TEST], p):>7.3f}{spearman(SCORES[TEST], p):>10.3f}")
arm RMSE spearman
predict the mean of the dev rows 3.088 -0.014
the note as word counts, same CatBoost 2.466 0.605
ask for the score itself, shifted -1.71 2.145 0.761
18 questions from round 1, no loop 1.869 0.778
38 questions after all 5 rounds 1.772 0.799Haben die Autoresearch-Runden geholfen?
Beide Linien zeigen den Fehler des Fragebogens am Ende jeder Runde, beginnend mit dem ersten Vorschlag. Die gestrichelte Linie ist der kreuzvalidierte Entwicklungsfehler, auf den jede Annahme- und Ablehnungsentscheidung basiert. Die durchgezogene Linie bewertet denselben Fragebogen an den zurückgehaltenen Zeilen, auf die die Schleife niemals zugreift. Jeder Punkt repräsentiert den Fragebogen in dem Zustand, in dem er sich befand, als die Runde geschlossen wurde, sodass eine Runde, die nur eine Frage überarbeitet oder entfernt hat, beide Linien verschiebt. Die Merkmalszuordnung sagt aus, was die Fragen messen; der Fehler zeigt, ob die Runden nach dem ersten Vorschlag die Vorhersagen verbessert haben.
Die Achse ist eng: Alles darauf passiert innerhalb einer halben Minute, und jeder Shortcut aus der obigen Tabelle liegt weit oberhalb davon. Die Dev-Linie verläuft die gesamte Strecke über der gehaltenen Linie, und das ist ein Training-Größe-Effekt. Jeder Dev-Fold trainiert auf vier Fünfteln der Dev-Zeilen, während die gehaltene Zahl von einem Modell stammt, das alle 1.200 erhalten hat. Die beiden Linien bewegen sich zusammen, sodass die Dev-Zahl, nach der die Schleife steuert, die gehaltene Zahl verfolgt, die sie nie sieht. Das Intervall unter dem Titel stammt aus dem Resampling der gehaltenen Zeilen, also sagt es, ob die Bewegung von Runde 1 zu Runde 5 größer ist als das Rauschen in 800 Zeilen.
curve, per_round = [], []
for features in snapshots:
    X_round, _ = design(features, answers_for, ENCODING)
    per_round.append(fit_predict(X_round, split))
    curve.append((len(features), rmse(SCORES[TEST], per_round[-1])))

# the same held-out rows resampled 2,000 times, both arms scored on each resample
gain = paired_gain(SCORES[TEST], per_round[0], per_round[-1])
print(
    f"round 1 -> round {ROUNDS} on the held-out rows: {gain[0]:+.3f} points, "
    f"95% CI [{gain[1]:+.3f}, {gain[2]:+.3f}]"
)

fig = rounds_chart(plt, curve, history, len(TEST), gain)
display(fig)
plt.close(fig)
round 1 -> round 5 on the held-out rows: -0.097 points, 95% CI [-0.147, -0.050]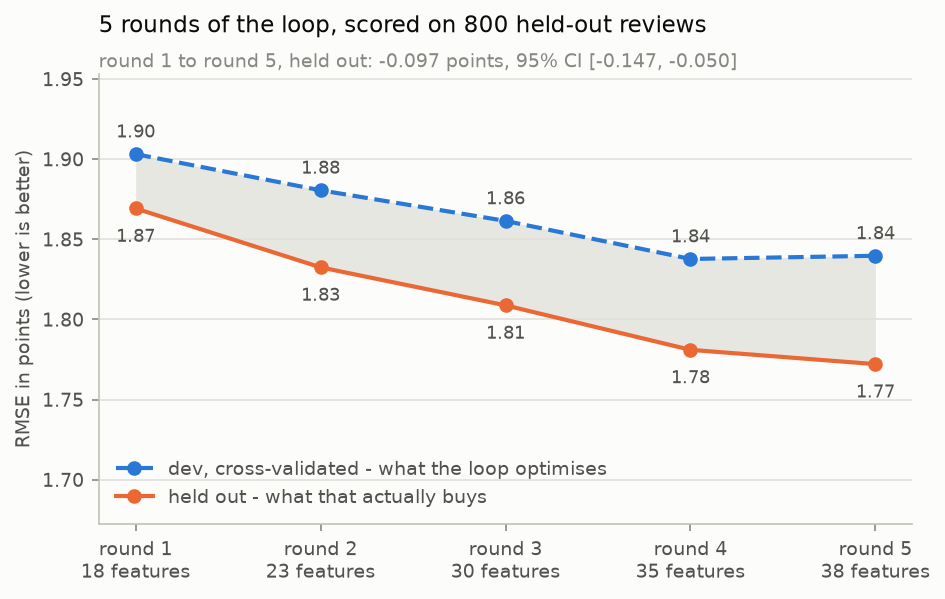
Die gehaltene Zeile fällt stärker aus als die Dev-Zeile. Runde 1 schrieb ihre Fragen ohne Feedback als Grundlage, und die vier darauffolgenden Runden haben einen Wert von 0,10 Punkten auf den gehaltenen Zeilen, 95% KI [-0,147, -0,050].
Runde 5 schlug vier Ergänzungen, zwei Umformulierungen und acht Streichungen vor und lieferte die erste Dev-Zahl, die keine Verbesserung darstellte. Man kann bei einer 245 Zeichen langen Notiz nur so viel fragen, und bis Runde 5 hatten sich die Vorschläge von der Hinzufügung von Fragen hin zu deren Streichung verschoben.
kinds = {f["name"]: f["kind"] for f in accepted}
print("feature importance share: % of total CatBoost importance across all questions")
print(f"{'feature':<38}{'asked as':<10}{'importance share':>16}")
for name, importance_share in sorted(feature_importances.items(), key=lambda p: -p[1])[
    :12
]:
    kind = "score" if kinds[name] == "intensity" else "noul"
    print(
        f"{name[:36]:<38}{kind:<10}{importance_share:>8.1f}%  "
        f"{'#' * round(importance_share)}"
    )
counts = f"{sum(1 for k in kinds.values() if k == 'intensity')} score"
counts += f", {sum(1 for k in kinds.values() if k == 'presence')} noul"
print(f"\nthe {len(accepted)} questions the loop kept: {counts}")
top = max(feature_importances, key=feature_importances.get)
print(
    f'the question behind the top row:\n  {top}: "{owner_of(top, accepted)["question"]}"'
)
feature importance share: % of total CatBoost importance across all questions
feature asked as importance share
note_overall_tone_positivity score 17.4% #################
savory_food_wine_seriousness score 8.7% #########
positive_superlative_language score 8.4% ########
single_vineyard_or_prestige_signal noul 7.2% #######
descriptive_detail_density score 5.7% ######
elegance_finesse_language score 5.0% #####
complexity score 5.0% #####
aging_potential score 5.0% #####
balance_harmony score 2.9% ###
drinkability_easiness score 2.9% ###
critic_enthusiasm_confidence score 2.7% ###
flavor_distinctiveness score 2.6% ###
the 38 questions the loop kept: 29 score, 9 noul
the question behind the top row:
note_overall_tone_positivity: "Setting aside specific descriptors, how positive is the overall emotional tone and word choice of the note taken as a whole (warm, admiring language throughout vs. flat, neutral, or lukewarm phrasing)?"importance share ist die CatBoost-Funktionswichtigkeit, normiert, sodass sich die 38 Fragen auf 100 % summieren. Es handelt sich nicht um einen Anteil an Zeilen, Fragen oder Vorhersagegenauigkeit. Eine Score-Frage besitzt zwei Spalten, einen Mittelwert und eine Streuung, daher werden die Wichtigkeiten ihrer beiden Spalten vor der Ausgabe des Prozentsatzes wieder addiert. note_overall_tone_positivity macht 17,4 % der Gesamtsumme aus. Die vierte Zeile ist ein Noul: Ob der Hinweis einen einzelnen Weinberg oder ein anderes Prestigesignal benennt, ist eine Ja/Nein-Tatsache, daher wurde sie als eine einzige Frage gestellt.
Nächste Schritte
Dieser Durchlauf hält die Schleife klein. Direkte Erweiterungen:
- Prüfen Sie einen Kandidaten, bevor Sie dafür bezahlen, ihn zu beantworten. Betrachten Sie die vorgeschlagene Frage selbst als den Zustand und fragen Sie Noul danach: Kann sie aus dem Quelltext beantwortet werden, bedeutet sie unter ihren Kriterien genau eines, gilt sie für die meisten Zeilen, wird sie sich über die Zeilen hinweg unterscheiden. Senden Sie nur die Fragen, die alle vier Kriterien mit ausreichender Sicherheit bestehen.
- Kürzen Sie korrelierte Merkmale. Messen Sie die Korrelation zwischen kodierten Spalten an den Entwicklungsdaten, clustern Sie die nahezu Duplikate und behalten Sie die klarste oder wichtigste Frage aus jedem Cluster bei.
- Fügen Sie einfache Baselines hinzu. Vergleichen Sie TF-IDF, Zeichenzahlen und andere strukturelle Merkmale isoliert, fügen Sie sie dann zu den entdeckten Spalten hinzu und messen Sie, was jeder einzelne beiträgt.
- Mischen Sie Antragsteller-Familien. Generieren Sie Kandidaten-Batches mit Anthropic, OpenAI, Google Gemini und Open-Source-Modellen, verschmelzen und deduplizieren Sie sie dann, bevor irgendeines von ihnen TypeSafe erreicht. Verschiedene Familien sollten die Suche breiter machen als wiederholte Aufrufe eines einzelnen Antragstellers.
- Vergleichen Sie prädiktive Modelle und Methoden. Probieren Sie lineare oder Elastic-Net-Regression, einen Support-Vector-Regressor, Random Forests und Rekalibrierung aus, wenn die nachgelagerte Ausgabe probabilistisch ist. Prüfen Sie, ob die entdeckten Merkmale auch außerhalb von CatBoost helfen.
- Fügen Sie eine Embedding-Baseline hinzu. Ein Embedding verwandelt eine Notiz in ein paar hundert Zahlen ohne angehängte Frage:
sentence-transformers/all-MiniLM-L6-v2läuft lokal, OpenAI’stext-embedding-3-smallist ein gehosteter Aufruf. Hängen Sie eines an die entdeckten Spalten und messen Sie, ob es etwas trägt, das sie nicht haben. - Passen Sie die Validierung an die Bereitstellung an. Verwenden Sie chronologische Aufteilungen, wenn Sie die Zukunft vorhersagen, gruppierte Aufteilungen, wenn verwandte Zeilen zusammen bleiben müssen, und bewahren Sie einen finalen Testset unberührt von sowohl der Merkmalsentdeckung als auch der Modellauswahl.
- Stoppen Sie auf einem Plateau. Beenden Sie die Schleife, wenn die kreuzvalidierte RMSE über eine feste Anzahl von Runden nicht mehr verbessert, oder wenn sie ein Fragen- oder Anfrage-Budget erreicht.
- Führen Sie eine längere Suche im Goal-Modus eines Agents durch. Geben Sie ihm eine explizite Metrik, ein Budget und eine Abbruchregel, lassen Sie ihn dann mehr Runden vorschlagen, auswerten und verfeinern.
- Prüfen Sie die Stabilität. Wiederholen Sie die Entdeckung über verschiedene Seeds oder Datenschnitte hinweg und behalten Sie die Fragen bei, die nützlich bleiben, anstatt die, deren Bedeutung auf einer einzigen Aufteilung beruht.
Öffnen Sie es im Playground
Dieser Freigabelink enthält eine Verkostungsnotiz sowie alle Fragen, die die Schleife am Ende ergeben hat.
playground_link = make_playground_link(
    NOTES[0], feature_questions(accepted), models=[TYPESAFE_MODEL]
)
display(
    Markdown(
        f"🔗 [Open the note + questions in the TypeSafe playground]({playground_link})"
    )
)