 JevCode
자기 일관성: 선택
검토 결정에 불확실한 결과를 추가하고, 라벨 간 일치율을 자동 조치 비율과 비교한다.
이 문서는 en에서 기계 번역되었으며 교정되지 않았습니다. 빠른 참고용으로만 사용하세요.

이 쿡북은 경계선상의 사용자 게시글 하나를 가져와서 15회에 걸쳐 모더레이션 기준을 적용하고, 각 답변이 반복 동안 일관되게 유지되는지 확인합니다. 각 검사는 Choice이므로, 각 답변은 고정된 세트에서 하나의 라벨을 가집니다. 모더레이션 파이프라인에서 이 라벨은 라우팅 결정입니다: 삭제하거나 게시 유지, 에스컬레이션하거나 자동 해결, 위협, 스팸 또는 일반 큐로 전송. 라벨이 한 실행에서 다음 실행으로 흔들리면, 동일한 게시글이 별다른 이유 없이 서로 다른 위치로 라우팅됩니다.
루브릭은 8 Choice개의 질문으로 구성되며, 각 실행은 8개 모두에 답변하는 단일 호출입니다. 우리는 조건당 15번 반복하며, 여기서 조건은 하나의 모델과 하나의 설정을 의미하고, 반환된 모든 라벨을 플롯합니다.
조건:
- 비추론형 LLM
claude-haiku-4-5및gpt-5.4-mini, 온도0및 API 기본값 사용. - 추론형 LLM
gpt-5.5및claude-opus-4-8, 온도 조절 기능이 없음. - TypeSafe: 8개의
Choice질문 중 한 번의system_one호출, 각 호출마다 noul 쿡북 설정과 일치하는 새로운uid필드(일회용 고유 값) 사용.
무엇을 살펴봐야 할지: 선택된 레이블은 TypeSafe를 포함한 단일 조건 내에서 뒤집힐 수 있으며, 조건들끼리 서로 모순될 수 있습니다.
이번 실행에서 LLM 분포 설정은 TypeSafe의 90.8%와 비교하여 87.5%에서 100%의 확률로 다수 라벨을 반복합니다. TypeSafe는 여섯 가지 LLM 분포 조건 중 다섯 가지보다 평균 확률 변동이 낮습니다. Haiku는 온도 0에서 변동이 더 적습니다. 확률이 근접해도 라우팅 변경은 가능합니다: TypeSafe는 8개 질문 중 2개에서 전환됩니다.
애플리케이션 결정에는 최소 0.60의 상위 확률이 필요하며, 그렇지 않으면 결과는 uncertain로 처리되어 인간 검토로 넘어갑니다. TypeSafe의 동의율은 99.2%까지 상승하며, 답변의 74.2%에 대해 자동 라벨이 적용됩니다. 우리는 원본 출력을 표시하고 LLM 확률 조건에도 동일한 임계값을 적용하여, 보류 및 변경 사항을 가시적으로 유지합니다.
설정
pip install anthropic openai matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/then set TYPESAFE_API_KEY, ANTHROPIC_API_KEY, and OPENAI_API_KEY.
This run uses jev-latest on the production API, sampled on 2026-09-11.
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean

from time import perf_counter

import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Choice, TypeSafeClient

matplotlib.use("Agg")  # headless render

BASE_MODELS = [
    "claude-haiku-4-5",
    "gpt-5.4-mini",
]  # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
    "gpt-5.5",
    "claude-opus-4-8",
]  # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest"  # the TypeSafe model
NUM_SAMPLES = 15  # repeated post+rubric calls per condition
MIN_CHOICE_PROBABILITY = 0.60  # illustrative automatic-action threshold

LLM_PRICES = {  # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
    "claude-haiku-4-5": (1.00, 5.00),
    "gpt-5.4-mini": (0.75, 4.50),
    "gpt-5.5": (5.00, 30.00),
    "claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00)  # Historical TypeSafe rate, as of 2026-08

anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
    api_key=os.environ["TYPESAFE_API_KEY"],
    base_url="https://api.typesafe.ai",
    timeout=30.0,
)
상태: 경계선 사용자 게시글, JSON 형식
아래 게시물은 중립을 지키도록 구성되어 있다. 언어는 격앙되고 모욕적이며, 한 사람을 겨냥한 부분과 논쟁 및 커뮤니티를 겨냥한 부분이 혼재되어 있다. 이 게시물은 플랫폼 외부로의 초대(다른 사이트로 유입시키는 링크)를 포함하고 있으며, 해당 계정에는 과거 한 번의 경고 이력이 있고, 네 건의 사용자 신고가 접수되었으며, 위협적으로 읽힐 수 있는 표현이 명확하게 정리되지 않았다.
여기에는 명확한 정답이 하나 있는 것은 아니며, 그것이 핵심입니다: 작은 어휘 차이는 동일한 게시물을 강제 처리 경로 간에 무작위로 이동시켜서는 안 됩니다.
LLM에는 json.dumps(POST)가 프롬프트로 전달됩니다. TypeSafe에는 Python 딕셔너리가 직접 전달됩니다.
POST = {
    "post_id": "P-88213",
    "author": {
        "user_id": "u/4471",
        "account_age_days": 38,
        "prior_strikes": 1,
        "followers": 210,
    },
    "context": {
        "surface": "public reply",
        "in_reply_to": "another user defending a game patch",
        "community": "r/gamedebates",
    },
    "content": {
        "text": (
            "Are you seriously this dense? Anyone who defends that patch is a complete clown and "
            "should be embarrassed to even post here. People like you are what's ruining this "
            "community and honestly you need to be dealt with. Come say it to my face, invite's "
            "right here. Keep it up and I'll end your whole channel."
        ),
        "has_link": True,
        "link_domain": "discord.gg",
        "language": "en",
    },
    "reports": {"user_reports": 4, "report_reasons": ["harassment", "spam", "threat"]},
}
평가 기준: 8 Choice 질문
각 질문에는 key, 지침 문장, 그리고 고정된 라벨 세트가 포함됩니다. 질문 내 라벨들은 상호 배타적(정확히 하나만 적용)이며, 각각 짧은 설명을 갖습니다. TypeSafe는 선택된 choice과 라벨들에 대한 probabilities 분포를 반환합니다. LLM들은 동일한 라벨 세트를 사용하도록 요청받으며, 이는 모든 행을 비교 가능하게 유지합니다.
QUESTIONS = {
    "category": (
        "What is the single most applicable content-policy category for this post?",
        {
            "None": "No policy violation of any kind.",
            "Harass": "Insults or demeans a person, with no threat of harm and no protected-class attack.",
            "Hate": "Attacks a person or group over a protected characteristic (race, religion, gender, ...).",
            "Violence": "Makes a credible threat of harm or incites violence against someone.",
            "Spam": "Unsolicited promotion or link spam, with no personal attack.",
            "Sexual": "Sexual or adult content.",
        },
    ),
    "primary_risk": (
        "What is the primary moderation risk that should drive triage for this post?",
        {
            "Harassment": "Personal attack or targeted abuse is the main risk.",
            "Violence": "A threat of harm or intimidation is the main risk.",
            "LinkAbuse": "External-link or off-platform coordination risk is the main risk.",
            "AccountHistory": "Prior account history or repeat behavior is the main risk.",
            "LowRisk": "No meaningful moderation risk is present.",
        },
    ),
    "target": (
        "Who or what is the content primarily directed at?",
        {
            "None": "Not directed at anyone in particular.",
            "Person": "Directed at one specific individual.",
            "Group": "Directed at a protected group or class.",
            "Platform": "Directed at the community or platform itself, not a person.",
        },
    ),
    "action": (
        "What enforcement action should be taken on this post?",
        {
            "Allow": "Leave the post up with no action.",
            "Warn": "Leave the post up but attach a warning label.",
            "Remove": "Remove the post, but do not penalize the account.",
            "Strike": "Remove the post and add a strike to the account.",
            "Escalate": "Take no automated action; hold for a human decision.",
        },
    ),
    "queue": (
        "Which single moderation queue should own this post?",
        {
            "Auto": "Auto-resolve; no human queue needed.",
            "General": "General moderation queue.",
            "Threat": "Threat / violence response queue.",
            "Spam": "Spam and platform-abuse queue.",
            "TSLead": "Trust-and-safety lead / senior queue.",
        },
    ),
    "link_handling": (
        "How should any external link or off-platform invite in the post be handled?",
        {
            "Allow": "Leave the link in place.",
            "RmLink": "Strip or disable the link but keep the post.",
            "Brigade": "Treat the link as coordinated brigading and action it as abuse.",
            "Escalate": "Send the link to a specialist to assess before acting.",
        },
    ),
    "review_path": (
        "Who should make the final call on this post?",
        {
            "Auto": "Automated action; no human review.",
            "Human": "A frontline human moderator makes the call.",
            "Senior": "A senior or specialist reviewer is required.",
            "Legal": "Route to legal or law-enforcement escalation.",
        },
    ),
    "severity": (
        "What is the overall severity of this post?",
        {
            "None": "No violation.",
            "Low": "Rude or dismissive, but essentially harmless.",
            "Medium": "Personal harassment with no clearly credible threat.",
            "High": "Harassment together with a threat that could be read as credible.",
        },
    ),
}
우리가 어떻게 묻는가
각 LLM 호출은 json.dumps(POST), 8개의 모든 질문, 그리고 허용된 모든 라벨을 포함하는 하나의 프롬프트입니다. 답변 형식은 두 가지가 있습니다. 분산 모드에서는 모델이 각 질문마다 각 라벨에 대한 확률을 포함한 하나의 JSON 객체를 반환합니다. 단일 선택 모드에서는 각 질문마다 하나의 원시 라벨을 반환하며, 우리의 분석은 해당 라벨에 모든 확률 질량을 할당합니다.
TypeSafe 호출은 동일한 게시글과 동일한 8개의 Choice 질문을 대상으로 한 system_one 요청이며, 질문마다 하나의 분포를 반환합니다.
모든 쿼리에는 매번 새로 생성되는 uid가 할당되며, 이는 각 실행마다 변경되는 일회용 고유 값으로, 게시글과 평가 기준은 그대로 유지됩니다. 이는 LLM 프롬프트와 TypeSafe 상태의 추가 필드에 나타납니다. 이 구조는 무관한 필드에 대한 민감도와 동일한 요청에서 발생할 수 있는 변동을 분리할 수 없습니다.
각 도우미는 답변, 예상 비용, 왕복 지연 시간을 반환합니다。
def argmax_label(values: list, labels: list[str]) -> str | None:
    """The label with the most probability mass, or ``None`` if any value is missing or
    non-numeric -- a partially parsed distribution never yields a confident-looking pick."""
    numeric = [_numeric_value(value) for value in values]
    if any(value is None for value in numeric):
        return None
    return labels[int(np.argmax(numeric))]


def choice_decision_with_uncertainty(values: list, labels: list[str]) -> str | None:
    """Abstain below the action threshold; retain invalid results as parse failures."""
    label = argmax_label(values, labels)
    if label is None:
        return None
    probabilities = [float(value) for value in values]
    if any(value < 0 or value > 1 for value in probabilities):
        return None
    return label if max(probabilities) >= MIN_CHOICE_PROBABILITY else "uncertain"


def choice_decision_annotation(values: list, labels: list[str]) -> str:
    """Show the application decision and top probability in a heatmap cell."""
    decision = choice_decision_with_uncertainty(values, labels)
    if decision is None:
        return ""
    probability = max(float(value) for value in values)
    probability_text = f"{probability:.2f}".removeprefix("0")
    return f"{decision} {probability_text}"


def _numeric_value(value: object) -> float | None:
    """A finite numeric value, or ``None`` if the model emitted something unusable."""
    try:
        numeric = float(value)
    except (TypeError, ValueError):
        return None
    return numeric if np.isfinite(numeric) else None


def parse_distribution(raw: object, labels: list[str]) -> list[float]:
    """Map a model's already-parsed per-question reply to per-label probabilities, in label order
    (distribution-mode answers left un-normalized).

    A single-pick reply is a single label string -> all the mass on that exact label; a
    distribution-mode reply is a dict read label by label. Anything that doesn't match a known label
    or isn't a finite number is left NaN -- we report the gap rather than massaging the reply (e.g.
    stripping an echoed description) to make it fit."""
    if isinstance(raw, str):  # single-pick mode: a single chosen label
        if raw in labels:
            return [1.0 if label == raw else 0.0 for label in labels]
        return [float("nan")] * len(labels)
    if not isinstance(raw, dict):
        return [float("nan")] * len(labels)
    return [
        value if (value := _numeric_value(raw.get(label))) is not None else float("nan")
        for label in labels
    ]


def rubric_prompt(mode: str, sample_index: int, rubric_hash: str) -> str:
    """The post + all questions (with their label sets) in one prompt; ``mode`` picks the format.

    ``mode="dist"`` asks for a probability distribution over each question's labels; the single-pick
    mode (``mode="single"``) asks for a single label per question. The uid line combines
    ``rubric_hash`` (which rubric version) with ``sample_index`` and a random token, so every repeat
    is a distinct, independent draw and two different rubrics never share a nonce."""
    lines = []
    for key, (instructions, choices) in QUESTIONS.items():
        labels = "\n".join(f"     {label}: {desc}" for label, desc in choices.items())
        lines.append(f"- {key}: {instructions}\n   labels:\n{labels}")
    exclusivity = (
        "\n\nEach question's labels are mutually exclusive: exactly one applies. If a post could "
        "arguably fit more than one, pick the single most severe / most specific label per the "
        "label descriptions."
    )
    if mode == "single":
        answer_format = (
            "\n\nFor each question, pick exactly ONE label.\nRespond with ONLY a JSON object "
            "mapping each question's key to one of that question's bare labels (the label only, "
            "not its description), with one entry per question."
        )
    else:
        answer_format = (
            "\n\nFor each question, give a probability distribution over that question's labels "
            "(values 0.00-1.00 that sum to 1).\nRespond with ONLY a JSON object mapping each "
            "question's key to an object mapping that question's bare labels (the label only, "
            "not its description) to probabilities, with one entry per question."
        )
    return (
        f"uid: {rubric_hash}:{sample_index}:{token_hex(4)}\n\n"
        f"Document (a reported user post):\n{json.dumps(POST, indent=2)}\n\nQuestions:\n"
        + "\n".join(lines)
        + exclusivity
        + answer_format
    )


def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]


def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started


# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering is instant and reproduces the published numbers with no API spend. ``sample_index``
# seeds the uid buster and is part of the cache key, so each of the NUM_SAMPLES repeats is its own
# entry and its own independent draw, not one draw replayed. Delete ``json_cache.json`` to re-sample
# everything live.
json_cache = JsonCache(Path("json_cache.json"))


def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text and label set. Passed into the cached calls below so that editing the post or any question
    changes the cache key and forces a fresh sample, instead of silently serving a stale answer that
    was generated for the old wording."""
    payload = json.dumps([POST, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]


RUBRIC_HASH = _rubric_fingerprint()


@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return distributions, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{rubric_hash}:{sample_index}:{token_hex(4)}", "post": POST},
        questions=questions,
    )
    distributions = {}
    for key, (_instructions, choices) in QUESTIONS.items():
        probabilities = dict(response.answers[key].probabilities)
        distributions[key] = [
            probabilities.get(label, float("nan")) for label in choices
        ]
    return (
        distributions,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )


@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question label distributions keyed by question key, cost_usd,
    latency_s); NaNs if the reply doesn't parse.

    ``mode="dist"`` parses 8 label distributions; the single-pick mode (``mode="single"``) parses 8
    single labels and puts all the mass on each. ``rubric_hash`` goes into the prompt's uid nonce
    (and so the cache key), so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index, rubric_hash)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 sometimes adds one despite "ONLY a JSON
    # object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    if not isinstance(raw, dict):
        raw = {}
    distributions = {
        key: parse_distribution(raw.get(key), list(choices))
        for key, (_instructions, choices) in QUESTIONS.items()
    }
    return distributions, cost, latency
실험 조건
실험 그리드
| 모델 그룹 | 모델 | 분포 (t=0) | 분포 (기본값) | 단일 선택 (t=0) |
|---|---|---|---|---|
| 비추론 모델 | claude-haiku-4-5 |
✓ | ✓ | ✓ |
| 비추론 모델 | gpt-5.4-mini |
✓ | ✓ | ✓ |
| 추론 모델 | gpt-5.5 |
— | ✓ | — |
| 추론 모델 | claude-opus-4-8 |
— | ✓ | — |
| TypeSafe | jev-latest (typesafe_choice) |
— | ✓ | — |
✓는 15회 반복으로 테스트된 조건을,—는 테스트되지 않은 조합을 나타냅니다.- 기본 열은 온도 인수를 전송하지 않습니다: 비추론 모델은 API 기본값을 사용하며, 추론 모델과 TypeSafe는 온도 설정 없이 실행됩니다.
- 단일 선택 조건은 질문당 하나의 레이블을 반환합니다.
- 재현성을 위해 온도
0가 일반적으로 권장되므로, API 기본값과 비교됩니다.
우리는 NUM_SAMPLES = 조건당 15회 반복을 사용합니다. 각 반복은 고유한 캐시 키를 가지며 별도의 샘플링으로 간주되고, 캐시(json_cache.json)는 쿡북과 함께 제공되므로 다시 렌더링 시 이를 재사용하여 API 호출을 전혀 사용하지 않습니다. 캐시를 삭제하면 다시 실시간 샘플링을 수행할 수 있습니다.
CONDITIONS = []
for (
    model
) in BASE_MODELS:  # non-reasoning models: dist at t=0 / default, then a single-pick variant
    for temp_value, temp_label in ((0, "0"), (None, "default")):
        CONDITIONS.append(
            {
                "label": f"{model} t={temp_label}",
                "model": model,
                "temp": temp_value,
                "mode": "dist",
            }
        )
    CONDITIONS.append(
        {
            "label": f"{model} single-pick t=0",
            "model": model,
            "temp": 0,
            "mode": "single",
        }
    )
CONDITIONS += [  # reasoning models: one distribution condition each
    {
        "label": f"{model}-reasoning",
        "model": model,
        "temp": None,
        "mode": "dist",
    }
    for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]
TYPESAFE_LABEL = "typesafe_choice"
ALL_LABELS = [*LABELS, TYPESAFE_LABEL]

runs: dict[
    str, list
] = {}  # label -> NUM_SAMPLES samples of {question key: distribution}
stats: dict[str, list] = {}  # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
    futures = {
        condition["label"]: [
            pool.submit(
                ask_llm_rubric,
                condition["model"],
                condition["mode"],
                condition["temp"],
                sample_index,
                RUBRIC_HASH,
            )
            for sample_index in range(NUM_SAMPLES)
        ]
        for condition in CONDITIONS
    }
    for label, sample_futures in futures.items():
        results = [future.result() for future in sample_futures]
        runs[label] = [result[0] for result in results]
        stats[label] = [(result[1], result[2]) for result in results]

# TypeSafe samples are drawn sequentially, after the LLM pool has closed, so each call's latency is a
# clean round trip rather than one measured under the 16-way LLM thread contention.
typesafe_usage_results = [
    _call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
    for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
    result[4]["response_model"]
    for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
    (distributions, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
    for distributions, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats[TYPESAFE_LABEL] = [(result[1], result[2]) for result in typesafe_results]
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}비용 + 속도 (규칙별 쿼리 기준)
아래 비용은 Setup의 과거 가격 가정, TypeSafe의 speed_latest 비율을 포함하여 산정되었습니다. 이는 검증되지 않은 jev-latest 가격 또는 현재 청구 금액이 아닙니다.
한 행은 8문항 평가 기준 호출 하나를 의미합니다. time/call와 cost/call는 15회 호출의 평균을 내고, vs ts_choice 열은 TypeSafe 수치를 나눕니다. LLM은 16개 풀에서 실행됩니다.
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_choice"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_choice"]])
name_w = max(len(name) for name in ALL_LABELS) + 2  # fit the longest condition label
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
    f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
    f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
    f"{'ts_choice':>11}{'ts_choice':>11}"
)
for name in ALL_LABELS:
    costs, latencies = zip(*stats[name])
    cost = mean(costs)
    latency = mean(latencies)
    print(
        f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
        f"{'$' + format(cost, '.6f'):>13}"
        f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
        f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
    )
speed vs cost vs
condition calls time/call cost/call ts_choice ts_choice
claude-haiku-4-5 t=0 15 3853ms $0.003498 33.8x 76.1x
claude-haiku-4-5 t=default 15 3860ms $0.003494 33.8x 76.0x
claude-haiku-4-5 single-pick t=0 15 992ms $0.001527 8.7x 33.2x
gpt-5.4-mini t=0 15 2293ms $0.002299 20.1x 50.0x
gpt-5.4-mini t=default 15 1986ms $0.002164 17.4x 47.1x
gpt-5.4-mini single-pick t=0 15 826ms $0.000936 7.2x 20.3x
gpt-5.5-reasoning 15 12978ms $0.041255 113.7x 897.4x
claude-opus-4-8-reasoning 15 10376ms $0.028375 90.9x 617.2x
typesafe_choice 15 114ms $0.000046 1.0x 1.0x이번 실행 typesafe_choice에서 평균 왕복 지연 시간은 114ms입니다. 위의 동시성 설정 하에서 LLM 조건별 호출당 처리 시간은 826ms에서 13.0초까지 다양합니다.
플롯: 샘플별 결정의 히트맵
읽는 방법:
- 바깥쪽 행 그룹: 질문.
- 안쪽 행: 조건.
- 열: 하나의 전체 루빅 호출.
- 셀 텍스트: 애플리케이션 결정과 상위 레이블의 확률.
- 셀 색상: 해당 질문 내 레이블의 위치, 따라서 행 전체에 걸쳐 같은 색상은 항상 동일한 결정을 의미.
- 회색
uncertain: 상위 확률이0.60미만인 경우, 해당 사례는 인간 검토로 넘어감. - 대각선 줄무늬
n/a: 응답이 사용 가능한 레이블로 파싱되지 않음(파싱 실패). - 빈 행은 단순한 간격 역할.
단일 선택 조건은 반환된 라벨을 유지합니다. 불확실성 추정치를 제공하지 않습니다。
GAP = 1  # blank spacer row(s) between question blocks
HEAT_LABELS = ALL_LABELS
rows_per_block = len(HEAT_LABELS)  # rows per question block
pooled_runs = {
    **runs,
    TYPESAFE_LABEL: typesafe_runs,
}

row_index_values, row_text, row_labels, blocks = [], [], [], []
for question_index, (question_key, (question_text, choices)) in enumerate(
    QUESTIONS.items()
):
    labels = list(choices)
    if question_index:  # blank spacer rows (NaN -> rendered white) separate the blocks
        row_index_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
        row_text.extend([[""] * NUM_SAMPLES for _ in range(GAP)])
        row_labels.extend([""] * GAP)
    blocks.append((len(row_index_values), question_key, question_text))
    for label in HEAT_LABELS:
        values_by_sample = [
            pooled_runs[label][sample][question_key] for sample in range(NUM_SAMPLES)
        ]
        picks = [
            choice_decision_with_uncertainty(values, labels) for values in values_by_sample
        ]
        row_index_values.append(
            [
                10 if pick == "uncertain" else labels.index(pick) if pick in labels else np.nan
                for pick in picks
            ]
        )
        row_text.append(
            [choice_decision_annotation(values, labels) for values in values_by_sample]
        )
        row_labels.append(label)

heatmap_matrix = np.array(row_index_values, dtype=float)
# Reserve gray for abstentions while concrete-label colors remain local to each question.
cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
cmap.set_bad(
    "white"
)  # NaN cells (spacer rows AND unparseable replies) render white here...

fig, ax = plt.subplots(figsize=(15, 0.33 * len(row_index_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=10, aspect="auto")
for row in range(heatmap_matrix.shape[0]):
    is_spacer_row = row_labels[row] == ""  # blank separator between question blocks
    for col in range(heatmap_matrix.shape[1]):
        label_text = row_text[row][col]
        if label_text:
            ax.text(
                col,
                row,
                label_text,
                ha="center",
                va="center",
                fontsize=5.7,
                family="monospace",
                color="black",
            )
        elif (
            not is_spacer_row
        ):  # ...but an unparseable reply gets a hatched "n/a", not blank white
            ax.add_patch(
                plt.Rectangle(
                    (col - 0.5, row - 0.5),
                    1,
                    1,
                    facecolor="#e8e8e8",
                    edgecolor="#b0b0b0",
                    hatch="////",
                    linewidth=0,
                )
            )
            ax.text(
                col,
                row,
                "n/a",
                ha="center",
                va="center",
                fontsize=5,
                family="monospace",
                color="#b30000",
            )

ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
    ax.spines[edge].set_visible(False)

# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
    center = start + (rows_per_block - 1) / 2
    ax.text(
        -0.2,
        center - 0.7,
        question_key,
        transform=y_axis_transform,
        ha="right",
        va="center",
        fontsize=8,
        fontweight="bold",
    )
    ax.text(
        -0.2,
        center + 0.1,
        textwrap.fill(question_text, 34),
        transform=y_axis_transform,
        ha="right",
        va="top",
        fontsize=6,
        style="italic",
        color="gray",
    )

ax.set_title(
    f"Every sample's decision + top probability; gray = uncertain (< {MIN_CHOICE_PROBABILITY:.2f})\n"
    f"(rows = question x condition, {NUM_SAMPLES} columns)",
    pad=12,
)
fig.tight_layout()
display(fig)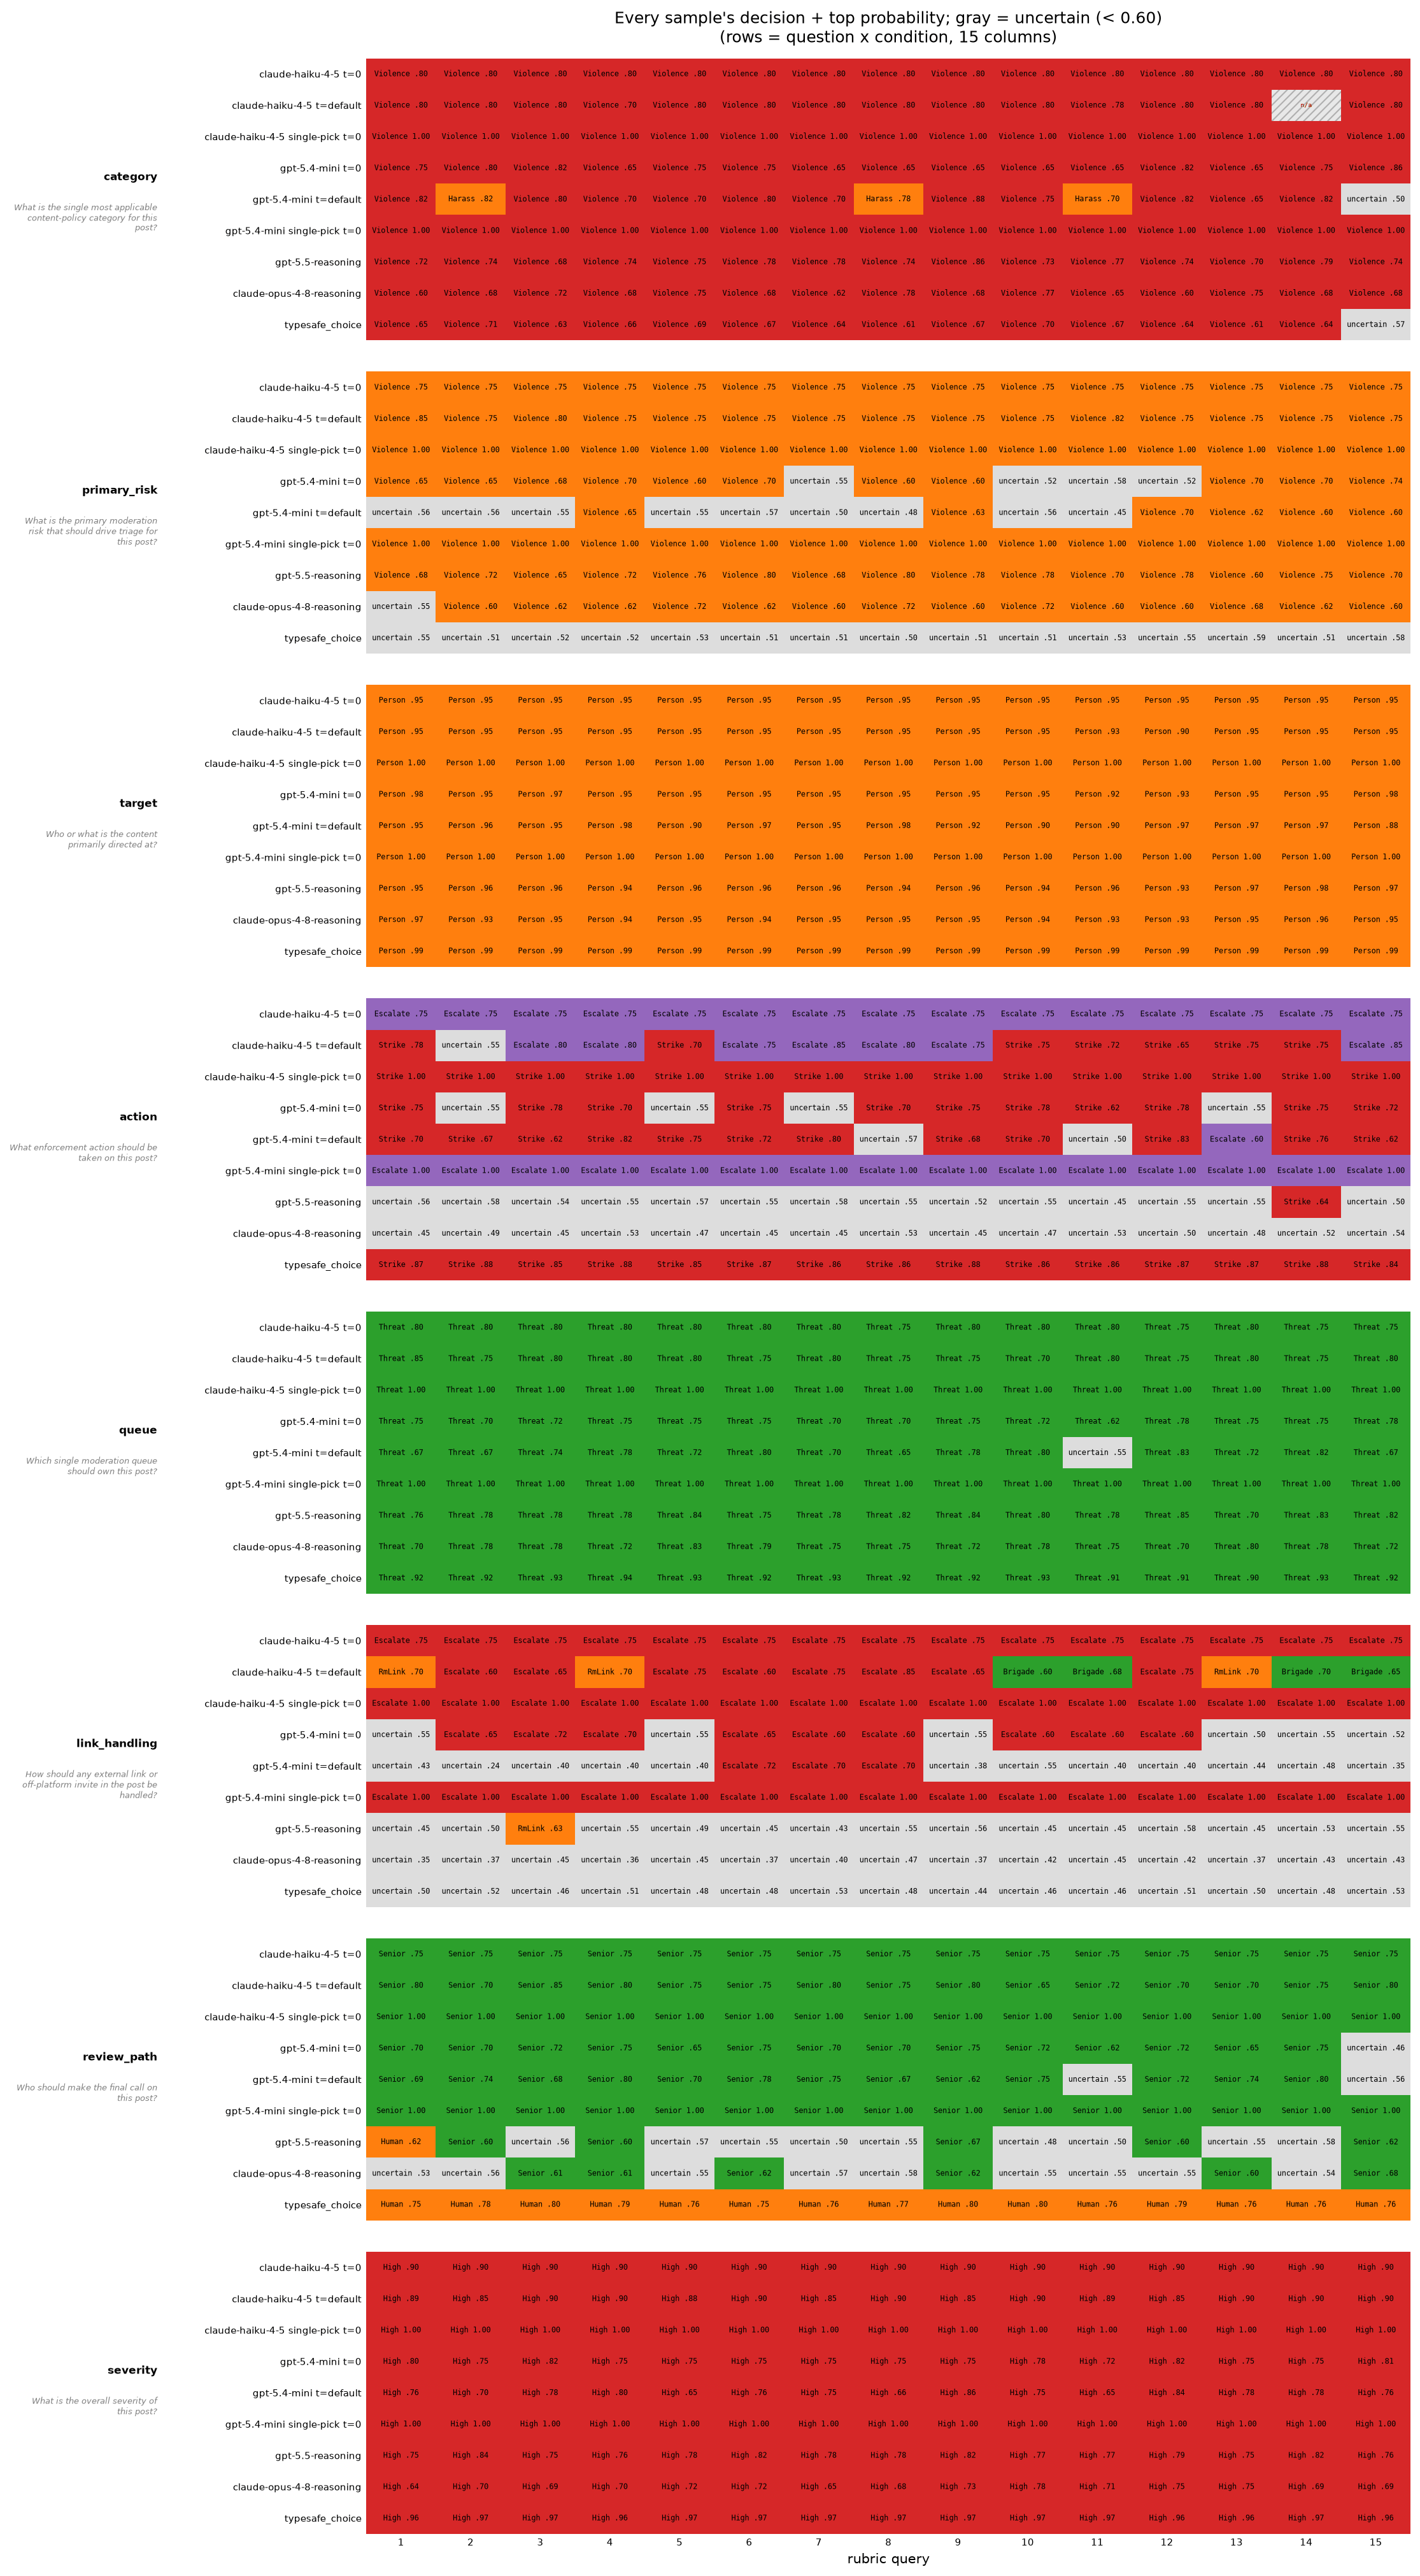
더 명확한 질문들은 일관성을 유지한다: target은 Person을, severity은 High를 전반적으로 나타낸다. 경계선상의 것들은 조건 간에 분포된다: category, primary_risk, action, review_path, 그리고 link_handling. 일부 조건은 자체 15회 반복 내에서 반전되기도 한다. 기권 이전, TypeSafe는 primary_risk(Harassment 11회, Violence 4회)과 link_handling(RmLink 8회, Brigade 7회)에서 최상위 레이블을 변경한다. 두 행은 이제 최상위 확률이 0.60 미만이기 때문에 uncertain를 전반적으로 보여준다.
확률 표준편차
이는 선택된 레이블뿐만 아니라 전체 확률 벡터를 검토합니다. 각 조건에 대해 모든 질문마다 15개 분포를 수집하고, 반복 실행 간 각 레이블 확률의 표준 편차(실행 간 변동 폭)를 계산한 후, 모든 레이블과 질문에서 해당 표준 편차를 평균냅니다. 또한 단일 최대 레이블 표준 편차를 보고하고, 구문 분석 실패는 별도로 집계합니다.
표는 확률 출력 LLM의 각 조건을 TypeSafe와 비교합니다. 단일 선택 행은 확률 분포가 아닌 하드 라벨을 출력하므로 제외됩니다.
def probability_std_stats(samples: list) -> tuple[float, float, float]:
    """Mean label std dev, max label std dev, parse-failure rate."""
    label_stds = []
    parse_failures = []
    for question_key in QUESTIONS:
        arr = np.array(
            [sample[question_key] for sample in samples],
            dtype=float,
        )
        parse_failures.extend(np.isnan(arr).any(axis=1).tolist())
        label_stds.extend(np.nanstd(arr, axis=0).tolist())
    return (
        float(np.nanmean(label_stds)),
        float(np.nanmax(label_stds)),
        float(np.mean(parse_failures)),
    )


PROBABILITY_OUTPUT_LABELS = [
    condition["label"] for condition in CONDITIONS if condition["mode"] == "dist"
] + [TYPESAFE_LABEL]
probability_std_by_label = {
    label: probability_std_stats(pooled_runs[label])
    for label in PROBABILITY_OUTPUT_LABELS
}
typesafe_mean_std = probability_std_by_label[TYPESAFE_LABEL][0]

print(
    f"{'condition':<{name_w}}{'mean prob std':>15}{'max prob std':>14}"
    f"{'parse fail':>12}{'x TypeSafe':>12}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    mean_std, max_std, parse_failure_rate = probability_std_by_label[label]
    relative_std = mean_std / typesafe_mean_std
    print(
        f"{label:<{name_w}}{mean_std:>15.4f}{max_std:>14.4f}"
        f"{parse_failure_rate:>11.0%}{relative_std:>12.2f}x"
    )
condition mean prob std max prob std parse fail x TypeSafe
claude-haiku-4-5 t=0 0.0012 0.0221 0% 0.12x
claude-haiku-4-5 t=default 0.0516 0.3150 1% 5.29x
gpt-5.4-mini t=0 0.0312 0.0905 0% 3.20x
gpt-5.4-mini t=default 0.0543 0.2303 0% 5.56x
gpt-5.5-reasoning 0.0305 0.1047 0% 3.12x
claude-opus-4-8-reasoning 0.0245 0.0693 0% 2.52x
typesafe_choice 0.0098 0.0515 0% 1.00x이번 실행에서 TypeSafe는 0.0098의 평균 확률 표준편차와 0.0515의 최대 단일 레이블 표준편차를 가집니다. 온도 0에서의 Haiku는 0.0012의 더 낮은 평균 표준편차를 가집니다. 다른 다섯 LLM 확률 조건은 0.0245에서 0.0543 사이이며, TypeSafe 평균의 약 2.5x에서 5.6x입니다. 두 레이블이 근접할 때 작은 변화라도 상위 레이블을 변경할 수 있습니다.
플롯: 불확실한 결과를 가진 결정 합의
최상위 확률이 0.60 미만일 경우 uncertain를 반환한다. 각 확률 출력 조건과 질문마다 uncertain를 포함한 가장 일반적인 애플리케이션 결정을 세고, 이를 15번의 추출 전체로 나눈다. 구문 분석 실패는 일치도 계산에 반영된다. 각 막대는 8개 질문 전체에 대한 점수의 평균을 나타내며, 일치도가 가장 높은 순으로 정렬된다.
불확실성 추정치를 제공하지 않기 때문에 단일 선택 LLM 조건은 제외됩니다.
# Compute policy decisions and agreement once for both this chart and the comparison table.
decisions_by_condition = {}
policy_agreement_by_condition = {}
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = [
        [
            choice_decision_with_uncertainty(sample[key], list(choices))
            for sample in pooled_runs[label]
        ]
        for key, (_instructions, choices) in QUESTIONS.items()
    ]
    decisions_by_condition[label] = decisions
    shares = [
        max(Counter(value for value in row if value is not None).values(), default=0)
        / NUM_SAMPLES
        for row in decisions
    ]
    policy_agreement_by_condition[label] = mean(shares)

# Sort by the measured agreement, keeping TypeSafe's color independent of its rank.
bar_labels = sorted(
    PROBABILITY_OUTPUT_LABELS, key=policy_agreement_by_condition.__getitem__, reverse=True
)
rates = [policy_agreement_by_condition[label] for label in bar_labels]

fig_bar, bar_ax = plt.subplots(figsize=(7, 0.45 * len(bar_labels) + 1))
positions = range(len(bar_labels))
bar_ax.barh(
    list(positions),
    rates,
    color=["#2b8cbe" if label == TYPESAFE_LABEL else "#fe9929" for label in bar_labels],
    alpha=0.85,
)
for label, position, rate in zip(bar_labels, positions, rates):
    marker = "*" if label == "claude-haiku-4-5 t=0" else ""
    bar_ax.text(
        rate + 0.01, position, f"{rate:.1%}{marker}", va="center", fontsize=8, color="gray"
    )
bar_ax.set_yticks(list(positions))
bar_ax.set_yticklabels(bar_labels, fontsize=8)
bar_ax.invert_yaxis()  # first condition on top
bar_ax.set_xlim(0, 1.08)
bar_ax.set_xticks(np.linspace(0, 1, 6))
bar_ax.set_xlabel("decision agreement across 15 re-runs (mean over 8 questions)")
for edge in ("top", "right", "left"):
    bar_ax.spines[edge].set_visible(False)
bar_ax.tick_params(length=0)
fig_bar.suptitle("Decision agreement including uncertain outcomes", y=1.0)
# Keep the caveat inside the exported chart so it travels with the 100% annotation.
fig_bar.text(
    0.01,
    0.01,
    "* Haiku t=0: 100% repeatability does not imply correctness.\n"
    "  This experiment does not measure accuracy.",
    fontsize=8,
)
fig_bar.tight_layout(rect=(0, 0.11, 1, 1))
display(fig_bar)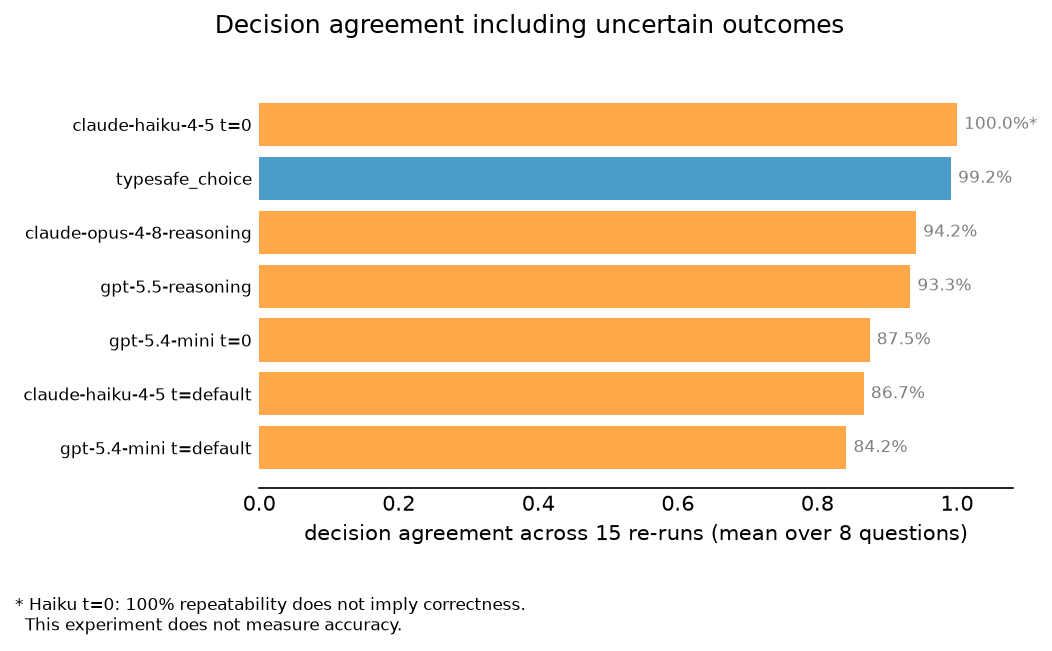
0.60 규칙 하에서, Haiku는 온도 0에서 100%의 점수를 기록했습니다. TypeSafe는 99.2%를 기록했으며, 다른 LLM 조건들은 84.2%에서 94.2% 사이에 위치했습니다. TypeSafe는 답변의 25.8%에서 uncertain을 반환했고 나머지 74.2%에서는 자동으로 조치를 취했습니다. 온도 0의 Haiku는 결코 거부하지 않았습니다. 이 비율들은 반복성만을 측정합니다. 아래 표는 이 차트의 정책 동의율과 함께 원시 동의율과 거부율을 나란히 제시합니다.
불확실한 확률이 불확실한 결정을 낳게 한다
작은 확률 변화가 두 개의 근접한 레이블을 바꿀 수 있습니다. 애플리케이션은 최상위 레이블에 반드시 반응해야 하는 것은 아닙니다: 상위 확률이 uncertain 미만일 경우 0.60를 반환하고, 해당 케이스를 사람에게 전달합니다. 정확히 0.60에서 최상위 레이블을 선택합니다. 이는 API의 별도 confidence 필드가 아닌 반환된 확률을 사용하며, 모델 호출을 추가하지 않습니다.
임계값은 예시용 애플리케이션 정책이며, 교정된 보증이나 이번 실행의 일치율을 최대화하도록 선택된 임계값이 아닙니다. 라벨이 붙은 예시와 잘못된 조치의 비용, 그리고 인간 검토를 사용하여 생산 환경의 임계값을 선택하세요.
우리는 모든 확률 출력 조건에 동일한 규칙을 적용합니다. 단일 선택 LLM 응답에는 확률 추정치가 없으며, 이들의 합성 원-핫 벡터는 불확실성을 측정할 수 없으므로 일치도 차트와 표에서 제외됩니다.
def agreement_rate(samples: list) -> float:
    """Mean over questions of the raw plurality label's share across all NUM_SAMPLES draws.

    Parse failures count against agreement because a failed route is not a repeated decision.
    """
    shares = []
    for question_key, (_instructions, choices) in QUESTIONS.items():
        labels = list(choices)
        picks = [
            argmax_label(samples[sample][question_key], labels)
            for sample in range(NUM_SAMPLES)
        ]
        picks = [pick for pick in picks if pick is not None]
        if not picks:
            shares.append(0.0)
            continue
        top = Counter(picks).most_common(1)[0][1]
        shares.append(top / NUM_SAMPLES)
    return mean(shares) if shares else float("nan")


# Keep failures separate from abstentions and count conflicting concrete actions per question.
print(
    f"{'condition':<{name_w}}{'raw agree':>12}{'policy agree':>14}"
    f"{'uncertain':>12}{'automatic':>12}{'conflicts':>11}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = decisions_by_condition[label]
    flat = [value for row in decisions for value in row]
    uncertain_rate = mean(value == "uncertain" for value in flat)
    automatic_rate = mean(value not in (None, "uncertain") for value in flat)
    conflicts = sum(
        len({value for value in row if value not in (None, "uncertain")}) > 1
        for row in decisions
    )
    print(
        f"{label:<{name_w}}{agreement_rate(pooled_runs[label]):>11.1%}"
        f"{policy_agreement_by_condition[label]:>13.1%}{uncertain_rate:>11.1%}"
        f"{automatic_rate:>11.1%}{conflicts:>11}"
    )
condition raw agree policy agree uncertain automatic conflicts
claude-haiku-4-5 t=0 100.0% 100.0% 0.0% 100.0% 0
claude-haiku-4-5 t=default 87.5% 86.7% 0.8% 98.3% 2
gpt-5.4-mini t=0 99.2% 87.5% 12.5% 87.5% 0
gpt-5.4-mini t=default 90.8% 84.2% 22.5% 77.5% 2
gpt-5.5-reasoning 90.0% 93.3% 30.8% 69.2% 1
claude-opus-4-8-reasoning 92.5% 94.2% 33.3% 66.7% 0
typesafe_choice 90.8% 99.2% 25.8% 74.2% 0policy agree는 결정을 uncertain로 간주하며, 구문 분석 실패는 합의에 대해 카운트됩니다.
automatic는 레이블을 선택하는 모든 답변의 비율입니다. conflicts는 기권을 무시하고 반복 동안 여러 개의 구체적인 레이블이 있는 질문의 수를 카운트합니다. 이러한 지표는 행동이 올바른지 여부가 아니라, 반복성과 애플리케이션이 행동하는 빈도를 설명합니다.
TypeSafe의 합의율은 90.8%에서 99.2%로 상승했다. 답변 중 25.8%는 불확실했고 74.2%는 자동이었다. primary_risk과 link_handling은 모든 반복에서 불확실하게 돌아왔으며, category은 폭력과 uncertain 사이를 오가며 일부 반복에서는 행동 임계값을 넘었고 다른 반복에서는 넘지 않았다. 어떤 질문도 두 가지 다른 구체적인 TypeSafe 라벨을 생성하지 않았다. 이 결과는 정확성이나 우월성을 보여주지 않는다: Haiku는 온도 0에서 100%의 합의율을 보였으며, 거부 답변은 없었다.
# Show every TypeSafe decision while retaining the top probability behind it.
policy_decisions = decisions_by_condition[TYPESAFE_LABEL]
policy_values = []
for row, (_key, (_instructions, choices)) in zip(policy_decisions, QUESTIONS.items()):
    labels = list(choices)
    policy_values.append([
        10 if value == "uncertain" else labels.index(value) if value is not None else np.nan
        for value in row
    ])
policy_cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
policy_cmap.set_bad("white")
fig_policy, ax_policy = plt.subplots(figsize=(13, 4))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=10, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
    for sample_index in range(NUM_SAMPLES):
        decision = policy_decisions[row_index][sample_index]
        probability = max(typesafe_runs[sample_index][key])
        ax_policy.text(sample_index, row_index, f"{decision or 'n/a'}\n{probability:.2f}",
                       ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
    "TypeSafe application decisions: gray means uncertain "
    f"(top probability < {MIN_CHOICE_PROBABILITY:.2f})"
)
fig_policy.tight_layout()
display(fig_policy)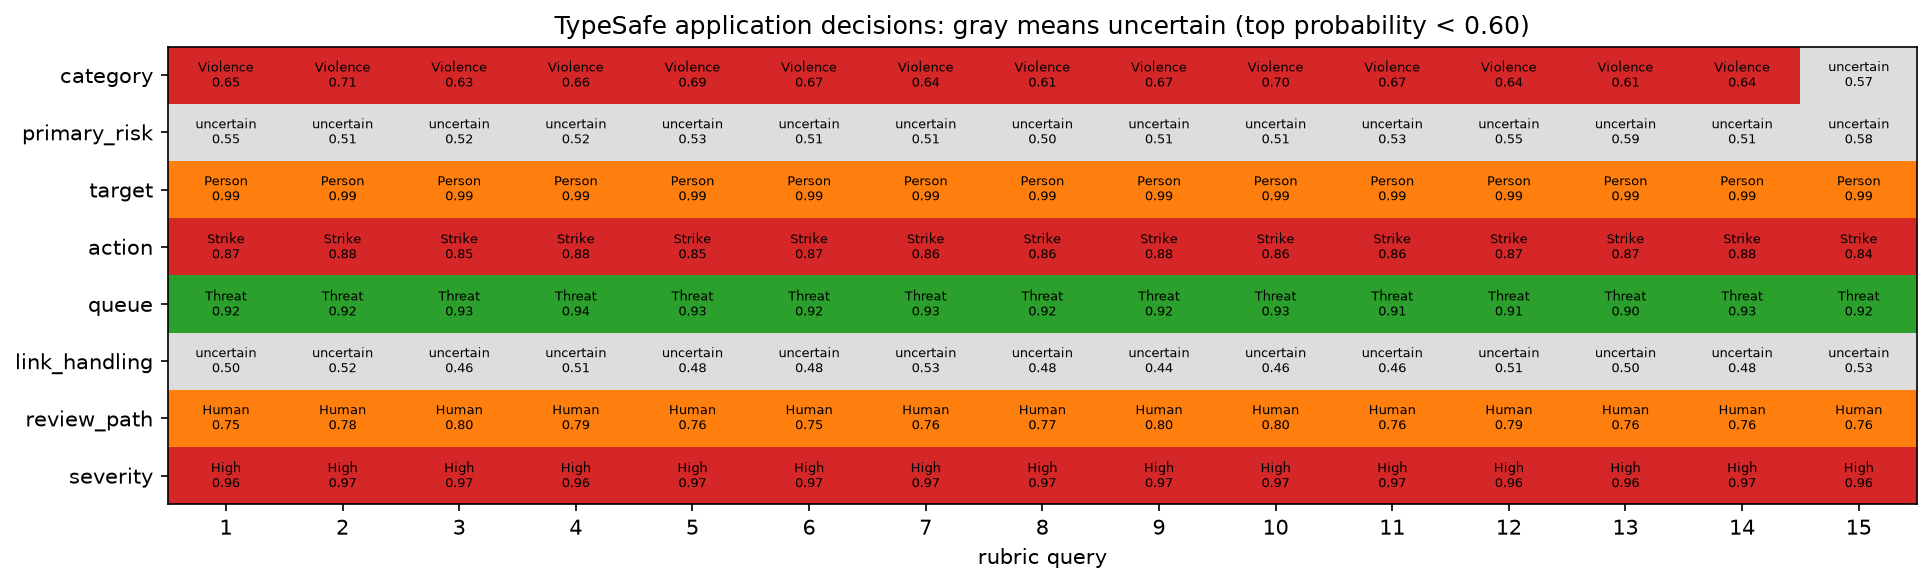
이 정책은 모델을 결정론적으로 만들지 않습니다. 거부하는 것은 동일한 인간 검토 결과를 가진 경쟁 레이블을 대체할 수 있지만, 0.60 근처의 확률은 여전히 구체적인 레이블과 uncertain 사이에서 이동할 수 있습니다. 확률 통계와 테이블의 raw agree 열은 여전히 원래 모델 출력을 보고합니다.
TypeSafe 플레이그라운드에서 열기
아래 링크는 플레이그라운드에서 동일한 게시글과 평가 기준을 엽니다: 하나의 게시글, 동일한 8
Choices, 그리고 TypeSafe jev-latest.
playground_link = make_playground_link(
    {"post": POST},
    {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this post + rubric in the TypeSafe playground]({playground_link})"
    )
)