 JevCode
Autoconsistência: escolhas
Adicione um resultado incerto às decisões de moderação e compare a concordância de rótulos com a proporção de ações automáticas.
Traduzido automaticamente do en, sem revisão. Apenas como referência rápida.

Este livro de receitas pega uma postagem de usuário limítrofe, aplica um rubrica de moderação sobre ela 15 vezes,
e verifica se cada resposta permanece estável através das repetições. Cada verificação é um
Choice, então cada resposta é um rótulo de um conjunto fixo. Em um pipeline de moderação
esse rótulo é a decisão de roteamento: remover ou deixar no ar, escalar ou resolver automaticamente, enviar para
a fila de ameaças, spam ou geral. Quando o rótulo oscila de uma execução para a próxima, a
mesma postagem é roteada para lugares diferentes sem boa razão.
A rubrica é de 8 Choice perguntas, e cada execução é uma chamada que responde a todas as 8. Fazemos
15
repetições por condição, onde uma condição é um modelo mais uma configuração, e plotamos cada
rótulo que retornou.
As condições:
- LLMs não raciocinadores
claude-haiku-4-5egpt-5.4-mini, com temperatura0e a configuração padrão da API. - LLMs com raciocínio
gpt-5.5eclaude-opus-4-8, que não possuem controle de temperatura. - TypeSafe: uma única chamada
system_onesobre as 8 perguntasChoice, com um campouidnovo (um valor único descartável) em cada chamada, correspondendo à configuração do cookbook noul.
O que observar: rótulos selecionados podem inverter-se dentro de uma única condição, incluindo TypeSafe, e as condições discordam umas das outras.
Nesta execução, as configurações de distribuição do LLM repetem seus rótulos de pluralidade de 87,5% a 100% das vezes, em comparação com os 90,8% do TypeSafe. O TypeSafe apresenta menor variação média de probabilidade do que cinco das seis condições de distribuição do LLM; o Haiku a temperatura 0 varia menos. Probabilidades próximas ainda permitem alterações de roteamento: o TypeSafe inverte em 2 das 8 perguntas.
Para decisões de aplicação, também exigimos uma probabilidade máxima de pelo menos 0.60; caso contrário, o resultado é uncertain e vai para revisão humana. O acordo da TypeSafe então sobe para 99,2%, com rótulos automáticos em 74,2% das respostas. Mostramos as saídas brutas e aplicamos o mesmo limiar às condições de probabilidade do LLM, mantendo as abstenções e as alterações visíveis.
Configuração
pip install anthropic openai matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/então defina TYPESAFE_API_KEY, ANTHROPIC_API_KEY e OPENAI_API_KEY.
Esta execução usa jev-latest na API de produção, amostrada em 2026-09-11.
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean

from time import perf_counter

import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Choice, TypeSafeClient

matplotlib.use("Agg")  # headless render

BASE_MODELS = [
    "claude-haiku-4-5",
    "gpt-5.4-mini",
]  # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
    "gpt-5.5",
    "claude-opus-4-8",
]  # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest"  # the TypeSafe model
NUM_SAMPLES = 15  # repeated post+rubric calls per condition
MIN_CHOICE_PROBABILITY = 0.60  # illustrative automatic-action threshold

LLM_PRICES = {  # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
    "claude-haiku-4-5": (1.00, 5.00),
    "gpt-5.4-mini": (0.75, 4.50),
    "gpt-5.5": (5.00, 30.00),
    "claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00)  # Historical TypeSafe rate, as of 2026-08

anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
    api_key=os.environ["TYPESAFE_API_KEY"],
    base_url="https://api.typesafe.ai",
    timeout=30.0,
)
O estado: uma postagem de usuário limítrofe, em JSON
A publicação abaixo está na linha tênue. A linguagem é acalorada e insultuosa, dirigida parcialmente a uma pessoa e parcialmente ao argumento e à comunidade. Ela contém um convite fora da plataforma (um link que direciona pessoas para outro site), uma advertência prévia na conta e quatro relatos de usuários, e a redação com tom de ameaça nunca é claramente formulada.
Não há uma única resposta óbvia aqui, e esse é o ponto: pequenas diferenças de redação não devem mover aleatoriamente a mesma publicação entre os caminhos de aplicação.
Os LLMs recebem json.dumps(POST) no prompt. O TypeSafe recebe o dicionário Python diretamente.
POST = {
    "post_id": "P-88213",
    "author": {
        "user_id": "u/4471",
        "account_age_days": 38,
        "prior_strikes": 1,
        "followers": 210,
    },
    "context": {
        "surface": "public reply",
        "in_reply_to": "another user defending a game patch",
        "community": "r/gamedebates",
    },
    "content": {
        "text": (
            "Are you seriously this dense? Anyone who defends that patch is a complete clown and "
            "should be embarrassed to even post here. People like you are what's ruining this "
            "community and honestly you need to be dealt with. Come say it to my face, invite's "
            "right here. Keep it up and I'll end your whole channel."
        ),
        "has_link": True,
        "link_domain": "discord.gg",
        "language": "en",
    },
    "reports": {"user_reports": 4, "report_reasons": ["harassment", "spam", "threat"]},
}
A rubrica: 8 Choice perguntas
Cada pergunta tem um key, uma linha de instruções e um conjunto de rótulos fixo. Os rótulos dentro de uma pergunta são mutuamente exclusivos (exatamente um se aplica), e cada um carrega uma descrição curta. O TypeSafe retorna um choice escolhido, além de uma distribuição probabilities sobre os rótulos. Os LLMs são solicitados a usar os mesmos conjuntos de rótulos, o que mantém cada linha comparável.
QUESTIONS = {
    "category": (
        "What is the single most applicable content-policy category for this post?",
        {
            "None": "No policy violation of any kind.",
            "Harass": "Insults or demeans a person, with no threat of harm and no protected-class attack.",
            "Hate": "Attacks a person or group over a protected characteristic (race, religion, gender, ...).",
            "Violence": "Makes a credible threat of harm or incites violence against someone.",
            "Spam": "Unsolicited promotion or link spam, with no personal attack.",
            "Sexual": "Sexual or adult content.",
        },
    ),
    "primary_risk": (
        "What is the primary moderation risk that should drive triage for this post?",
        {
            "Harassment": "Personal attack or targeted abuse is the main risk.",
            "Violence": "A threat of harm or intimidation is the main risk.",
            "LinkAbuse": "External-link or off-platform coordination risk is the main risk.",
            "AccountHistory": "Prior account history or repeat behavior is the main risk.",
            "LowRisk": "No meaningful moderation risk is present.",
        },
    ),
    "target": (
        "Who or what is the content primarily directed at?",
        {
            "None": "Not directed at anyone in particular.",
            "Person": "Directed at one specific individual.",
            "Group": "Directed at a protected group or class.",
            "Platform": "Directed at the community or platform itself, not a person.",
        },
    ),
    "action": (
        "What enforcement action should be taken on this post?",
        {
            "Allow": "Leave the post up with no action.",
            "Warn": "Leave the post up but attach a warning label.",
            "Remove": "Remove the post, but do not penalize the account.",
            "Strike": "Remove the post and add a strike to the account.",
            "Escalate": "Take no automated action; hold for a human decision.",
        },
    ),
    "queue": (
        "Which single moderation queue should own this post?",
        {
            "Auto": "Auto-resolve; no human queue needed.",
            "General": "General moderation queue.",
            "Threat": "Threat / violence response queue.",
            "Spam": "Spam and platform-abuse queue.",
            "TSLead": "Trust-and-safety lead / senior queue.",
        },
    ),
    "link_handling": (
        "How should any external link or off-platform invite in the post be handled?",
        {
            "Allow": "Leave the link in place.",
            "RmLink": "Strip or disable the link but keep the post.",
            "Brigade": "Treat the link as coordinated brigading and action it as abuse.",
            "Escalate": "Send the link to a specialist to assess before acting.",
        },
    ),
    "review_path": (
        "Who should make the final call on this post?",
        {
            "Auto": "Automated action; no human review.",
            "Human": "A frontline human moderator makes the call.",
            "Senior": "A senior or specialist reviewer is required.",
            "Legal": "Route to legal or law-enforcement escalation.",
        },
    ),
    "severity": (
        "What is the overall severity of this post?",
        {
            "None": "No violation.",
            "Low": "Rude or dismissive, but essentially harmless.",
            "Medium": "Personal harassment with no clearly credible threat.",
            "High": "Harassment together with a threat that could be read as credible.",
        },
    ),
}
Como pedimos
Cada chamada de LLM é um prompt contendo json.dumps(POST), todas as 8 perguntas e todos os rótulos permitidos. Existem dois formatos de resposta. No modo de distribuição, o modelo retorna um objeto JSON por pergunta com uma probabilidade para cada rótulo. No modo de escolha única, ele retorna um único rótulo por pergunta, e nossa análise concentra toda a massa de probabilidade nesse rótulo.
A chamada TypeSafe é uma system_one solicitação sobre a mesma postagem e as mesmas 8
Choice perguntas, retornando uma distribuição por pergunta.
Cada consulta também recebe um uid novo, um valor exclusivo descartável que muda a cada execução enquanto
mantém a postagem e a rubrica inalteradas. Ele aparece no prompt do LLM e como um campo extra
no estado TypeSafe. Esta configuração não consegue separar a sensibilidade ao campo irrelevante
da variação que ocorreria em solicitações idênticas.
Cada assistente retorna a resposta, um custo estimado e a latência de ida e volta.
def argmax_label(values: list, labels: list[str]) -> str | None:
    """The label with the most probability mass, or ``None`` if any value is missing or
    non-numeric -- a partially parsed distribution never yields a confident-looking pick."""
    numeric = [_numeric_value(value) for value in values]
    if any(value is None for value in numeric):
        return None
    return labels[int(np.argmax(numeric))]


def choice_decision_with_uncertainty(values: list, labels: list[str]) -> str | None:
    """Abstain below the action threshold; retain invalid results as parse failures."""
    label = argmax_label(values, labels)
    if label is None:
        return None
    probabilities = [float(value) for value in values]
    if any(value < 0 or value > 1 for value in probabilities):
        return None
    return label if max(probabilities) >= MIN_CHOICE_PROBABILITY else "uncertain"


def choice_decision_annotation(values: list, labels: list[str]) -> str:
    """Show the application decision and top probability in a heatmap cell."""
    decision = choice_decision_with_uncertainty(values, labels)
    if decision is None:
        return ""
    probability = max(float(value) for value in values)
    probability_text = f"{probability:.2f}".removeprefix("0")
    return f"{decision} {probability_text}"


def _numeric_value(value: object) -> float | None:
    """A finite numeric value, or ``None`` if the model emitted something unusable."""
    try:
        numeric = float(value)
    except (TypeError, ValueError):
        return None
    return numeric if np.isfinite(numeric) else None


def parse_distribution(raw: object, labels: list[str]) -> list[float]:
    """Map a model's already-parsed per-question reply to per-label probabilities, in label order
    (distribution-mode answers left un-normalized).

    A single-pick reply is a single label string -> all the mass on that exact label; a
    distribution-mode reply is a dict read label by label. Anything that doesn't match a known label
    or isn't a finite number is left NaN -- we report the gap rather than massaging the reply (e.g.
    stripping an echoed description) to make it fit."""
    if isinstance(raw, str):  # single-pick mode: a single chosen label
        if raw in labels:
            return [1.0 if label == raw else 0.0 for label in labels]
        return [float("nan")] * len(labels)
    if not isinstance(raw, dict):
        return [float("nan")] * len(labels)
    return [
        value if (value := _numeric_value(raw.get(label))) is not None else float("nan")
        for label in labels
    ]


def rubric_prompt(mode: str, sample_index: int, rubric_hash: str) -> str:
    """The post + all questions (with their label sets) in one prompt; ``mode`` picks the format.

    ``mode="dist"`` asks for a probability distribution over each question's labels; the single-pick
    mode (``mode="single"``) asks for a single label per question. The uid line combines
    ``rubric_hash`` (which rubric version) with ``sample_index`` and a random token, so every repeat
    is a distinct, independent draw and two different rubrics never share a nonce."""
    lines = []
    for key, (instructions, choices) in QUESTIONS.items():
        labels = "\n".join(f"     {label}: {desc}" for label, desc in choices.items())
        lines.append(f"- {key}: {instructions}\n   labels:\n{labels}")
    exclusivity = (
        "\n\nEach question's labels are mutually exclusive: exactly one applies. If a post could "
        "arguably fit more than one, pick the single most severe / most specific label per the "
        "label descriptions."
    )
    if mode == "single":
        answer_format = (
            "\n\nFor each question, pick exactly ONE label.\nRespond with ONLY a JSON object "
            "mapping each question's key to one of that question's bare labels (the label only, "
            "not its description), with one entry per question."
        )
    else:
        answer_format = (
            "\n\nFor each question, give a probability distribution over that question's labels "
            "(values 0.00-1.00 that sum to 1).\nRespond with ONLY a JSON object mapping each "
            "question's key to an object mapping that question's bare labels (the label only, "
            "not its description) to probabilities, with one entry per question."
        )
    return (
        f"uid: {rubric_hash}:{sample_index}:{token_hex(4)}\n\n"
        f"Document (a reported user post):\n{json.dumps(POST, indent=2)}\n\nQuestions:\n"
        + "\n".join(lines)
        + exclusivity
        + answer_format
    )


def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]


def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started


# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering is instant and reproduces the published numbers with no API spend. ``sample_index``
# seeds the uid buster and is part of the cache key, so each of the NUM_SAMPLES repeats is its own
# entry and its own independent draw, not one draw replayed. Delete ``json_cache.json`` to re-sample
# everything live.
json_cache = JsonCache(Path("json_cache.json"))


def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text and label set. Passed into the cached calls below so that editing the post or any question
    changes the cache key and forces a fresh sample, instead of silently serving a stale answer that
    was generated for the old wording."""
    payload = json.dumps([POST, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]


RUBRIC_HASH = _rubric_fingerprint()


@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return distributions, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{rubric_hash}:{sample_index}:{token_hex(4)}", "post": POST},
        questions=questions,
    )
    distributions = {}
    for key, (_instructions, choices) in QUESTIONS.items():
        probabilities = dict(response.answers[key].probabilities)
        distributions[key] = [
            probabilities.get(label, float("nan")) for label in choices
        ]
    return (
        distributions,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )


@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question label distributions keyed by question key, cost_usd,
    latency_s); NaNs if the reply doesn't parse.

    ``mode="dist"`` parses 8 label distributions; the single-pick mode (``mode="single"``) parses 8
    single labels and puts all the mass on each. ``rubric_hash`` goes into the prompt's uid nonce
    (and so the cache key), so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index, rubric_hash)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 sometimes adds one despite "ONLY a JSON
    # object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    if not isinstance(raw, dict):
        raw = {}
    distributions = {
        key: parse_distribution(raw.get(key), list(choices))
        for key, (_instructions, choices) in QUESTIONS.items()
    }
    return distributions, cost, latency
Condições Experimentais
Grade de Experimentos
| Grupo de modelos | Modelo | Distribuição (t=0) | Distribuição (padrão) | Escolha única (t=0) |
|---|---|---|---|---|
| Modelos sem raciocínio | claude-haiku-4-5 |
✓ | ✓ | ✓ |
| Modelos sem raciocínio | gpt-5.4-mini |
✓ | ✓ | ✓ |
| Modelos com raciocínio | gpt-5.5 |
— | ✓ | — |
| Modelos com raciocínio | claude-opus-4-8 |
— | ✓ | — |
| TypeSafe | jev-latest (typesafe_choice) |
— | ✓ | — |
- Um
✓marca uma condição testada com 15 repetições; um—marca uma combinação que não é testada. - A coluna padrão não envia argumento de temperatura: modelos não raciocinantes usam o padrão da API e modelos de raciocínio e TypeSafe executam sem configuração de temperatura.
- Condições de escolha única retornam um rótulo por pergunta.
- Temperatura
0é comumente sugerida para repetibilidade, portanto é comparada com o padrão da API.
Desenhamos NUM_SAMPLES = 15 repetições por condição. Cada repetição tem sua própria chave de cache e conta como um desenho distinto, e o cache (json_cache.json) acompanha o livro de receitas, portanto, o novo renderizado o reutiliza e não gasta chamadas de API. Exclua o cache para amostrar ao vivo novamente.
CONDITIONS = []
for (
    model
) in BASE_MODELS:  # non-reasoning models: dist at t=0 / default, then a single-pick variant
    for temp_value, temp_label in ((0, "0"), (None, "default")):
        CONDITIONS.append(
            {
                "label": f"{model} t={temp_label}",
                "model": model,
                "temp": temp_value,
                "mode": "dist",
            }
        )
    CONDITIONS.append(
        {
            "label": f"{model} single-pick t=0",
            "model": model,
            "temp": 0,
            "mode": "single",
        }
    )
CONDITIONS += [  # reasoning models: one distribution condition each
    {
        "label": f"{model}-reasoning",
        "model": model,
        "temp": None,
        "mode": "dist",
    }
    for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]
TYPESAFE_LABEL = "typesafe_choice"
ALL_LABELS = [*LABELS, TYPESAFE_LABEL]

runs: dict[
    str, list
] = {}  # label -> NUM_SAMPLES samples of {question key: distribution}
stats: dict[str, list] = {}  # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
    futures = {
        condition["label"]: [
            pool.submit(
                ask_llm_rubric,
                condition["model"],
                condition["mode"],
                condition["temp"],
                sample_index,
                RUBRIC_HASH,
            )
            for sample_index in range(NUM_SAMPLES)
        ]
        for condition in CONDITIONS
    }
    for label, sample_futures in futures.items():
        results = [future.result() for future in sample_futures]
        runs[label] = [result[0] for result in results]
        stats[label] = [(result[1], result[2]) for result in results]

# TypeSafe samples are drawn sequentially, after the LLM pool has closed, so each call's latency is a
# clean round trip rather than one measured under the 16-way LLM thread contention.
typesafe_usage_results = [
    _call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
    for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
    result[4]["response_model"]
    for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
    (distributions, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
    for distributions, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats[TYPESAFE_LABEL] = [(result[1], result[2]) for result in typesafe_results]
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}Custo + velocidade (por consulta de rubrica)
Os custos abaixo utilizam as premissas de preço históricas em Setup, incluindo a taxa speed_latest para TypeSafe. Eles não são preços jev-latest verificados nem valores atuais de faturamento.
Uma linha corresponde a uma chamada completa de rubrica com 8 perguntas. time/call e cost/call fazem a média das 15 chamadas, e as colunas vs ts_choice dividem pelos valores do TypeSafe. Os LLMs são executados em um pool de 16 vias.
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_choice"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_choice"]])
name_w = max(len(name) for name in ALL_LABELS) + 2  # fit the longest condition label
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
    f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
    f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
    f"{'ts_choice':>11}{'ts_choice':>11}"
)
for name in ALL_LABELS:
    costs, latencies = zip(*stats[name])
    cost = mean(costs)
    latency = mean(latencies)
    print(
        f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
        f"{'$' + format(cost, '.6f'):>13}"
        f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
        f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
    )
speed vs cost vs
condition calls time/call cost/call ts_choice ts_choice
claude-haiku-4-5 t=0 15 3853ms $0.003498 33.8x 76.1x
claude-haiku-4-5 t=default 15 3860ms $0.003494 33.8x 76.0x
claude-haiku-4-5 single-pick t=0 15 992ms $0.001527 8.7x 33.2x
gpt-5.4-mini t=0 15 2293ms $0.002299 20.1x 50.0x
gpt-5.4-mini t=default 15 1986ms $0.002164 17.4x 47.1x
gpt-5.4-mini single-pick t=0 15 826ms $0.000936 7.2x 20.3x
gpt-5.5-reasoning 15 12978ms $0.041255 113.7x 897.4x
claude-opus-4-8-reasoning 15 10376ms $0.028375 90.9x 617.2x
typesafe_choice 15 114ms $0.000046 1.0x 1.0xNesta execução typesafe_choice possui uma latência média de ida e volta de 114ms. As condições do LLM variam de 826ms a 13,0 segundos por chamada sob as configurações de concorrência acima.
Enredo: a decisão de cada amostra como um mapa de calor
Como ler:
- Grupo de linhas externo: a pergunta.
- Linha interna: a condição.
- Coluna: uma chamada completa da rubrica.
- Texto da célula: a decisão da aplicação mais a probabilidade no rótulo superior.
- Cor da célula: a posição do rótulo dentro dessa pergunta, de modo que a mesma cor ao longo de toda uma linha significa a mesma decisão sempre.
- Cinza
uncertain: a probabilidade superior está abaixo de0.60, então o caso vai para revisão humana. - Tracejado
n/a: a resposta não foi analisada em rótulos utilizáveis (falha de análise). - Linhas em branco são apenas espaçadores.
As condições de escolha única mantêm seus rótulos retornados: elas não fornecem estimativa de incerteza.
GAP = 1  # blank spacer row(s) between question blocks
HEAT_LABELS = ALL_LABELS
rows_per_block = len(HEAT_LABELS)  # rows per question block
pooled_runs = {
    **runs,
    TYPESAFE_LABEL: typesafe_runs,
}

row_index_values, row_text, row_labels, blocks = [], [], [], []
for question_index, (question_key, (question_text, choices)) in enumerate(
    QUESTIONS.items()
):
    labels = list(choices)
    if question_index:  # blank spacer rows (NaN -> rendered white) separate the blocks
        row_index_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
        row_text.extend([[""] * NUM_SAMPLES for _ in range(GAP)])
        row_labels.extend([""] * GAP)
    blocks.append((len(row_index_values), question_key, question_text))
    for label in HEAT_LABELS:
        values_by_sample = [
            pooled_runs[label][sample][question_key] for sample in range(NUM_SAMPLES)
        ]
        picks = [
            choice_decision_with_uncertainty(values, labels) for values in values_by_sample
        ]
        row_index_values.append(
            [
                10 if pick == "uncertain" else labels.index(pick) if pick in labels else np.nan
                for pick in picks
            ]
        )
        row_text.append(
            [choice_decision_annotation(values, labels) for values in values_by_sample]
        )
        row_labels.append(label)

heatmap_matrix = np.array(row_index_values, dtype=float)
# Reserve gray for abstentions while concrete-label colors remain local to each question.
cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
cmap.set_bad(
    "white"
)  # NaN cells (spacer rows AND unparseable replies) render white here...

fig, ax = plt.subplots(figsize=(15, 0.33 * len(row_index_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=10, aspect="auto")
for row in range(heatmap_matrix.shape[0]):
    is_spacer_row = row_labels[row] == ""  # blank separator between question blocks
    for col in range(heatmap_matrix.shape[1]):
        label_text = row_text[row][col]
        if label_text:
            ax.text(
                col,
                row,
                label_text,
                ha="center",
                va="center",
                fontsize=5.7,
                family="monospace",
                color="black",
            )
        elif (
            not is_spacer_row
        ):  # ...but an unparseable reply gets a hatched "n/a", not blank white
            ax.add_patch(
                plt.Rectangle(
                    (col - 0.5, row - 0.5),
                    1,
                    1,
                    facecolor="#e8e8e8",
                    edgecolor="#b0b0b0",
                    hatch="////",
                    linewidth=0,
                )
            )
            ax.text(
                col,
                row,
                "n/a",
                ha="center",
                va="center",
                fontsize=5,
                family="monospace",
                color="#b30000",
            )

ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
    ax.spines[edge].set_visible(False)

# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
    center = start + (rows_per_block - 1) / 2
    ax.text(
        -0.2,
        center - 0.7,
        question_key,
        transform=y_axis_transform,
        ha="right",
        va="center",
        fontsize=8,
        fontweight="bold",
    )
    ax.text(
        -0.2,
        center + 0.1,
        textwrap.fill(question_text, 34),
        transform=y_axis_transform,
        ha="right",
        va="top",
        fontsize=6,
        style="italic",
        color="gray",
    )

ax.set_title(
    f"Every sample's decision + top probability; gray = uncertain (< {MIN_CHOICE_PROBABILITY:.2f})\n"
    f"(rows = question x condition, {NUM_SAMPLES} columns)",
    pad=12,
)
fig.tight_layout()
display(fig)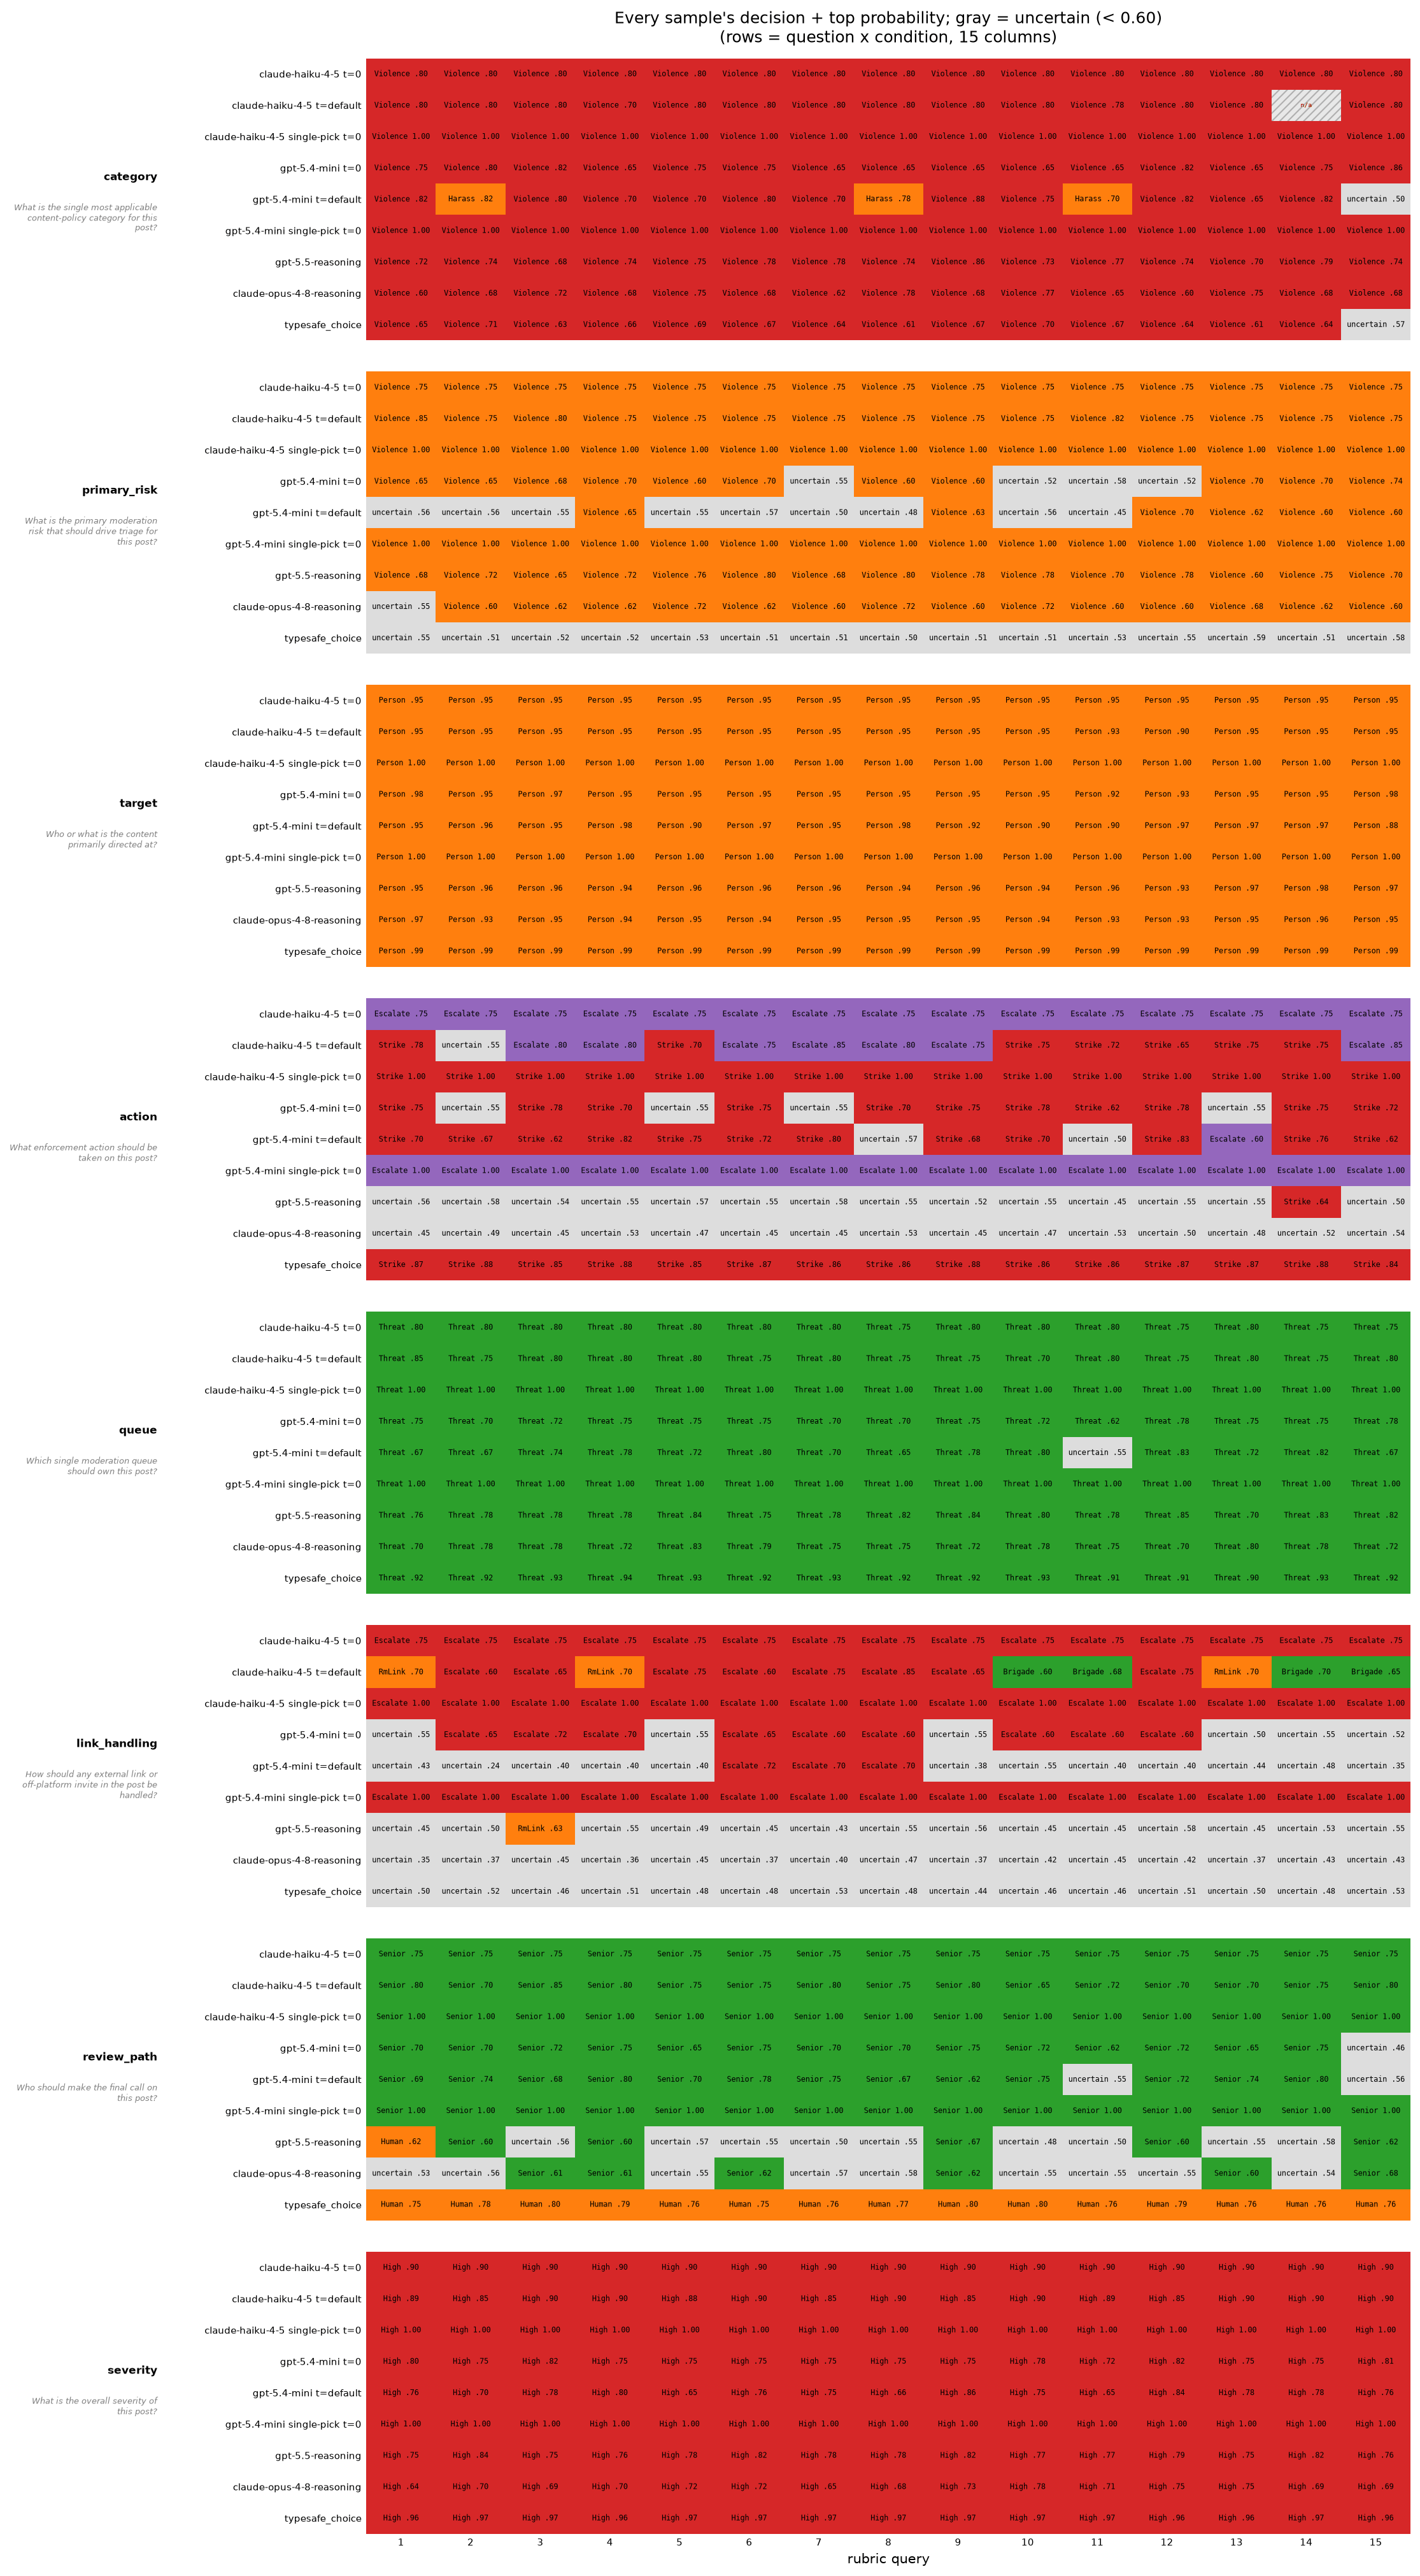
As perguntas mais claras mantêm-se estáveis: target lê Person e severity lê High em todas as condições. As limítrofes dividem-se entre condições: category, primary_risk, action, review_path e link_handling. Algumas condições também alternam dentro das suas 15 repetições. Antes da abstenção, o TypeSafe altera o seu rótulo principal em primary_risk (Harassment 11 vezes, Violence 4 vezes) e link_handling (RmLink 8 vezes, Brigade 7 vezes). Ambas as linhas mostram agora uncertain em toda a parte, porque as suas probabilidades máximas estão abaixo de 0.60.
Desvio padrão da probabilidade
Isso analisa os vetores de probabilidade completos, não apenas o rótulo escolhido. Para cada condição, coletamos todas as 15 distribuições para cada pergunta, calculamos o desvio padrão da probabilidade de cada rótulo entre as repetições (o quanto ele varia de execução para execução) e, em seguida, fazemos a média desses desvios padrão sobre todos os rótulos e perguntas. Também relatamos o maior desvio padrão de rótulo único e contamos as falhas de análise separadamente.
A tabela compara cada condição de LLM que produz probabilidades em relação ao TypeSafe. As linhas de escolha única foram omitidas, pois emitem rótulos definitivos em vez de distribuições de probabilidades.
def probability_std_stats(samples: list) -> tuple[float, float, float]:
    """Mean label std dev, max label std dev, parse-failure rate."""
    label_stds = []
    parse_failures = []
    for question_key in QUESTIONS:
        arr = np.array(
            [sample[question_key] for sample in samples],
            dtype=float,
        )
        parse_failures.extend(np.isnan(arr).any(axis=1).tolist())
        label_stds.extend(np.nanstd(arr, axis=0).tolist())
    return (
        float(np.nanmean(label_stds)),
        float(np.nanmax(label_stds)),
        float(np.mean(parse_failures)),
    )


PROBABILITY_OUTPUT_LABELS = [
    condition["label"] for condition in CONDITIONS if condition["mode"] == "dist"
] + [TYPESAFE_LABEL]
probability_std_by_label = {
    label: probability_std_stats(pooled_runs[label])
    for label in PROBABILITY_OUTPUT_LABELS
}
typesafe_mean_std = probability_std_by_label[TYPESAFE_LABEL][0]

print(
    f"{'condition':<{name_w}}{'mean prob std':>15}{'max prob std':>14}"
    f"{'parse fail':>12}{'x TypeSafe':>12}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    mean_std, max_std, parse_failure_rate = probability_std_by_label[label]
    relative_std = mean_std / typesafe_mean_std
    print(
        f"{label:<{name_w}}{mean_std:>15.4f}{max_std:>14.4f}"
        f"{parse_failure_rate:>11.0%}{relative_std:>12.2f}x"
    )
condition mean prob std max prob std parse fail x TypeSafe
claude-haiku-4-5 t=0 0.0012 0.0221 0% 0.12x
claude-haiku-4-5 t=default 0.0516 0.3150 1% 5.29x
gpt-5.4-mini t=0 0.0312 0.0905 0% 3.20x
gpt-5.4-mini t=default 0.0543 0.2303 0% 5.56x
gpt-5.5-reasoning 0.0305 0.1047 0% 3.12x
claude-opus-4-8-reasoning 0.0245 0.0693 0% 2.52x
typesafe_choice 0.0098 0.0515 0% 1.00xNesta execução, o TypeSafe apresenta um desvio padrão médio de probabilidade de 0.0098 e um desvio padrão máximo de rótulo único de 0.0515. O Haiku a temperatura 0 tem um desvio padrão médio menor de 0.0012. As outras cinco condições de probabilidade do LLM variam de 0.0245 a 0.0543, aproximadamente de 2.5x a 5.6x da média do TypeSafe. Pequenas alterações ainda podem inverter o rótulo principal quando dois rótulos estão próximos.
Enredo: acordo de decisão com resultado incerto
Retorne uncertain quando a probabilidade mais alta estiver abaixo de 0.60. Para cada condição de saída de probabilidade e pergunta, conte a decisão de aplicação mais comum, incluindo uncertain, e divida por todas as 15 extrações. Falhas de análise contam contra o acordo. Cada barra faz a média da pontuação sobre todas as 8 perguntas, com o maior acordo em primeiro lugar.
Condições de LLM de escolha única são excluídas porque não fornecem estimativa de incerteza.
# Compute policy decisions and agreement once for both this chart and the comparison table.
decisions_by_condition = {}
policy_agreement_by_condition = {}
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = [
        [
            choice_decision_with_uncertainty(sample[key], list(choices))
            for sample in pooled_runs[label]
        ]
        for key, (_instructions, choices) in QUESTIONS.items()
    ]
    decisions_by_condition[label] = decisions
    shares = [
        max(Counter(value for value in row if value is not None).values(), default=0)
        / NUM_SAMPLES
        for row in decisions
    ]
    policy_agreement_by_condition[label] = mean(shares)

# Sort by the measured agreement, keeping TypeSafe's color independent of its rank.
bar_labels = sorted(
    PROBABILITY_OUTPUT_LABELS, key=policy_agreement_by_condition.__getitem__, reverse=True
)
rates = [policy_agreement_by_condition[label] for label in bar_labels]

fig_bar, bar_ax = plt.subplots(figsize=(7, 0.45 * len(bar_labels) + 1))
positions = range(len(bar_labels))
bar_ax.barh(
    list(positions),
    rates,
    color=["#2b8cbe" if label == TYPESAFE_LABEL else "#fe9929" for label in bar_labels],
    alpha=0.85,
)
for label, position, rate in zip(bar_labels, positions, rates):
    marker = "*" if label == "claude-haiku-4-5 t=0" else ""
    bar_ax.text(
        rate + 0.01, position, f"{rate:.1%}{marker}", va="center", fontsize=8, color="gray"
    )
bar_ax.set_yticks(list(positions))
bar_ax.set_yticklabels(bar_labels, fontsize=8)
bar_ax.invert_yaxis()  # first condition on top
bar_ax.set_xlim(0, 1.08)
bar_ax.set_xticks(np.linspace(0, 1, 6))
bar_ax.set_xlabel("decision agreement across 15 re-runs (mean over 8 questions)")
for edge in ("top", "right", "left"):
    bar_ax.spines[edge].set_visible(False)
bar_ax.tick_params(length=0)
fig_bar.suptitle("Decision agreement including uncertain outcomes", y=1.0)
# Keep the caveat inside the exported chart so it travels with the 100% annotation.
fig_bar.text(
    0.01,
    0.01,
    "* Haiku t=0: 100% repeatability does not imply correctness.\n"
    "  This experiment does not measure accuracy.",
    fontsize=8,
)
fig_bar.tight_layout(rect=(0, 0.11, 1, 1))
display(fig_bar)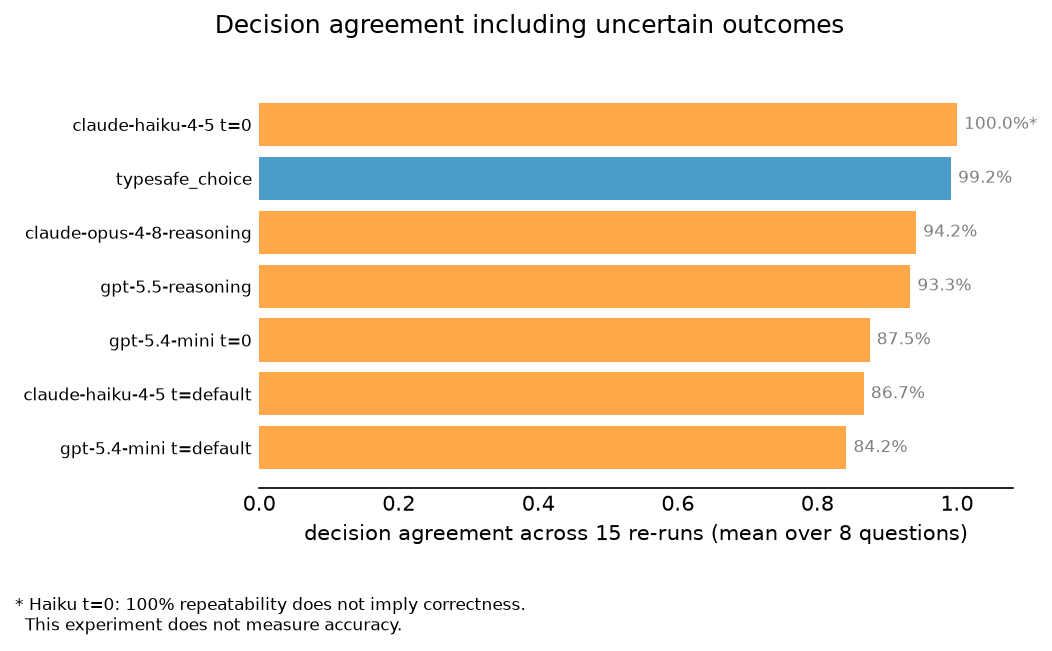
Sob a mesma regra 0.60, o Haiku a temperatura 0 obteve 100%. O TypeSafe obteve 99,2%, e as outras condições de LLM ficaram entre 84,2% e 94,2%. O TypeSafe retornou uncertain em 25,8% das respostas e agiu automaticamente nas outras 74,2%; o Haiku a temperatura 0 nunca se absteve. Essas porcentagens medem apenas a repetibilidade. A tabela abaixo mostra as taxas brutas de concordância e abstenção ao lado da concordância de política neste gráfico.
Que probabilidades incertas produzam uma decisão incerta
Uma pequena mudança na probabilidade pode trocar dois rótulos próximos. A aplicação não precisa agir sobre o vencedor: retornar uncertain quando a probabilidade superior estiver abaixo de 0.60, e enviar esse caso para um humano. Em exatamente 0.60, selecionar o rótulo superior. Isso usa as probabilidades retornadas, não o campo separado confidence da API, e não adiciona chamadas de modelo.
O limiar é uma política de aplicação ilustrativa, não uma garantia calibrada ou um limiar escolhido para maximizar o acordo desta execução. Escolha limiares de produção usando exemplos rotulados e o custo de ações incorretas e revisão humana.
Aplicamos a mesma regra a cada condição de saída de probabilidade. As respostas de LLM de escolha única não possuem estimativa de probabilidade; seus vetores one-hot sintéticos não podem medir a incerteza, portanto, são excluídos do gráfico e da tabela de concordância.
def agreement_rate(samples: list) -> float:
    """Mean over questions of the raw plurality label's share across all NUM_SAMPLES draws.

    Parse failures count against agreement because a failed route is not a repeated decision.
    """
    shares = []
    for question_key, (_instructions, choices) in QUESTIONS.items():
        labels = list(choices)
        picks = [
            argmax_label(samples[sample][question_key], labels)
            for sample in range(NUM_SAMPLES)
        ]
        picks = [pick for pick in picks if pick is not None]
        if not picks:
            shares.append(0.0)
            continue
        top = Counter(picks).most_common(1)[0][1]
        shares.append(top / NUM_SAMPLES)
    return mean(shares) if shares else float("nan")


# Keep failures separate from abstentions and count conflicting concrete actions per question.
print(
    f"{'condition':<{name_w}}{'raw agree':>12}{'policy agree':>14}"
    f"{'uncertain':>12}{'automatic':>12}{'conflicts':>11}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = decisions_by_condition[label]
    flat = [value for row in decisions for value in row]
    uncertain_rate = mean(value == "uncertain" for value in flat)
    automatic_rate = mean(value not in (None, "uncertain") for value in flat)
    conflicts = sum(
        len({value for value in row if value not in (None, "uncertain")}) > 1
        for row in decisions
    )
    print(
        f"{label:<{name_w}}{agreement_rate(pooled_runs[label]):>11.1%}"
        f"{policy_agreement_by_condition[label]:>13.1%}{uncertain_rate:>11.1%}"
        f"{automatic_rate:>11.1%}{conflicts:>11}"
    )
condition raw agree policy agree uncertain automatic conflicts
claude-haiku-4-5 t=0 100.0% 100.0% 0.0% 100.0% 0
claude-haiku-4-5 t=default 87.5% 86.7% 0.8% 98.3% 2
gpt-5.4-mini t=0 99.2% 87.5% 12.5% 87.5% 0
gpt-5.4-mini t=default 90.8% 84.2% 22.5% 77.5% 2
gpt-5.5-reasoning 90.0% 93.3% 30.8% 69.2% 1
claude-opus-4-8-reasoning 92.5% 94.2% 33.3% 66.7% 0
typesafe_choice 90.8% 99.2% 25.8% 74.2% 0policy agree conta uncertain como uma decisão; falhas de análise contam contra o acordo.
automatic é a parcela de todas as respostas que selecionam um rótulo. conflicts conta perguntas
com mais de um rótulo concreto entre as repetições, ignorando abstenções. Essas medidas
descrevem a repetibilidade e com que frequência o aplicativo age, não se suas ações são
corretas.
A concordância do TypeSafe subiu de 90,8% para 99,2%. Das respostas, 25,8% foram incertas e
74,2% automáticas. primary_risk e link_handling retornaram incertos em todas as repetições;
category alternou entre Violence e uncertain, cruzando o limite de ação em
algumas repetições e não em outras. Nenhuma pergunta produziu dois rótulos TypeSafe concretos diferentes.
Nada disso mostra precisão ou superioridade: Haiku a temperatura 0 teve concordância de 100%
aqui, sem abstenções.
# Show every TypeSafe decision while retaining the top probability behind it.
policy_decisions = decisions_by_condition[TYPESAFE_LABEL]
policy_values = []
for row, (_key, (_instructions, choices)) in zip(policy_decisions, QUESTIONS.items()):
    labels = list(choices)
    policy_values.append([
        10 if value == "uncertain" else labels.index(value) if value is not None else np.nan
        for value in row
    ])
policy_cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
policy_cmap.set_bad("white")
fig_policy, ax_policy = plt.subplots(figsize=(13, 4))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=10, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
    for sample_index in range(NUM_SAMPLES):
        decision = policy_decisions[row_index][sample_index]
        probability = max(typesafe_runs[sample_index][key])
        ax_policy.text(sample_index, row_index, f"{decision or 'n/a'}\n{probability:.2f}",
                       ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
    "TypeSafe application decisions: gray means uncertain "
    f"(top probability < {MIN_CHOICE_PROBABILITY:.2f})"
)
fig_policy.tight_layout()
display(fig_policy)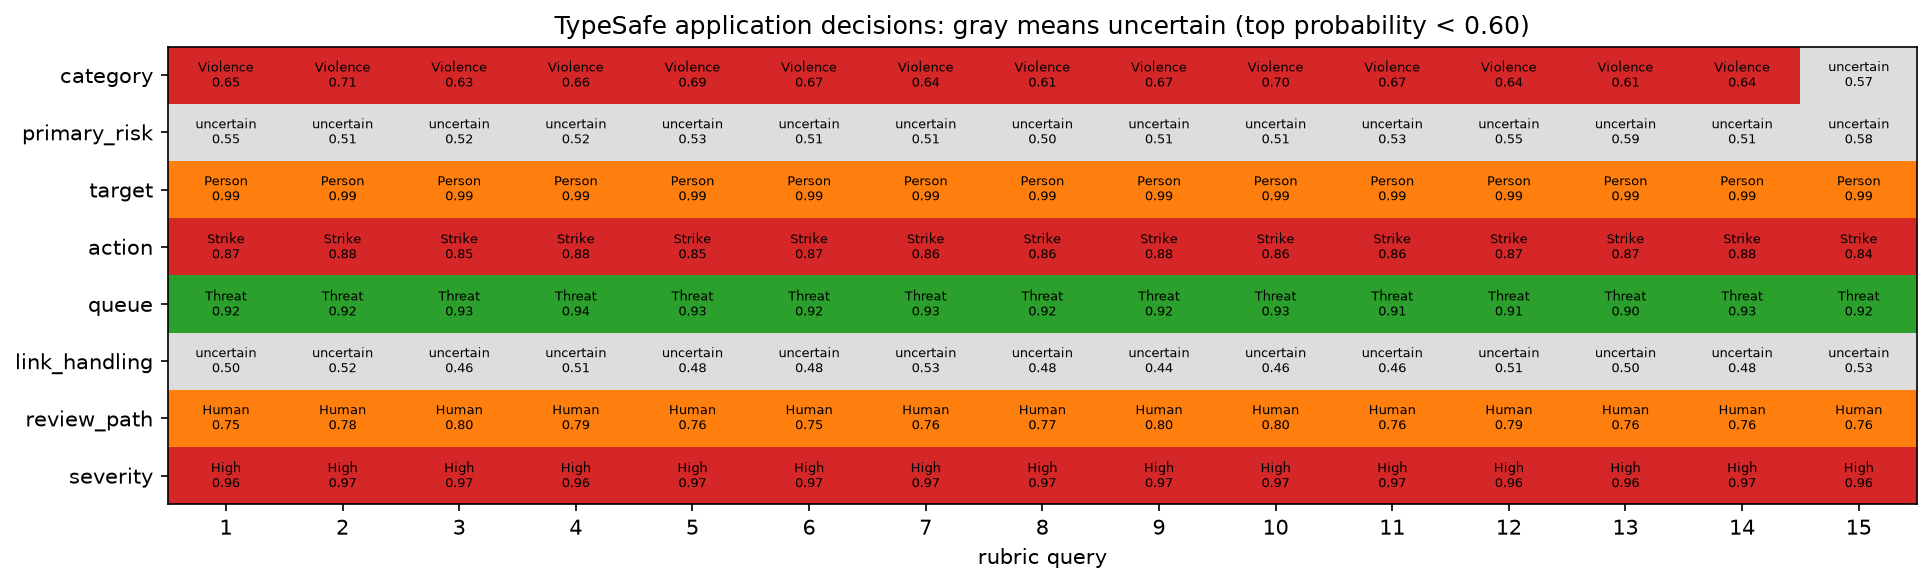
Esta política não torna o modelo determinístico. A abstenção pode substituir rótulos concorrentes pelo mesmo resultado de revisão humana, mas uma probabilidade próxima de 0.60 ainda pode mudar entre um rótulo concreto e uncertain. As estatísticas de probabilidade e a coluna raw agree da tabela ainda reportam as saídas do modelo original.
Abra no playground TypeSafe
O link abaixo abre a mesma postagem e rubrica no playground: uma postagem, os mesmos 8
Choices, e TypeSafe jev-latest.
playground_link = make_playground_link(
    {"post": POST},
    {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this post + rubric in the TypeSafe playground]({playground_link})"
    )
)