 JevCode
Cascata SDE
Utiliza uma cascata de extração de dados estruturados em 2 estágios (mini → verify → reasoning) para obter a maior parte da qualidade de um modelo de raciocínio grande por uma fração do custo.
Traduzido automaticamente do en, sem revisão. Apenas como referência rápida.

- Visão geral
- modelos de raciocínio grandes extraem dados estruturados bem, mas são lentos e caros
- modelos pequenos são baratos, mas cometem erros
- uma cascade obtém a maior parte da qualidade por uma fração do custo
- os modelos que usamos, e seus preços ($ por 1M tokens, input / output; tarifas padrão verificadas em 15 de setembro de 2026):
- rung 0 (mini):
gpt-5.4-minia $0.75 / $4.50 - rung 1 (reasoning):
gpt-5.5a $5.00 / $30.00 (aproximadamente 7x o mini) - verifier: TypeSafe
jev-1.12a $0.042 / $0.00 (tokens de saída são gratuitos; published Jev pricing) - Algoritmo
- Extract com um modelo barato/pequeno.
- Verify com primitivas TypeSafe: uma pergunta sim/não por campo (“Noul question”) pergunta
- (por exemplo, “este valor está ausente na fonte?”, “foi extraído de texto não relacionado ?”), cada uma retornando P(algo está errado).
- Escalate para um modelo de raciocínio caro se um sinal do verifier for acionado; caso contrário, mantenha a resposta barata.
- Este Cookbook
- percorre um exemplo real do início ao fim, depois mostra a compensação em 100 prompts
- nota: os dois rungs de extração usam OpenAI em modo texto
- nós não usamos saídas estruturadas, chamadas de ferramentas ou modo json, porque:
- um erro de schema following não é o erro que esperamos que um LLM cometa (é fácil gerar dados sintéticos para isso)
- se um LLM falhar ao seguir o schema, quase sempre está muito confuso, então constrained decoding não corrige o problema subjacente
- encorajamos você a tentar, no entanto!
Configuração
- instalar as dependências (o cliente verificador TypeSafe é servido a partir do índice de pacotes da TypeSafe):
pip install openai datasets jsonschema ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/- defina
OPENAI_API_KEYeTYPESAFE_API_KEYno seu ambiente
import json
import os
from pathlib import Path

import jsonschema
from cooksafe import JsonCache, make_playground_link
from datasets import load_dataset
from IPython.display import Markdown, display
from openai import OpenAI
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

MINI = "gpt-5.4-mini"  # rung 0: cheap + fast
REASONING = "gpt-5.5"  # rung 1: strong, run with reasoning_effort="high"
TS_MODEL = "jev-1.12"  # the TypeSafe verifier model
FIRE_T = 0.7  # escalate if any per-field P(wrong) exceeds this; also the "<== FIRES" display marker

oai = OpenAI()

ts = TypeSafeClient(api_key=os.environ["TYPESAFE_API_KEY"], timeout=30.0)
Passo 1: os dados
Escolhemos um dataset do huggingface chamado scrapegraphai
SCRAPEGRAPHAI_REVISION = "4bb9fba1dff9181c5acdb60a5a26fea62fa54fe9"
row = load_dataset(
    "scrapegraphai/scrapegraphai-100k",
    revision=SCRAPEGRAPHAI_REVISION,
    split="train",
)[516]
schema = json.loads(row["schema"])
prompt = row["prompt"]
content = row["content"]

print(
    f"""
PROMPT
===========
{prompt}

SCHEMA
===========
{json.dumps(schema, indent=2)}

CONTENT
===========
{content}
""".strip()
)
PROMPT
===========
Find registration open date fall semester for New York University in New York, NY for the 2024-2025 school year.
SCHEMA
===========
{
"properties": {
"registration_open_date": {
"description": "The date that registration opens for the fall semester. MUST be in the format mm/dd/yyyy. For example, for a college in the 2024-2025 school year, it might be something like 09/05/2024. Return a blank string if you are unsure.",
"title": "Registration Open Date",
"type": "string"
},
"description": {
"description": "A brief description of the registration open date. For example, 'Registration opens for the fall semester'.",
"title": "Description",
"type": "string"
}
},
"required": [
"registration_open_date",
"description"
],
"title": "RegistrationOpen",
"type": "object"
}
CONTENT
===========
Skip to content Skip to current page navigation
[ ](https://www.nyu.edu/)
Search Site
[ ](https://www.nyu.edu/)
* [ Academics](https://www.nyu.edu/academics.html)
* [ Admissions](https://www.nyu.edu/admissions.html)
* [ Research](https://www.nyu.edu/research.html)
* [ University Life](https://www.nyu.edu/life.html)
* [ About](https://www.nyu.edu/about.html)
All NYU
# Mobile Navigation
[ ](https://www.nyu.edu/)
Search Site
* [Academics](https://www.nyu.edu/academics.html)
* [Admissions](https://www.nyu.edu/admissions.html)
* [Research](https://www.nyu.edu/research.html)
* [University Life](https://www.nyu.edu/life.html)
* [About](https://www.nyu.edu/about.html)
All NYU
Info for
* Back to main menu
* Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](http://home.nyu.edu/)
Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](https://home.nyu.edu/)
Search Site Search
# Events Calendar
Search Events
Apply Reset
* [About the Events Calendar ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar.html)
* [Events Calendar Tutorial ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar/tutorials.html)
* [Report issue or provide feedback ](https://nyu.service-now.com/sp?id=sc_cat_item&sys_id=7698dd2a98bcf4004c8c03063d84e274)
Search Filters Calendar
New York University
Equal Opportunity and Non-Discrimination at NYU - New York University is committed to maintaining an environment that encourages and fosters respect for individual values and appropriate conduct among all persons. In all University spaces--physical and digital--programming, activities, and events are carried out in accordance with applicable law as well as University policy, which includes but is not limited to its Non-Discrimination and Anti-Harassment Policy.
Unless otherwise noted, all content copyright New York University. All rights reserved.
* [Search](https://search.nyu.edu/)
* [Campus Map](https://www.nyu.edu/map.html)
* [Events](https://events.nyu.edu/)
* [Contact Us](https://www.nyu.edu/contact-us.html)
* [Give](https://www.nyu.edu/about/giving.html)
* [Copyright & Fair Use](https://www.nyu.edu/copyright-and-fair-use.html)
* [Privacy](https://www.nyu.edu/privacy.html)
* [Accessibility](https://www.nyu.edu/accessibility.html)
* [Feedback](https://www.nyu.edu/#feedback.html)
* [New York Campus](https://www.nyu.edu/)
* [Abu Dhabi Campus](https://nyuad.nyu.edu/)
* [Shanghai Campus](https://shanghai.nyu.edu/)
* [](https://facebook.com/)
* [](https://linkedin.com/)
* [](https://x.com/)
* [](https://instagram.com/)
* [](https://youtube.com/)- Esta linha é uma página do calendário de eventos da NYU (“Data do Censo de Outono 2024”):
- o esquema pede apenas dois campos:
registration_open_dateedescription - a raspagem do prompt capturou apenas a navegação do calendário e o texto padrão: não há data de inscrição, ou descrição
- observe que o campo
descriptiondo esquema já envia um valor de exemplo (“A inscrição abre para o semestre de outono”) na própria descrição do campo - então um extrator bem-comportado deve recusar inventar os campos que a página não contém
- vamos ver se o modelo pequeno faz a coisa certa!
Passo 2: extrair com o modelo mini (modo texto)
- nota:
gpt-5.4-minié muito estocástico nesta entrada – mesmo emtemperature=0ele inventa umdescriptiondiferente em quase todas as execuções. Para um passeio reproduzível, nós codificamos a única fabricação canônica que o restante deste notebook explica (e que o verificador sinaliza em P(errado) > 0.8). Um pipeline real simplesmente usariaextract(MINI, prompt, schema, content, temperature=0)diretamente.
EXTRACT_SYSTEM = (
    "You extract structured data from documents. Return only values supported by the text. "
    "Follow any value format specified by the schema or its field descriptions."
)


# LLM and TypeSafe calls are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published results with no API spend; delete the file to re-run live.
json_cache = JsonCache(Path("json_cache.json"))


@json_cache
def extract(
    model: str,
    prompt: str,
    schema: dict,
    content: str,
    *,
    reasoning_effort: str | None = None,
    temperature: float | None = None,
) -> dict:
    user = (
        f"{prompt}\n\nReturn ONLY a JSON object matching this JSON Schema:\n"
        f"{json.dumps(schema, indent=2)}\n\nDocument:\n{content}"
    )
    kwargs = {
        "model": model,
        "messages": [
            {"role": "system", "content": EXTRACT_SYSTEM},
            {"role": "user", "content": user},
        ],
    }
    if reasoning_effort:
        kwargs["reasoning_effort"] = reasoning_effort
    if temperature is not None:
        kwargs["temperature"] = temperature
    text = oai.chat.completions.create(**kwargs).choices[0].message.content
    # The prompt asks for ONLY a JSON object, so parse the reply as-is -- no regex fishing a
    # substring out of a malformed reply. If ``json.loads`` fails, treat it as an empty extraction
    # (the record-level analog of NaN): every field reads as absent, which the verifier flags and the
    # gate escalates -- the safe direction. Schema-following errors are rare here (see the overview).
    try:
        return json.loads(text)
    except (ValueError, json.JSONDecodeError):
        return {}


# Hard-coded canonical fabrication (see note above); a real pipeline would use extract(MINI, prompt, schema, content, temperature=0).
mini_record = {
    "registration_open_date": "",
    "description": "Registration opens for the fall semester",
}
print("mini extraction:\n", json.dumps(mini_record, indent=2))

# The record is a perfect fit for the JSON Schema -- and still wrong. Schema validation is necessary
# but not sufficient: it catches structural errors, never semantic ones. That gap is the whole point.
print("\nschema-valid:", jsonschema.Draft202012Validator(schema).is_valid(mini_record))
mini extraction:
{
"registration_open_date": "",
"description": "Registration opens for the fall semester"
}
schema-valid: True- O registro é schema-valid (a linha acima imprime
True), mas está errado: registration_open_datefica em branco, o que corresponde à página: ela afirma que não há data- mas
descriptioné fabricado: a página nunca descreve uma data de registro, então mini inventa uma plausível. Pode repetir o próprio exemplo do schema, “Registration opens for the fall semester”, ou narrar “…was not found in the document” - uma verificação JSON-Schema não consegue perceber isso. Um modelo barato produz fabricações confiantes que satisfazem o schema deste tipo, e a tarefa de detectá-las cabe a um verificador semântico
Passo 3: verifique com TypeSafe
- o verificador é TypeSafe; para cada campo, construímos uma
Noulpergunta: - um sim/não restrito, formulado de modo que
true= algo está errado (escalar) - TypeSafe retorna uma
noulcalibrada =P(true)por pergunta, em uma única chamada system_one - o conjunto de perguntas:
- uma cabeça holística
__overall__::judge(“este registro deve ser escalado?”). Nós a calculamos e exibimos para contrastar um julgamento de registro inteiro com as cabeças por campo, mas o portão na Etapa 4 não a utiliza – a escalada é conduzida pela bateria por campo. - uma bateria por campo
- campos não vazios recebem o conjunto completo de cabeças
- campos vazios (null / “” / []) recebem apenas a cabeça
absence_wrong - (o pipeline completo também possui uma cabeça
spuriouspara contêineres inteiros e uma pontuação geraldifficulty; não mostrada aqui, para manter este walkthrough limitado às duas cabeças de gateamento) - A Maneira TypeSafe: Decomposição
- Observe como tudo é programaticamente decomposto, esta é a maneira TypeSafe.
- A decomposição maximiza a inteligência de cada prompt, e torna o algoritmo ajustável e interpretável.
-
# metric -> (question, NoulCriteria)
MAIN_QUESTIONS = {
    "name_desc_mismatch": (
        "Does the `extracted_field` fail to match the field at `path` or the `description` in the "
        "`field_spec`? If the `description` is empty, judge against the `path` alone.",
        NoulCriteria(
            true="the `extracted_field` does not match the field name or its `description`",
            false="the `extracted_field` matches the field name and `description`",
        ),
    ),
    "type_mismatch": (
        "Does the `extracted_field` violate the `type` declared in the `field_spec`?",
        NoulCriteria(
            true="the `extracted_field` violates the declared `type`",
            false="the `extracted_field` conforms to the declared `type`",
        ),
    ),
    "unreasonable": (
        "Is the `extracted_field` one that a reasonable person would not have extracted for this "
        "`field_spec`?",
        NoulCriteria(
            true="a reasonable person would not have extracted this value",
            false="the extraction is reasonable",
        ),
    ),
    "hallucinated": (
        "Is the `extracted_field` unsupported by, or absent from, the source text?",
        NoulCriteria(
            true="the `extracted_field` is a hallucination -- not supported by, or absent "
            "from, the source text",
            false="the `extracted_field` is supported by the source text",
        ),
    ),
    "off_target": (
        "Does the source text fail to genuinely report the thing the `field_spec` describes, so the "
        "value was pulled from incidental text?",
        NoulCriteria(
            true="the source does not genuinely provide this field -- the value was pulled "
            "from incidental text",
            false="the source genuinely reports this field",
        ),
    ),
    "incomplete": (
        "Does the `extracted_field` fail to capture a value the source supports (note whether the "
        "`field_spec` is `required`)?",
        NoulCriteria(
            true="the field is wrongly empty, null, or missing a value the source supports",
            false="the field captures the value the source supports",
        ),
    ),
    "format_violation": (
        "Does the `extracted_field` violate the format or constraints implied by the `description`, "
        "the schema `type`, and the extraction instructions (e.g. date format, units, enum membership)?",
        NoulCriteria(
            true="the `extracted_field` violates the implied format or constraints",
            false="the `extracted_field` satisfies the format and constraints",
        ),
    ),
}
ABSENCE_QUESTION = (
    "The `extracted_field` is empty, null, or an empty collection. Does the source text contain the "
    "information the `field_spec` describes, making the empty result wrong?"
)
ABSENCE_CRITERIA = NoulCriteria(
    true="a value was wrongly omitted", false="returning nothing is correct"
)

# The pipeline also asks one holistic, whole-record head: "should this be escalated?"
OVERALL_JUDGE = (
    "Is this extracted record an incorrect extraction -- some value unsupported by the source or "
    "not conforming to the schema, required information missing or wrong, or some field hallucinated -- "
    "so it should be escalated to a smarter model?"
)
OVERALL_JUDGE_CRITERIA = NoulCriteria(
    true="the record is an incorrect extraction",
    false="the record is a correct extraction",
)


def is_empty(v) -> bool:
    return v is None or (isinstance(v, (str, list, dict)) and len(v) == 0)


def field_spec(name: str) -> dict:
    """Minimal spec pulled from the schema (unwrapping anyOf/null for optional fields)."""
    p = schema["properties"][name]
    branches = p.get("anyOf") or []
    typ = p.get("type") or next(
        (b["type"] for b in branches if b.get("type") != "null"), "unknown"
    )
    return {
        "path": name,
        "type": typ,
        "description": p.get("description", ""),
        "required": name in schema.get("required", []),
    }


def build_questions(record: dict) -> dict[str, Noul]:
    """The verify question set: one holistic ``__overall__::judge`` head plus a per-field battery,
    keyed ``field::metric`` (mirrors build_verify_prompts)."""
    questions: dict[str, Noul] = {
        "__overall__::judge": Noul(
            instructions=OVERALL_JUDGE, criteria=OVERALL_JUDGE_CRITERIA
        ),
    }
    for name, value in record.items():
        spec = field_spec(name)
        if is_empty(value):
            questions[f"{name}::absence_wrong"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": ABSENCE_QUESTION,
                },
                criteria=ABSENCE_CRITERIA,
            )
            continue
        for metric, (question, criteria) in MAIN_QUESTIONS.items():
            if metric == "type_mismatch" and spec["type"] == "unknown":
                continue
            questions[f"{name}::{metric}"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": question,
                },
                criteria=criteria,
            )
    return questions


@json_cache
def verify(record: dict) -> dict[str, float | str]:
    """Run the whole Noul battery over a record in one TypeSafe call; return ``{field::metric: P(true)}``."""
    state = {
        "system_message": EXTRACT_SYSTEM,
        "instruction": "Extract the structured record from this document",
        "source_text": row["content"],
        "schema": schema,
        "extraction": record,
    }
    questions = build_questions(record)
    answers = ts.system_one(state=state, questions=questions, model=TS_MODEL).answers
    return {qid: ans.noul for qid, ans in answers.items()} | {
        "playground_link": make_playground_link(state, questions)
    }
Execute a bateria inteira sobre a extração mini
checks = verify(mini_record)
playground_link = checks.pop("playground_link")
display(
    Markdown(
        f"🔗 [Open this verification in the TypeSafe playground]({playground_link})"
    )
)

print(f"{'qid':<40}{'P(wrong)':>9}")
print("-" * 50)
for fld, p in sorted(checks.items(), key=lambda c: -c[-1]):
    flag = "  <== FIRES" if p > FIRE_T else ""
    print(f"{fld:<40}{p:>9.2f}{flag}")
qid P(wrong)
--------------------------------------------------
description::hallucinated 0.95 <== FIRES
description::off_target 0.85 <== FIRES
description::unreasonable 0.58
__overall__::judge 0.56
description::incomplete 0.16
registration_open_date::absence_wrong 0.14
description::format_violation 0.10
description::name_desc_mismatch 0.08
description::type_mismatch 0.02Abra esta verificação no playground TypeSafe →
- O TypeSafe concentra o sinal nos campos que estão realmente errados.
- Nossos resultados são calibrados: alto no campo que está errado, baixo no campo que está correto, médio em um campo que parece fora do padrão sem estar claramente errado
- Isso é o que um verificador typesafe oferece a você em vez de um juiz bruto “isso tudo está bom?”
Passo 4: a barreira de escalonamento
- agora aplicamos o filtro em
any_flag: escalar se qualquer sinal de campo excederFIRE_T(0,7, definido acima e compartilhado com o marcador<== FIRESna Etapa 3) - este é um filtro do estilo
max(escalar se qualquer sinal de campo for acionado), não uma média, portanto um único sinal vermelho confiável é suficiente, em vez de ser diluído pelo silêncio
# any_flag is a per-field gate: the holistic __overall__ head is shown above but not part of it
fired = {
    qid: p
    for qid, p in checks.items()
    if not qid.startswith("__overall__") and p > FIRE_T
}
escalate = bool(fired)

print(
    f"any_flag gate (threshold {FIRE_T}): {'ESCALATE' if escalate else 'ACCEPT cheap result'}"
)
for qid, p in sorted(fired.items(), key=lambda c: -c[1]):
    print(f"  fired: {qid}  (P={p:.2f})")
any_flag gate (threshold 0.7): ESCALATE
fired: description::hallucinated (P=0.95)
fired: description::off_target (P=0.85)Passo 5: escalar para o modelo de raciocínio
Como um sinal foi disparado, pagamos pelo modelo forte (gpt-5.5, reasoning_effort="high")
final_record = (
    extract(REASONING, prompt, schema, content, reasoning_effort="high")
    if escalate
    else mini_record
)

print("mini      :", json.dumps(mini_record))
print("reasoning :", json.dumps(final_record))
print("\nfield-level diff (mini -> final):")
for name in mini_record:
    if mini_record[name] != final_record.get(name):
        print(f"  {name}: {mini_record[name]!r}  ->  {final_record.get(name)!r}")
mini : {"registration_open_date": "", "description": "Registration opens for the fall semester"}
reasoning : {"description": "", "registration_open_date": ""}
field-level diff (mini -> final):
description: 'Registration opens for the fall semester' -> ''- A melhoria
- O modelo de raciocínio descarta a fabricação
description, retornando"" - Reconheceu que a página nunca descreve uma data de registro e recusou-se a inventar uma
- A cascata transformou uma fabricação confiante e válida por esquema em um campo vazio honesto
- E gastou apenas dólares do modelo de raciocínio neste único item porque o verificador ordenou que o fizesse
Passo 6: como isso se parece em 100 prompts
- Estes são os resultados internos do TypeSafe, produzidos com o método geral acima:
- o mesmo loop
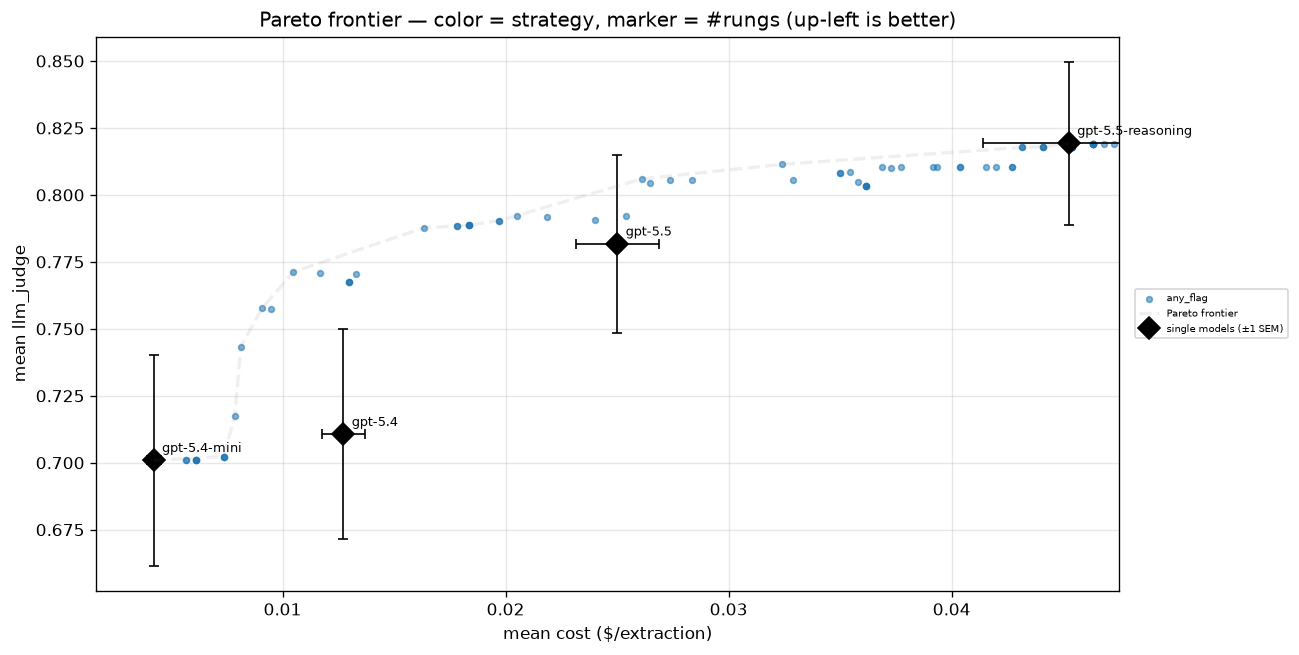
extract → verify → escalate,gpt-5.4-mini → gpt-5.5-reasoning,any_flaggate sobre as cabeças por campo, executado sobre 100 prompts scrapegraphai - a extração de baixo custo de cada item é pontuada pelo TypeSafe; o limiar do gate (“cut”) é varrido de 0→1, e cada configuração resultante é plotada no espaço (custo, qualidade)
- o gráfico é uma captura histórica; seus custos não foram recalculados na taxa Jev atual listada acima
- como ler:
- black diamonds = os quatro modelos executados individualmente (o custo sobe com a capacidade; o mais forte,
gpt-5.5-reasoning, está no canto superior direito com ≈0.81 de qualidade por ≈$0.10/extracção) - blue points = a cascata em vários limiares de gate; a linha tracejada é a pareto frontier
- a fronteira da cascata situa-se acima e à esquerda de cada modelo individual: ajustar o gate permite obter a maior parte da qualidade do modelo principal por uma fração do seu custo
- o degrau económico trata os itens fáceis por quase de graça, e apenas os itens sinalizados pagam pelo modelo de raciocínio
Apêndice A: o que constitui um bom sinal verificador
- a cascata é tão boa quanto seu verificador; o que separa um sinal útil de um inútil:
- Estreito e fundamentado.
- uma verificação sim/não sobre um campo contra a fonte (ex.: “este valor está ausente na fonte?”), não uma pergunta vaga como “esta extração é boa?”
- perguntas vagas geram escores nebulosos e não calibrados
- Ruim = VERDADEIRO, com critérios explícitos.
- formule cada pergunta de modo que o caso de escalar seja o
true, e declare o quetrue/falsesignificam - Por campo, depois agregue com
max. - uma sinalização por campo localiza o erro e permanece esparsa e forte
max(“qualquer sinalização dispara”) garante que uma única sinalização vermelha confiante escale, em vez de ser diluída no silêncio- Independente e barato.
- um verificador dedicado (aqui, TypeSafe) julgando a saída captura os próprios pontos cegos do extrator
- precisa ser barato, ou não haverá economias restantes a capturar
- Separado / calibrado.
- um bom sinal é alto em erros reais e baixo em acertos, de modo que um único limiar divida claramente aceitar vs. escalar
- essa separação é o que empurra a curva de pareto para cima e para a esquerda