 JevCode
Autoconsistencia: elecciones
Añadir un resultado incierto a las decisiones de moderación y comparar la concordancia de etiquetas con la proporción de acciones automáticas.
Traducido automáticamente del en, sin revisión. Solo como referencia rápida.

Este libro de recetas toma una publicación de usuario en el límite, aplica un rúbrica de moderación sobre ella 15 veces,
y verifica si cada respuesta se mantiene estable a través de las repeticiones. Cada verificación es un
Choice, por lo que cada respuesta es una etiqueta de un conjunto fijo. En una tubería de moderación
esa etiqueta es la decisión de enrutamiento: eliminar o dejar visible, escalar o resolver automáticamente, enviar a la
cola de amenazas, spam o general. Cuando la etiqueta oscila de una ejecución a la siguiente,
la misma publicación se enruta a diferentes lugares sin una buena razón.
La rúbrica es de 8 Choice preguntas, y cada ejecución es una única llamada que responde a las 8. Realizamos
15
repeticiones por condición, donde una condición es un modelo más una configuración, y graficamos cada
etiqueta que se devolvió.
Las condiciones:
- Modelos de lenguaje grandes (LLM) no razonadores
claude-haiku-4-5ygpt-5.4-mini, a una temperatura0y la configuración predeterminada de la API. - Modelos de lenguaje grandes (LLM) de razonamiento
gpt-5.5yclaude-opus-4-8, que no tienen un dial de temperatura. - TypeSafe: una sola llamada
system_onea través de las 8 preguntasChoice, con un campouidnuevo (un valor único desechable) en cada llamada, que coincide con la configuración del cookbook de noul.
Qué buscar: las etiquetas seleccionadas pueden cambiar dentro de una única condición, incluyendo TypeSafe, y las condiciones discrepan entre sí.
En esta ejecución, los ajustes de distribución del LLM repiten sus etiquetas de pluralidad entre el 87,5 % y el 100 % de las veces, en comparación con el 90,8 % de TypeSafe. TypeSafe tiene una variación media de probabilidad menor que cinco de las seis condiciones de distribución del LLM; Haiku a temperatura 0 varía menos. Las probabilidades cercanas aún permiten cambios de enrutamiento: TypeSafe cambia en 2 de las 8 preguntas.
Para las decisiones de la aplicación, también requerimos una probabilidad superior de al menos 0.60; de lo contrario, el resultado es uncertain y pasa a revisión humana. El acuerdo de TypeSafe luego asciende al 99.2%, con etiquetas automáticas en el 74.2% de las respuestas. Mostramos las salidas en bruto y aplicamos el mismo umbral a las condiciones de probabilidad de LLM, manteniendo las abstenciones y los cambios visibles.
Configuración
pip install anthropic openai matplotlib ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/luego establece TYPESAFE_API_KEY, ANTHROPIC_API_KEY y OPENAI_API_KEY.
Esta ejecución utiliza jev-latest en la API de producción, muestreada el 2026-09-11.
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean

from time import perf_counter

import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Choice, TypeSafeClient

matplotlib.use("Agg")  # headless render

BASE_MODELS = [
    "claude-haiku-4-5",
    "gpt-5.4-mini",
]  # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
    "gpt-5.5",
    "claude-opus-4-8",
]  # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest"  # the TypeSafe model
NUM_SAMPLES = 15  # repeated post+rubric calls per condition
MIN_CHOICE_PROBABILITY = 0.60  # illustrative automatic-action threshold

LLM_PRICES = {  # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
    "claude-haiku-4-5": (1.00, 5.00),
    "gpt-5.4-mini": (0.75, 4.50),
    "gpt-5.5": (5.00, 30.00),
    "claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00)  # Historical TypeSafe rate, as of 2026-08

anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
    api_key=os.environ["TYPESAFE_API_KEY"],
    base_url="https://api.typesafe.ai",
    timeout=30.0,
)
El estado: una publicación de usuario límite, en JSON
El siguiente post está construido para mantenerse en la valla. El lenguaje es acalorado e insultante, dirigido en parte a una persona y en parte al argumento y a la comunidad. Contiene una invitación fuera de la plataforma (un enlace que lleva a los usuarios a otro sitio), una infracción previa en la cuenta y cuatro informes de usuarios, y el lenguaje con amenaza nunca está formulado de manera clara.
No hay una única respuesta obvia aquí, y ese es el punto: las pequeñas diferencias de redacción no deben mover aleatoriamente la misma publicación entre las rutas de aplicación.
Los LLMs reciben json.dumps(POST) en el prompt. TypeSafe recibe el diccionario de Python directamente.
POST = {
    "post_id": "P-88213",
    "author": {
        "user_id": "u/4471",
        "account_age_days": 38,
        "prior_strikes": 1,
        "followers": 210,
    },
    "context": {
        "surface": "public reply",
        "in_reply_to": "another user defending a game patch",
        "community": "r/gamedebates",
    },
    "content": {
        "text": (
            "Are you seriously this dense? Anyone who defends that patch is a complete clown and "
            "should be embarrassed to even post here. People like you are what's ruining this "
            "community and honestly you need to be dealt with. Come say it to my face, invite's "
            "right here. Keep it up and I'll end your whole channel."
        ),
        "has_link": True,
        "link_domain": "discord.gg",
        "language": "en",
    },
    "reports": {"user_reports": 4, "report_reasons": ["harassment", "spam", "threat"]},
}
La rúbrica: 8 Choice preguntas
Cada pregunta tiene un key, una línea de instrucciones y un conjunto de etiquetas fijo. Las etiquetas dentro de una pregunta son mutuamente excluyentes (exactamente una aplica), y cada una lleva una descripción corta. TypeSafe devuelve un choice seleccionado más una distribución probabilities sobre las etiquetas. Se pide a los LLMs que utilicen los mismos conjuntos de etiquetas, lo que mantiene comparable cada fila.
QUESTIONS = {
    "category": (
        "What is the single most applicable content-policy category for this post?",
        {
            "None": "No policy violation of any kind.",
            "Harass": "Insults or demeans a person, with no threat of harm and no protected-class attack.",
            "Hate": "Attacks a person or group over a protected characteristic (race, religion, gender, ...).",
            "Violence": "Makes a credible threat of harm or incites violence against someone.",
            "Spam": "Unsolicited promotion or link spam, with no personal attack.",
            "Sexual": "Sexual or adult content.",
        },
    ),
    "primary_risk": (
        "What is the primary moderation risk that should drive triage for this post?",
        {
            "Harassment": "Personal attack or targeted abuse is the main risk.",
            "Violence": "A threat of harm or intimidation is the main risk.",
            "LinkAbuse": "External-link or off-platform coordination risk is the main risk.",
            "AccountHistory": "Prior account history or repeat behavior is the main risk.",
            "LowRisk": "No meaningful moderation risk is present.",
        },
    ),
    "target": (
        "Who or what is the content primarily directed at?",
        {
            "None": "Not directed at anyone in particular.",
            "Person": "Directed at one specific individual.",
            "Group": "Directed at a protected group or class.",
            "Platform": "Directed at the community or platform itself, not a person.",
        },
    ),
    "action": (
        "What enforcement action should be taken on this post?",
        {
            "Allow": "Leave the post up with no action.",
            "Warn": "Leave the post up but attach a warning label.",
            "Remove": "Remove the post, but do not penalize the account.",
            "Strike": "Remove the post and add a strike to the account.",
            "Escalate": "Take no automated action; hold for a human decision.",
        },
    ),
    "queue": (
        "Which single moderation queue should own this post?",
        {
            "Auto": "Auto-resolve; no human queue needed.",
            "General": "General moderation queue.",
            "Threat": "Threat / violence response queue.",
            "Spam": "Spam and platform-abuse queue.",
            "TSLead": "Trust-and-safety lead / senior queue.",
        },
    ),
    "link_handling": (
        "How should any external link or off-platform invite in the post be handled?",
        {
            "Allow": "Leave the link in place.",
            "RmLink": "Strip or disable the link but keep the post.",
            "Brigade": "Treat the link as coordinated brigading and action it as abuse.",
            "Escalate": "Send the link to a specialist to assess before acting.",
        },
    ),
    "review_path": (
        "Who should make the final call on this post?",
        {
            "Auto": "Automated action; no human review.",
            "Human": "A frontline human moderator makes the call.",
            "Senior": "A senior or specialist reviewer is required.",
            "Legal": "Route to legal or law-enforcement escalation.",
        },
    ),
    "severity": (
        "What is the overall severity of this post?",
        {
            "None": "No violation.",
            "Low": "Rude or dismissive, but essentially harmless.",
            "Medium": "Personal harassment with no clearly credible threat.",
            "High": "Harassment together with a threat that could be read as credible.",
        },
    ),
}
Cómo lo pedimos
Cada llamada al LLM es un prompt que contiene json.dumps(POST), las 8 preguntas y todas las etiquetas permitidas. Hay dos formatos de respuesta. En el modo de distribución, el modelo devuelve un objeto JSON por pregunta con una probabilidad para cada etiqueta. En el modo de selección única, devuelve una etiqueta cruda por pregunta, y nuestro análisis concentra toda la masa de probabilidad en esa etiqueta.
La llamada TypeSafe es una system_one solicitud sobre la misma publicación y las mismas 8
Choice preguntas, devolviendo una distribución por pregunta.
Cada consulta también recibe un uid fresco, un valor único desechable que cambia en cada ejecución mientras
se mantienen sin cambios la publicación y la rúbrica. Aparece en el prompt del LLM y como un campo adicional
en el estado de TypeSafe. Esta configuración no puede separar la sensibilidad al campo irrelevante
de la variación que ocurriría en solicitudes idénticas.
Cada asistente devuelve la respuesta, un costo estimado y la latencia de ida y vuelta.
def argmax_label(values: list, labels: list[str]) -> str | None:
    """The label with the most probability mass, or ``None`` if any value is missing or
    non-numeric -- a partially parsed distribution never yields a confident-looking pick."""
    numeric = [_numeric_value(value) for value in values]
    if any(value is None for value in numeric):
        return None
    return labels[int(np.argmax(numeric))]


def choice_decision_with_uncertainty(values: list, labels: list[str]) -> str | None:
    """Abstain below the action threshold; retain invalid results as parse failures."""
    label = argmax_label(values, labels)
    if label is None:
        return None
    probabilities = [float(value) for value in values]
    if any(value < 0 or value > 1 for value in probabilities):
        return None
    return label if max(probabilities) >= MIN_CHOICE_PROBABILITY else "uncertain"


def choice_decision_annotation(values: list, labels: list[str]) -> str:
    """Show the application decision and top probability in a heatmap cell."""
    decision = choice_decision_with_uncertainty(values, labels)
    if decision is None:
        return ""
    probability = max(float(value) for value in values)
    probability_text = f"{probability:.2f}".removeprefix("0")
    return f"{decision} {probability_text}"


def _numeric_value(value: object) -> float | None:
    """A finite numeric value, or ``None`` if the model emitted something unusable."""
    try:
        numeric = float(value)
    except (TypeError, ValueError):
        return None
    return numeric if np.isfinite(numeric) else None


def parse_distribution(raw: object, labels: list[str]) -> list[float]:
    """Map a model's already-parsed per-question reply to per-label probabilities, in label order
    (distribution-mode answers left un-normalized).

    A single-pick reply is a single label string -> all the mass on that exact label; a
    distribution-mode reply is a dict read label by label. Anything that doesn't match a known label
    or isn't a finite number is left NaN -- we report the gap rather than massaging the reply (e.g.
    stripping an echoed description) to make it fit."""
    if isinstance(raw, str):  # single-pick mode: a single chosen label
        if raw in labels:
            return [1.0 if label == raw else 0.0 for label in labels]
        return [float("nan")] * len(labels)
    if not isinstance(raw, dict):
        return [float("nan")] * len(labels)
    return [
        value if (value := _numeric_value(raw.get(label))) is not None else float("nan")
        for label in labels
    ]


def rubric_prompt(mode: str, sample_index: int, rubric_hash: str) -> str:
    """The post + all questions (with their label sets) in one prompt; ``mode`` picks the format.

    ``mode="dist"`` asks for a probability distribution over each question's labels; the single-pick
    mode (``mode="single"``) asks for a single label per question. The uid line combines
    ``rubric_hash`` (which rubric version) with ``sample_index`` and a random token, so every repeat
    is a distinct, independent draw and two different rubrics never share a nonce."""
    lines = []
    for key, (instructions, choices) in QUESTIONS.items():
        labels = "\n".join(f"     {label}: {desc}" for label, desc in choices.items())
        lines.append(f"- {key}: {instructions}\n   labels:\n{labels}")
    exclusivity = (
        "\n\nEach question's labels are mutually exclusive: exactly one applies. If a post could "
        "arguably fit more than one, pick the single most severe / most specific label per the "
        "label descriptions."
    )
    if mode == "single":
        answer_format = (
            "\n\nFor each question, pick exactly ONE label.\nRespond with ONLY a JSON object "
            "mapping each question's key to one of that question's bare labels (the label only, "
            "not its description), with one entry per question."
        )
    else:
        answer_format = (
            "\n\nFor each question, give a probability distribution over that question's labels "
            "(values 0.00-1.00 that sum to 1).\nRespond with ONLY a JSON object mapping each "
            "question's key to an object mapping that question's bare labels (the label only, "
            "not its description) to probabilities, with one entry per question."
        )
    return (
        f"uid: {rubric_hash}:{sample_index}:{token_hex(4)}\n\n"
        f"Document (a reported user post):\n{json.dumps(POST, indent=2)}\n\nQuestions:\n"
        + "\n".join(lines)
        + exclusivity
        + answer_format
    )


def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]


def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started


# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering is instant and reproduces the published numbers with no API spend. ``sample_index``
# seeds the uid buster and is part of the cache key, so each of the NUM_SAMPLES repeats is its own
# entry and its own independent draw, not one draw replayed. Delete ``json_cache.json`` to re-sample
# everything live.
json_cache = JsonCache(Path("json_cache.json"))


def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text and label set. Passed into the cached calls below so that editing the post or any question
    changes the cache key and forces a fresh sample, instead of silently serving a stale answer that
    was generated for the old wording."""
    payload = json.dumps([POST, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]


RUBRIC_HASH = _rubric_fingerprint()


@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return distributions, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{rubric_hash}:{sample_index}:{token_hex(4)}", "post": POST},
        questions=questions,
    )
    distributions = {}
    for key, (_instructions, choices) in QUESTIONS.items():
        probabilities = dict(response.answers[key].probabilities)
        distributions[key] = [
            probabilities.get(label, float("nan")) for label in choices
        ]
    return (
        distributions,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )


@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question label distributions keyed by question key, cost_usd,
    latency_s); NaNs if the reply doesn't parse.

    ``mode="dist"`` parses 8 label distributions; the single-pick mode (``mode="single"``) parses 8
    single labels and puts all the mass on each. ``rubric_hash`` goes into the prompt's uid nonce
    (and so the cache key), so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index, rubric_hash)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 sometimes adds one despite "ONLY a JSON
    # object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    if not isinstance(raw, dict):
        raw = {}
    distributions = {
        key: parse_distribution(raw.get(key), list(choices))
        for key, (_instructions, choices) in QUESTIONS.items()
    }
    return distributions, cost, latency
Condiciones experimentales
Cuadrícula de experimentos
| Grupo de modelos | Modelo | Distribución (t=0) | Distribución (predeterminada) | Elección única (t=0) |
|---|---|---|---|---|
| Modelos sin razonamiento | claude-haiku-4-5 |
✓ | ✓ | ✓ |
| Modelos sin razonamiento | gpt-5.4-mini |
✓ | ✓ | ✓ |
| Modelos con razonamiento | gpt-5.5 |
— | ✓ | — |
| Modelos con razonamiento | claude-opus-4-8 |
— | ✓ | — |
| TypeSafe | jev-latest (typesafe_choice) |
— | ✓ | — |
- Un
✓indica una condición probada con 15 repeticiones; un—indica una combinación que no está probada. - La columna predeterminada no envía el argumento de temperatura: los modelos no razonadores usan el valor predeterminado de la API, y los modelos razonadores y TypeSafe se ejecutan sin configuración de temperatura.
- Las condiciones de selección única devuelven una etiqueta por pregunta.
- La temperatura
0se sugiere comúnmente para la repetibilidad, por lo que se compara con el valor predeterminado de la API.
Dibujamos NUM_SAMPLES = 15 repeticiones por condición. Cada repetición tiene su propia clave de caché y cuenta como un dibujo distinto, y la caché (json_cache.json) se incluye con el libro de recetas, por lo que el re-renderizado la reutiliza y no realiza llamadas a API. Elimina la caché para volver a muestrear en vivo.
CONDITIONS = []
for (
    model
) in BASE_MODELS:  # non-reasoning models: dist at t=0 / default, then a single-pick variant
    for temp_value, temp_label in ((0, "0"), (None, "default")):
        CONDITIONS.append(
            {
                "label": f"{model} t={temp_label}",
                "model": model,
                "temp": temp_value,
                "mode": "dist",
            }
        )
    CONDITIONS.append(
        {
            "label": f"{model} single-pick t=0",
            "model": model,
            "temp": 0,
            "mode": "single",
        }
    )
CONDITIONS += [  # reasoning models: one distribution condition each
    {
        "label": f"{model}-reasoning",
        "model": model,
        "temp": None,
        "mode": "dist",
    }
    for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]
TYPESAFE_LABEL = "typesafe_choice"
ALL_LABELS = [*LABELS, TYPESAFE_LABEL]

runs: dict[
    str, list
] = {}  # label -> NUM_SAMPLES samples of {question key: distribution}
stats: dict[str, list] = {}  # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
    futures = {
        condition["label"]: [
            pool.submit(
                ask_llm_rubric,
                condition["model"],
                condition["mode"],
                condition["temp"],
                sample_index,
                RUBRIC_HASH,
            )
            for sample_index in range(NUM_SAMPLES)
        ]
        for condition in CONDITIONS
    }
    for label, sample_futures in futures.items():
        results = [future.result() for future in sample_futures]
        runs[label] = [result[0] for result in results]
        stats[label] = [(result[1], result[2]) for result in results]

# TypeSafe samples are drawn sequentially, after the LLM pool has closed, so each call's latency is a
# clean round trip rather than one measured under the 16-way LLM thread contention.
typesafe_usage_results = [
    _call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
    for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
    result[4]["response_model"]
    for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
    (distributions, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
    for distributions, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats[TYPESAFE_LABEL] = [(result[1], result[2]) for result in typesafe_results]
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}Coste + velocidad (por consulta de rúbrica)
Los costos a continuación utilizan las suposiciones de precio históricas en Setup, incluyendo la tasa speed_latest para TypeSafe. No son precios jev-latest verificados ni montos de facturación actuales.
Una fila es una llamada completa de rúbrica de 8 preguntas. time/call y cost/call promedian las 15 llamadas, y las columnas vs ts_choice dividen por las cifras de TypeSafe. Los LLMs se ejecutan en un pool de 16 vías.
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_choice"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_choice"]])
name_w = max(len(name) for name in ALL_LABELS) + 2  # fit the longest condition label
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
    f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
    f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
    f"{'ts_choice':>11}{'ts_choice':>11}"
)
for name in ALL_LABELS:
    costs, latencies = zip(*stats[name])
    cost = mean(costs)
    latency = mean(latencies)
    print(
        f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
        f"{'$' + format(cost, '.6f'):>13}"
        f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
        f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
    )
speed vs cost vs
condition calls time/call cost/call ts_choice ts_choice
claude-haiku-4-5 t=0 15 3853ms $0.003498 33.8x 76.1x
claude-haiku-4-5 t=default 15 3860ms $0.003494 33.8x 76.0x
claude-haiku-4-5 single-pick t=0 15 992ms $0.001527 8.7x 33.2x
gpt-5.4-mini t=0 15 2293ms $0.002299 20.1x 50.0x
gpt-5.4-mini t=default 15 1986ms $0.002164 17.4x 47.1x
gpt-5.4-mini single-pick t=0 15 826ms $0.000936 7.2x 20.3x
gpt-5.5-reasoning 15 12978ms $0.041255 113.7x 897.4x
claude-opus-4-8-reasoning 15 10376ms $0.028375 90.9x 617.2x
typesafe_choice 15 114ms $0.000046 1.0x 1.0xEn esta ejecución typesafe_choice tiene una latencia de ida y vuelta media de 114ms. Las condiciones de LLM oscilan entre 826ms y 13,0 segundos por llamada bajo los ajustes de concurrencia anteriores.
Trama: la decisión de cada muestra como mapa de calor
Cómo leerlo:
- Grupo de filas exterior: la pregunta.
- Fila interior: la condición.
- Columna: una llamada completa de rúbrica.
- Texto de celda: la decisión de la aplicación más la probabilidad en la etiqueta superior.
- Color de celda: la posición de la etiqueta dentro de esa pregunta, por lo que el mismo color a lo largo de una fila significa la misma decisión cada vez.
- Gris
uncertain: la probabilidad superior está por debajo de0.60, por lo que el caso pasa a revisión humana. - Rayado
n/a: la respuesta no se analizó en etiquetas utilizables (un error de análisis). - Las filas en blanco son solo separadores.
Las condiciones de selección única mantienen sus etiquetas devueltas: no proporcionan ninguna estimación de incertidumbre.
GAP = 1  # blank spacer row(s) between question blocks
HEAT_LABELS = ALL_LABELS
rows_per_block = len(HEAT_LABELS)  # rows per question block
pooled_runs = {
    **runs,
    TYPESAFE_LABEL: typesafe_runs,
}

row_index_values, row_text, row_labels, blocks = [], [], [], []
for question_index, (question_key, (question_text, choices)) in enumerate(
    QUESTIONS.items()
):
    labels = list(choices)
    if question_index:  # blank spacer rows (NaN -> rendered white) separate the blocks
        row_index_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
        row_text.extend([[""] * NUM_SAMPLES for _ in range(GAP)])
        row_labels.extend([""] * GAP)
    blocks.append((len(row_index_values), question_key, question_text))
    for label in HEAT_LABELS:
        values_by_sample = [
            pooled_runs[label][sample][question_key] for sample in range(NUM_SAMPLES)
        ]
        picks = [
            choice_decision_with_uncertainty(values, labels) for values in values_by_sample
        ]
        row_index_values.append(
            [
                10 if pick == "uncertain" else labels.index(pick) if pick in labels else np.nan
                for pick in picks
            ]
        )
        row_text.append(
            [choice_decision_annotation(values, labels) for values in values_by_sample]
        )
        row_labels.append(label)

heatmap_matrix = np.array(row_index_values, dtype=float)
# Reserve gray for abstentions while concrete-label colors remain local to each question.
cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
cmap.set_bad(
    "white"
)  # NaN cells (spacer rows AND unparseable replies) render white here...

fig, ax = plt.subplots(figsize=(15, 0.33 * len(row_index_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=10, aspect="auto")
for row in range(heatmap_matrix.shape[0]):
    is_spacer_row = row_labels[row] == ""  # blank separator between question blocks
    for col in range(heatmap_matrix.shape[1]):
        label_text = row_text[row][col]
        if label_text:
            ax.text(
                col,
                row,
                label_text,
                ha="center",
                va="center",
                fontsize=5.7,
                family="monospace",
                color="black",
            )
        elif (
            not is_spacer_row
        ):  # ...but an unparseable reply gets a hatched "n/a", not blank white
            ax.add_patch(
                plt.Rectangle(
                    (col - 0.5, row - 0.5),
                    1,
                    1,
                    facecolor="#e8e8e8",
                    edgecolor="#b0b0b0",
                    hatch="////",
                    linewidth=0,
                )
            )
            ax.text(
                col,
                row,
                "n/a",
                ha="center",
                va="center",
                fontsize=5,
                family="monospace",
                color="#b30000",
            )

ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
    ax.spines[edge].set_visible(False)

# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
    center = start + (rows_per_block - 1) / 2
    ax.text(
        -0.2,
        center - 0.7,
        question_key,
        transform=y_axis_transform,
        ha="right",
        va="center",
        fontsize=8,
        fontweight="bold",
    )
    ax.text(
        -0.2,
        center + 0.1,
        textwrap.fill(question_text, 34),
        transform=y_axis_transform,
        ha="right",
        va="top",
        fontsize=6,
        style="italic",
        color="gray",
    )

ax.set_title(
    f"Every sample's decision + top probability; gray = uncertain (< {MIN_CHOICE_PROBABILITY:.2f})\n"
    f"(rows = question x condition, {NUM_SAMPLES} columns)",
    pad=12,
)
fig.tight_layout()
display(fig)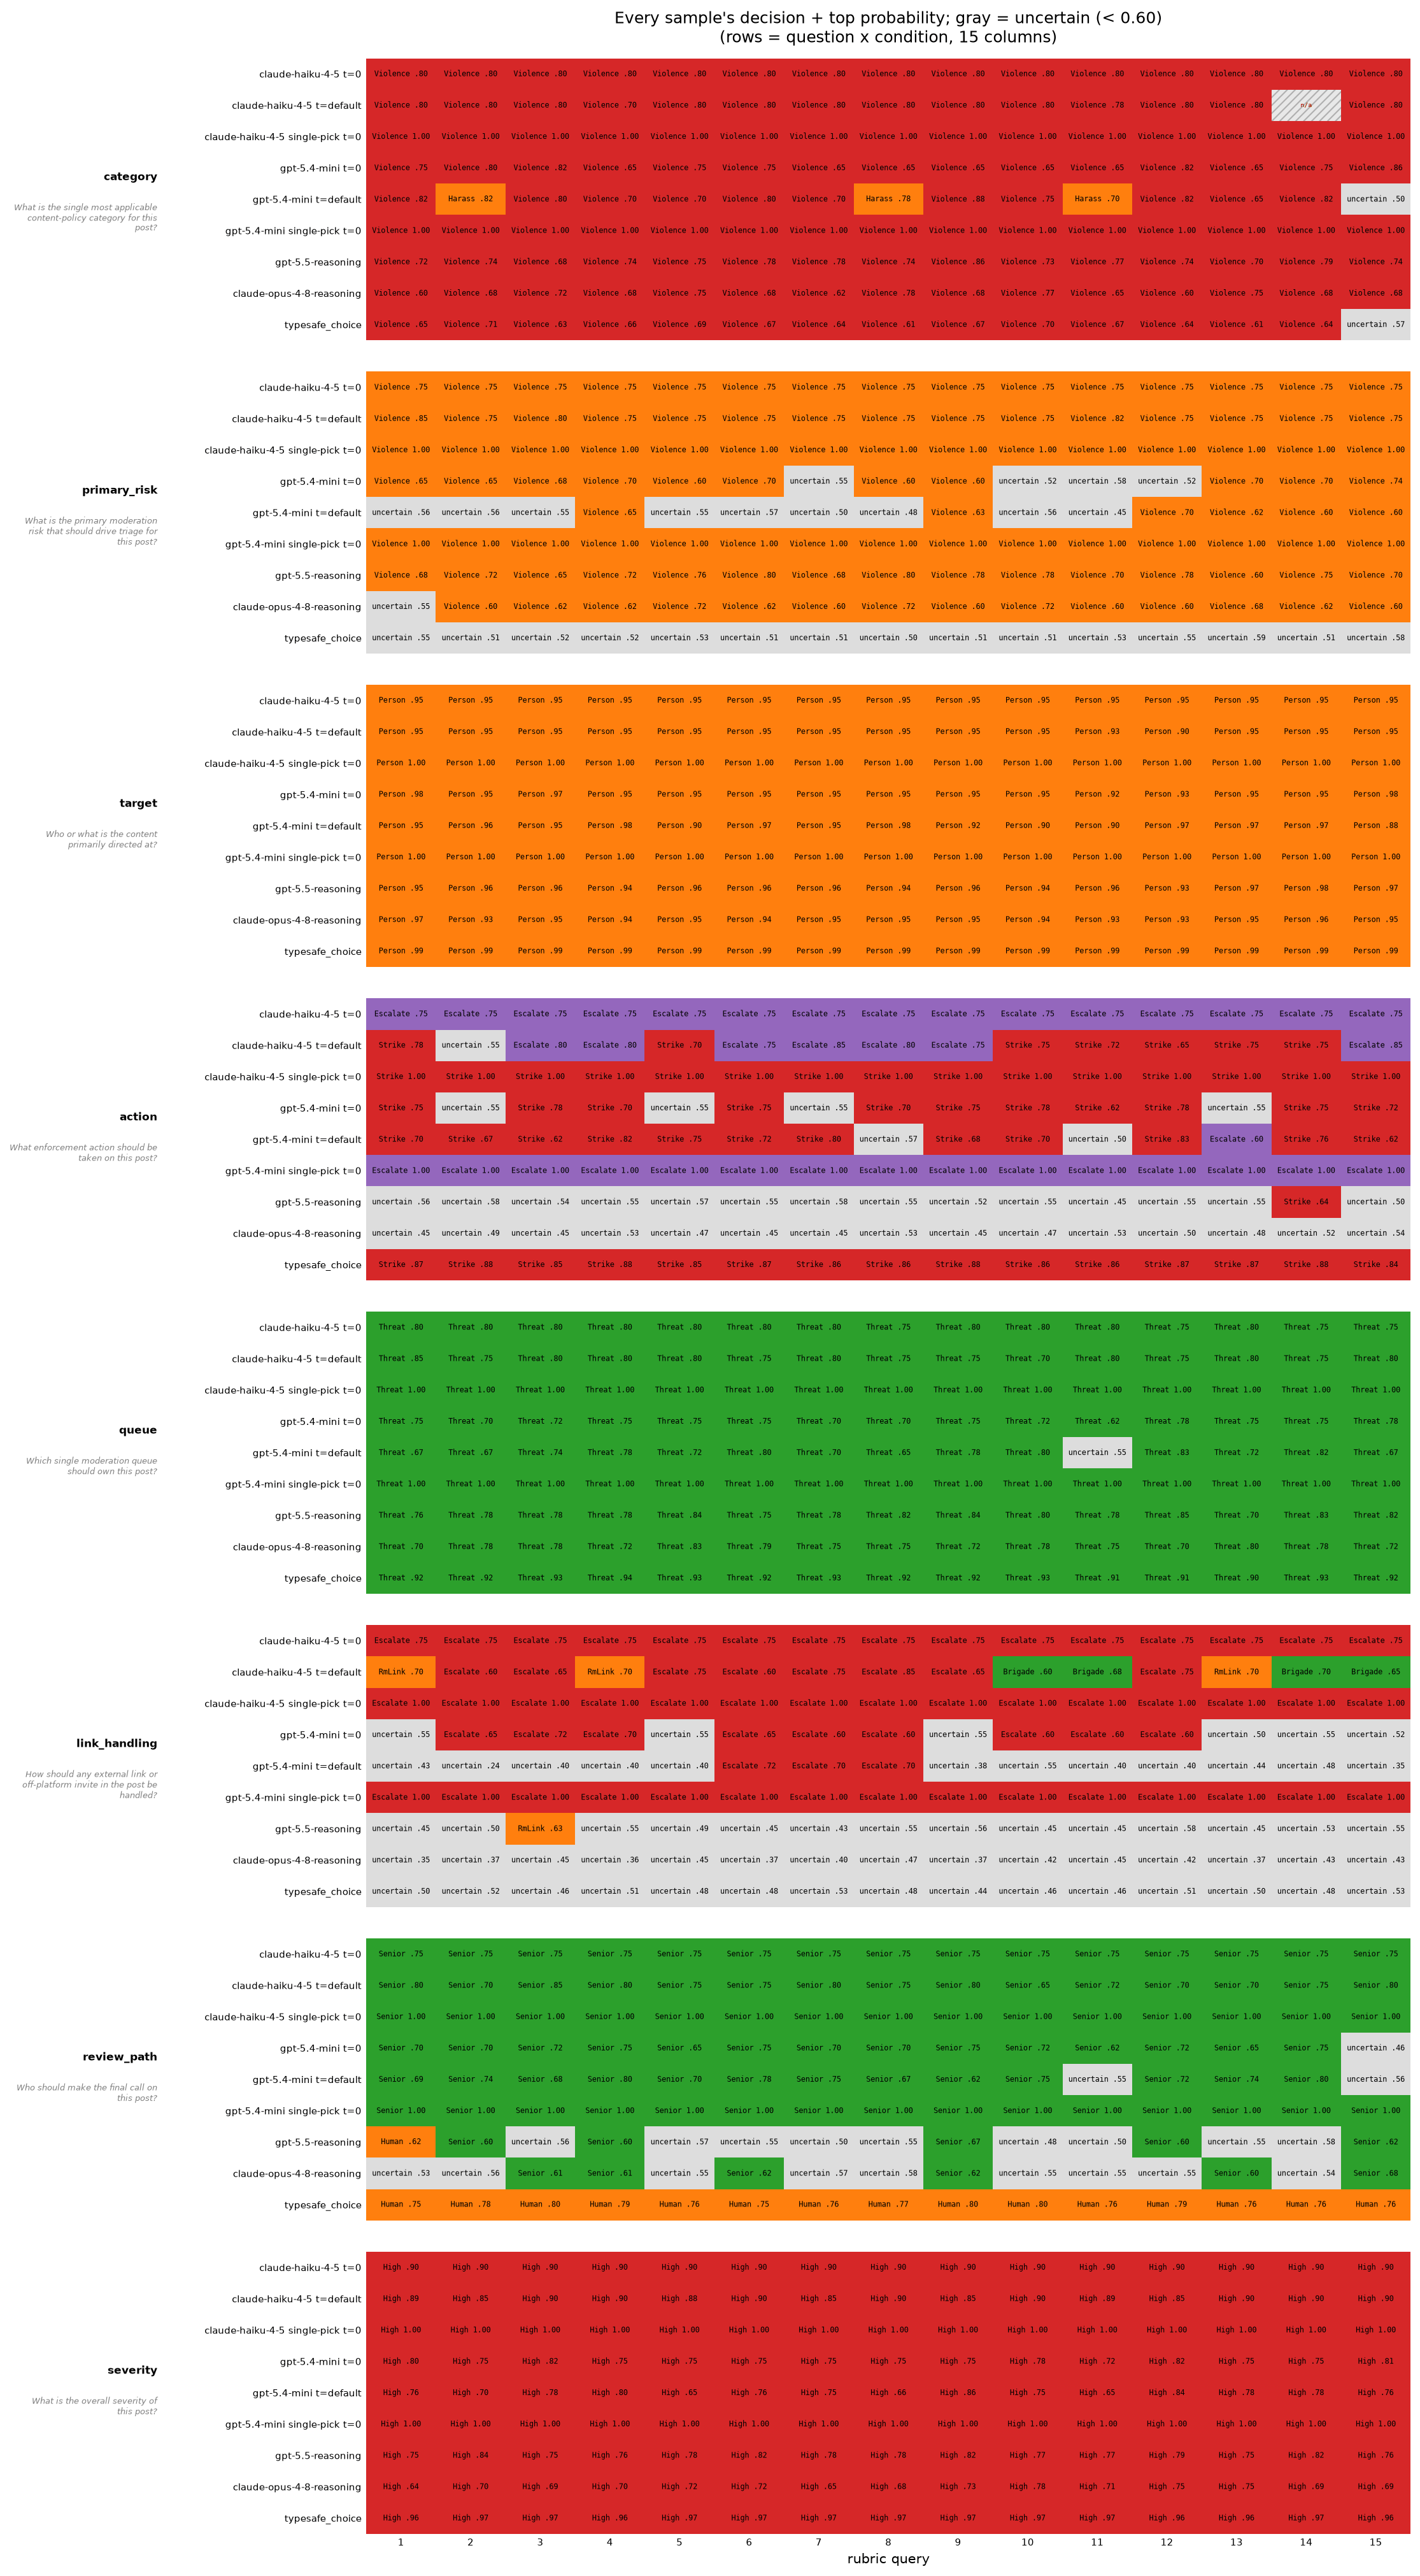
Las preguntas más claras se mantienen estables: target lee Persona y severity lee Alta en todas partes. Las limítrofes se dividen entre las condiciones: category, primary_risk,
action, review_path, y link_handling. Algunas condiciones también cambian dentro de sus
15 repeticiones propias. Antes de la abstención, TypeSafe cambia su etiqueta principal en primary_risk
(Acoso 11 veces, Violencia 4 veces) y link_handling (RmLink 8 veces, Brigade 7
veces). Ambas filas ahora muestran uncertain en todo momento porque sus probabilidades principales son
inferiores a 0.60.
Desviación estándar de probabilidad
Esto analiza los vectores de probabilidad completos, no solo la etiqueta seleccionada. Para cada condición, recopilamos las 15 distribuciones para cada pregunta, calculamos la desviación estándar de la probabilidad de cada etiqueta a través de las repeticiones (cuánto cambia de una ejecución a otra), y luego promediamos esas desviaciones estándar sobre todas las etiquetas y preguntas. También informamos la desviación estándar más grande de una sola etiqueta, y contamos los fallos de análisis por separado.
La tabla compara cada condición de LLM de salida de probabilidades frente a TypeSafe. Las filas de selección única se omiten, ya que emiten etiquetas definitivas en lugar de distribuciones de probabilidad.
def probability_std_stats(samples: list) -> tuple[float, float, float]:
    """Mean label std dev, max label std dev, parse-failure rate."""
    label_stds = []
    parse_failures = []
    for question_key in QUESTIONS:
        arr = np.array(
            [sample[question_key] for sample in samples],
            dtype=float,
        )
        parse_failures.extend(np.isnan(arr).any(axis=1).tolist())
        label_stds.extend(np.nanstd(arr, axis=0).tolist())
    return (
        float(np.nanmean(label_stds)),
        float(np.nanmax(label_stds)),
        float(np.mean(parse_failures)),
    )


PROBABILITY_OUTPUT_LABELS = [
    condition["label"] for condition in CONDITIONS if condition["mode"] == "dist"
] + [TYPESAFE_LABEL]
probability_std_by_label = {
    label: probability_std_stats(pooled_runs[label])
    for label in PROBABILITY_OUTPUT_LABELS
}
typesafe_mean_std = probability_std_by_label[TYPESAFE_LABEL][0]

print(
    f"{'condition':<{name_w}}{'mean prob std':>15}{'max prob std':>14}"
    f"{'parse fail':>12}{'x TypeSafe':>12}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    mean_std, max_std, parse_failure_rate = probability_std_by_label[label]
    relative_std = mean_std / typesafe_mean_std
    print(
        f"{label:<{name_w}}{mean_std:>15.4f}{max_std:>14.4f}"
        f"{parse_failure_rate:>11.0%}{relative_std:>12.2f}x"
    )
condition mean prob std max prob std parse fail x TypeSafe
claude-haiku-4-5 t=0 0.0012 0.0221 0% 0.12x
claude-haiku-4-5 t=default 0.0516 0.3150 1% 5.29x
gpt-5.4-mini t=0 0.0312 0.0905 0% 3.20x
gpt-5.4-mini t=default 0.0543 0.2303 0% 5.56x
gpt-5.5-reasoning 0.0305 0.1047 0% 3.12x
claude-opus-4-8-reasoning 0.0245 0.0693 0% 2.52x
typesafe_choice 0.0098 0.0515 0% 1.00xEn esta ejecución, TypeSafe tiene una desviación estándar media de probabilidad de 0.0098 y una desviación estándar máxima de etiqueta única de 0.0515. Haiku a temperatura 0 tiene una desviación estándar media más baja de 0.0012. Las otras cinco condiciones de probabilidad de LLM oscilan entre 0.0245 y 0.0543, aproximadamente 2.5x a 5.6x la media de TypeSafe. Los pequeños cambios aún pueden cambiar la etiqueta principal cuando dos etiquetas están cerca.
Trama: acuerdo de decisión con un resultado incierto
Devuelve uncertain cuando la probabilidad más alta esté por debajo de 0.60. Para cada condición de salida de probabilidad y pregunta, cuenta la decisión de aplicación más común, incluyendo uncertain, y divídela por los 15 sorteos. Los fallos de análisis se cuentan como desacuerdo. Cada barra promedia la puntuación en las 8 preguntas, con el acuerdo más alto primero.
Las condiciones de LLM de selección única están excluidas porque no proporcionan ninguna estimación de incertidumbre.
# Compute policy decisions and agreement once for both this chart and the comparison table.
decisions_by_condition = {}
policy_agreement_by_condition = {}
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = [
        [
            choice_decision_with_uncertainty(sample[key], list(choices))
            for sample in pooled_runs[label]
        ]
        for key, (_instructions, choices) in QUESTIONS.items()
    ]
    decisions_by_condition[label] = decisions
    shares = [
        max(Counter(value for value in row if value is not None).values(), default=0)
        / NUM_SAMPLES
        for row in decisions
    ]
    policy_agreement_by_condition[label] = mean(shares)

# Sort by the measured agreement, keeping TypeSafe's color independent of its rank.
bar_labels = sorted(
    PROBABILITY_OUTPUT_LABELS, key=policy_agreement_by_condition.__getitem__, reverse=True
)
rates = [policy_agreement_by_condition[label] for label in bar_labels]

fig_bar, bar_ax = plt.subplots(figsize=(7, 0.45 * len(bar_labels) + 1))
positions = range(len(bar_labels))
bar_ax.barh(
    list(positions),
    rates,
    color=["#2b8cbe" if label == TYPESAFE_LABEL else "#fe9929" for label in bar_labels],
    alpha=0.85,
)
for label, position, rate in zip(bar_labels, positions, rates):
    marker = "*" if label == "claude-haiku-4-5 t=0" else ""
    bar_ax.text(
        rate + 0.01, position, f"{rate:.1%}{marker}", va="center", fontsize=8, color="gray"
    )
bar_ax.set_yticks(list(positions))
bar_ax.set_yticklabels(bar_labels, fontsize=8)
bar_ax.invert_yaxis()  # first condition on top
bar_ax.set_xlim(0, 1.08)
bar_ax.set_xticks(np.linspace(0, 1, 6))
bar_ax.set_xlabel("decision agreement across 15 re-runs (mean over 8 questions)")
for edge in ("top", "right", "left"):
    bar_ax.spines[edge].set_visible(False)
bar_ax.tick_params(length=0)
fig_bar.suptitle("Decision agreement including uncertain outcomes", y=1.0)
# Keep the caveat inside the exported chart so it travels with the 100% annotation.
fig_bar.text(
    0.01,
    0.01,
    "* Haiku t=0: 100% repeatability does not imply correctness.\n"
    "  This experiment does not measure accuracy.",
    fontsize=8,
)
fig_bar.tight_layout(rect=(0, 0.11, 1, 1))
display(fig_bar)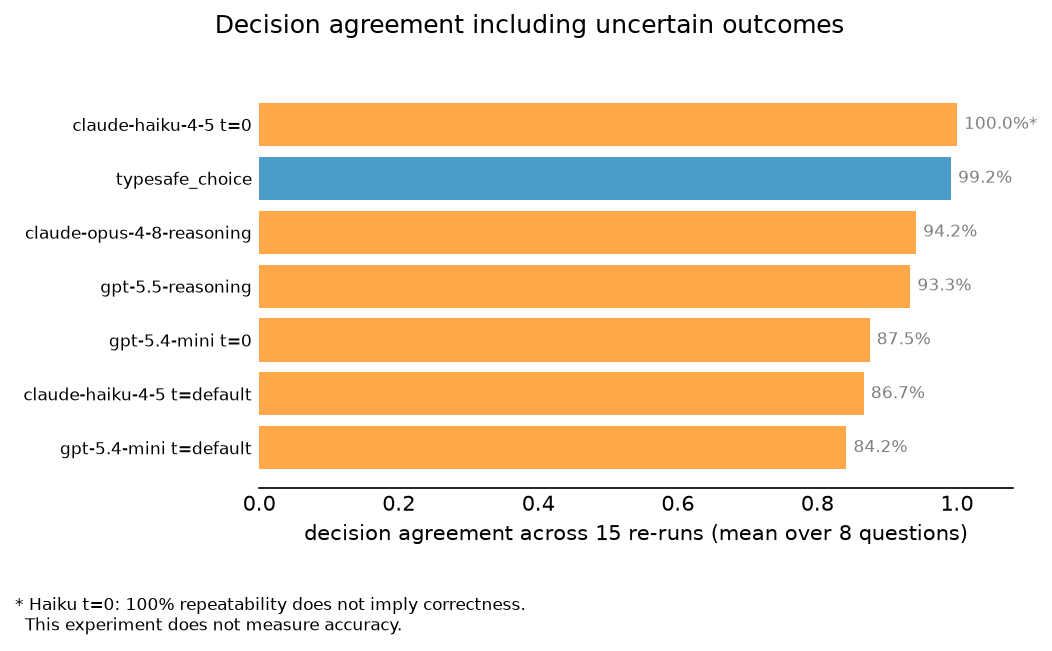
Bajo la misma regla 0.60, Haiku a temperatura 0 obtuvo un 100%. TypeSafe obtuvo un 99,2%, y las otras condiciones de LLM se situaron entre el 84,2% y el 94,2%. TypeSafe devolvió uncertain en el 25,8% de las respuestas y actuó automáticamente en el otro 74,2%; Haiku a temperatura 0 nunca se abstuvo. Estos porcentajes miden únicamente la repetibilidad. La siguiente tabla establece las tasas de acuerdo crudo y abstención junto con el acuerdo de políticas en este gráfico.
Que las probabilidades inciertas produzcan una decisión incierta
Un pequeño cambio de probabilidad puede intercambiar dos etiquetas cercanas. La aplicación no tiene que actuar sobre la ganadora: devolver uncertain cuando la probabilidad superior esté por debajo de 0.60, y enviar ese caso a un humano. En exactamente 0.60, seleccionar la etiqueta superior. Esto utiliza las probabilidades devueltas, no el campo confidence separado de API, y no añade llamadas al modelo.
El umbral es una política de aplicación ilustrativa, no una garantía calibrada ni un umbral elegido para maximizar el acuerdo de esta ejecución. Elige umbrales de producción usando ejemplos etiquetados y el costo de las acciones incorrectas y la revisión humana.
Aplicamos la misma regla a cada condición de salida de probabilidad. Las respuestas de LLM de selección única no tienen estimación de probabilidad; sus vectores one-hot sintéticos no pueden medir la incertidumbre, por lo que se excluyen del gráfico y la tabla de acuerdo.
def agreement_rate(samples: list) -> float:
    """Mean over questions of the raw plurality label's share across all NUM_SAMPLES draws.

    Parse failures count against agreement because a failed route is not a repeated decision.
    """
    shares = []
    for question_key, (_instructions, choices) in QUESTIONS.items():
        labels = list(choices)
        picks = [
            argmax_label(samples[sample][question_key], labels)
            for sample in range(NUM_SAMPLES)
        ]
        picks = [pick for pick in picks if pick is not None]
        if not picks:
            shares.append(0.0)
            continue
        top = Counter(picks).most_common(1)[0][1]
        shares.append(top / NUM_SAMPLES)
    return mean(shares) if shares else float("nan")


# Keep failures separate from abstentions and count conflicting concrete actions per question.
print(
    f"{'condition':<{name_w}}{'raw agree':>12}{'policy agree':>14}"
    f"{'uncertain':>12}{'automatic':>12}{'conflicts':>11}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = decisions_by_condition[label]
    flat = [value for row in decisions for value in row]
    uncertain_rate = mean(value == "uncertain" for value in flat)
    automatic_rate = mean(value not in (None, "uncertain") for value in flat)
    conflicts = sum(
        len({value for value in row if value not in (None, "uncertain")}) > 1
        for row in decisions
    )
    print(
        f"{label:<{name_w}}{agreement_rate(pooled_runs[label]):>11.1%}"
        f"{policy_agreement_by_condition[label]:>13.1%}{uncertain_rate:>11.1%}"
        f"{automatic_rate:>11.1%}{conflicts:>11}"
    )
condition raw agree policy agree uncertain automatic conflicts
claude-haiku-4-5 t=0 100.0% 100.0% 0.0% 100.0% 0
claude-haiku-4-5 t=default 87.5% 86.7% 0.8% 98.3% 2
gpt-5.4-mini t=0 99.2% 87.5% 12.5% 87.5% 0
gpt-5.4-mini t=default 90.8% 84.2% 22.5% 77.5% 2
gpt-5.5-reasoning 90.0% 93.3% 30.8% 69.2% 1
claude-opus-4-8-reasoning 92.5% 94.2% 33.3% 66.7% 0
typesafe_choice 90.8% 99.2% 25.8% 74.2% 0policy agree cuenta uncertain como una decisión; los fallos de análisis cuentan contra el acuerdo.
automatic es la proporción de todas las respuestas que seleccionan una etiqueta. conflicts cuenta las preguntas
con más de una etiqueta concreta a través de las repeticiones, ignorando las abstenciones. Estas medidas
describen la repetibilidad y con qué frecuencia la aplicación actúa, no si sus acciones son
correctas.
El acuerdo de TypeSafe aumentó del 90,8 % al 99,2 %. De las respuestas, el 25,8 % fueron inciertas y
el 74,2 % automáticas. primary_risk y link_handling volvieron a ser inciertos en cada repetición;
category alternó entre Violence y uncertain, cruzando el umbral de acción en
algunas repeticiones y no en otras. Ninguna pregunta produjo dos etiquetas TypeSafe concretas diferentes.
Nada de esto muestra precisión o superioridad: Haiku a temperatura 0 tuvo un 100 % de acuerdo
aquí, sin abstenciones.
# Show every TypeSafe decision while retaining the top probability behind it.
policy_decisions = decisions_by_condition[TYPESAFE_LABEL]
policy_values = []
for row, (_key, (_instructions, choices)) in zip(policy_decisions, QUESTIONS.items()):
    labels = list(choices)
    policy_values.append([
        10 if value == "uncertain" else labels.index(value) if value is not None else np.nan
        for value in row
    ])
policy_cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
policy_cmap.set_bad("white")
fig_policy, ax_policy = plt.subplots(figsize=(13, 4))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=10, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
    for sample_index in range(NUM_SAMPLES):
        decision = policy_decisions[row_index][sample_index]
        probability = max(typesafe_runs[sample_index][key])
        ax_policy.text(sample_index, row_index, f"{decision or 'n/a'}\n{probability:.2f}",
                       ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
    "TypeSafe application decisions: gray means uncertain "
    f"(top probability < {MIN_CHOICE_PROBABILITY:.2f})"
)
fig_policy.tight_layout()
display(fig_policy)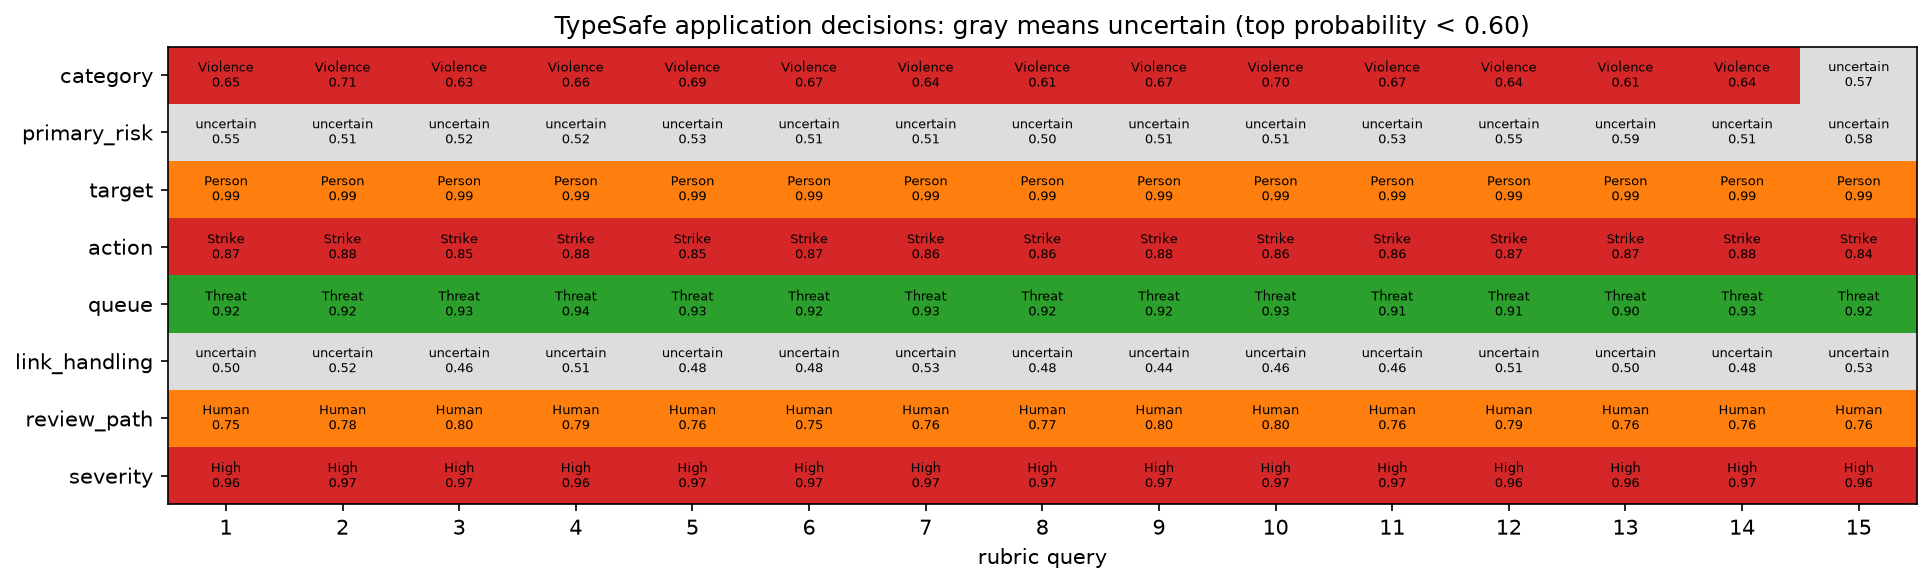
Esta política no hace que el modelo sea determinista. Abstenerse puede reemplazar etiquetas competitivas con el mismo resultado de revisión humana, pero una probabilidad cercana a 0.60 aún puede moverse entre una etiqueta concreta y uncertain. Las estadísticas de probabilidad y la columna raw agree de la tabla siguen informando las salidas originales del modelo.
Ábrelo en el playground de TypeSafe
El enlace de abajo abre la misma publicación y rúbrica en el playground: una publicación, los mismos 8
Choices, y TypeSafe jev-latest.
playground_link = make_playground_link(
    {"post": POST},
    {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this post + rubric in the TypeSafe playground]({playground_link})"
    )
)
Abrir esta publicación + rúbrica en el entorno de TypeSafe →