 JevCode
Pre-parsed value extraction
Uses regexes to find candidate emails, phone numbers, and amounts, then has TypeSafe select the requested span so code can normalize a verbatim value.

A regex finds the candidate values, TypeSafe picks the one the question asks for, and code copies it verbatim.
The find and pick pair here is one you can point at your own documents, and three
worked cases show it in use: the address a sender wants their receipt sent to, a phone
number as +14155550177, and an invoice total as 1315.50 USD flagged as a charge.
TypeSafe picks one of the options you hand it, so the candidates have to be found first. A regex finds them, TypeSafe picks one, and code copies the pick, in three steps:
- A regex finds the candidate values in the text. Tune it to over-find.
- TypeSafe picks which candidate the question is asking for, and reads off any attribute the code needs downstream (currency, country, whether an amount is a credit or a charge).
- The code copies the picked value and normalizes it.
Because TypeSafe only ever chooses among the spans the regex found, the value you get back is one of those spans, copied unchanged. It cannot invent a value or transpose a digit.
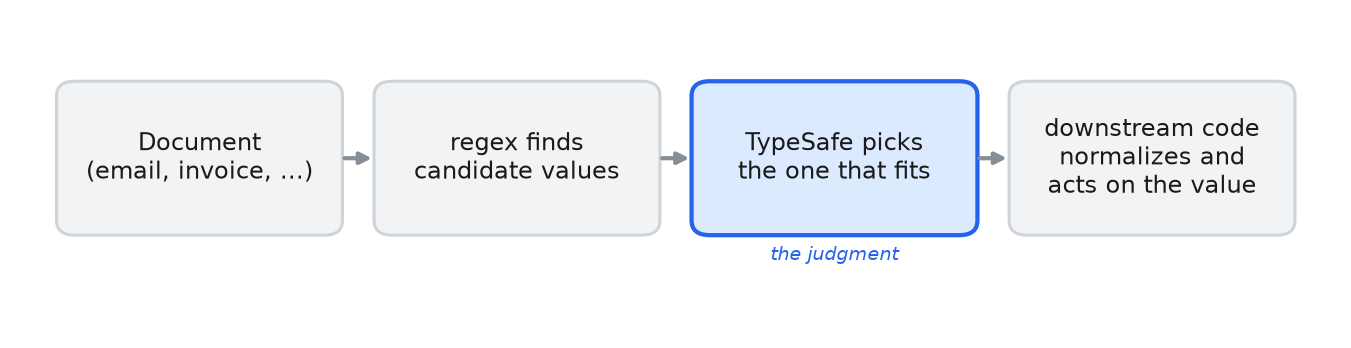
The regex finds candidate values in the document, TypeSafe picks one, and downstream code normalizes it and acts on it.
Setup
pip install ipython phonenumbers "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/then set TYPESAFE_API_KEY.
import os
import re
from decimal import Decimal
from pathlib import Path

import phonenumbers
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Choice, Noul, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
NONE = "none"  # the escape hatch on every selection: "none of the candidates fits"

# base_url defaults to https://api.typesafe.ai/ ; the env override points at another deployment.
ts = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # cached re-renders need no key
    base_url=os.environ.get("TYPESAFE_BASE_URL"),
    timeout=30.0,
)
json_cache = JsonCache(Path("json_cache.json"))
Helpers
find runs a regex tuned to over-find and dedupes the matches. pick is a
Choice question whose options are the spans find returns, so its answer is one of
those spans copied exactly, or none when no candidate fits. classify is a
Choice question over a fixed set of labels, used here for the currency and the
country.
is_true is a Noul, used here to ask whether an amount is a credit.
Every call is cached to json_cache.json, so re-rendering makes no API calls.
EMAIL_RE = re.compile(r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}")
PHONE_RE = re.compile(r"\(?\+?\d[\d\s()\-.]{6,}\d")
MONEY_RE = re.compile(r"[$€£¥]\s?\d[\d,]*(?:\.\d{2})?")


def find(pattern: re.Pattern, text: str) -> list[str]:
    """Code-side candidate finder: recall-tuned regex, deduped, in document order."""
    seen: set[str] = set()
    out: list[str] = []
    for match in pattern.findall(text):
        span = match.strip()
        if span and span not in seen:
            seen.add(span)
            out.append(span)
    return out


@json_cache
def pick(document: str, candidates: list[str], question: str) -> dict:
    """TypeSafe selects which found span plays the role. Returns {choice, confidence}.

    The options ARE the candidate spans, so ``choice`` is a verbatim copy of one of them (or the
    ``none`` hatch) - the model chooses, code owns the string."""
    criteria = {c: None for c in candidates} | {
        NONE: "None of these is the requested value."
    }
    answer = ts.system_one(
        state=document,
        questions={"pick": Choice(instructions=question, criteria=criteria)},
        model=TYPESAFE_MODEL,
    ).answers["pick"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def classify(document: str, question: str, options: list[str]) -> dict:
    """A small Choice over a fixed label set (currency, country, ...). Returns {choice, confidence}."""
    answer = ts.system_one(
        state=document,
        questions={
            "q": Choice(instructions=question, criteria={o: None for o in options})
        },
        model=TYPESAFE_MODEL,
    ).answers["q"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def is_true(document: str, question: str) -> float:
    """A yes/no Noul. Returns P(yes)."""
    return (
        ts.system_one(
            state=document,
            questions={"q": Noul(instructions=question)},
            model=TYPESAFE_MODEL,
        )
        .answers["q"]
        .noul
    )
Email: pick the right address by role
Four addresses in the headers. The body asks for the receipt to go to a personal
address instead of the To: billing alias, so the answer depends on reading the body.
Two questions here: which address gets the receipt, and which one sent the message.
EMAIL_DOC = """From: Dana Whit <[email protected]>
To: [email protected]
Cc: [email protected]
Reply-To: [email protected]

Hi team - please don't use the billing alias for this one. Send my receipt to my
personal address instead. Thanks, Dana."""

emails = find(EMAIL_RE, EMAIL_DOC)
receipt = pick(
    EMAIL_DOC, emails, "Which email address does the sender want their receipt sent to?"
)
sender = pick(
    EMAIL_DOC, emails, "Which email address did this message come from (the From line)?"
)

print("candidates :", emails)
# code copies the picked value verbatim and normalizes (lowercase); it never re-types it
print(
    f"receipt -> : {receipt['choice'].lower():<28} (conf {receipt['confidence']:.2f})"
)
print(f"sender  -> : {sender['choice'].lower():<28} (conf {sender['confidence']:.2f})")
candidates : ['[email protected]', '[email protected]', '[email protected]', '[email protected]']
receipt -> : [email protected] (conf 0.98)
sender -> : [email protected] (conf 1.00)receipt is the personal Gmail address on the Reply-To: line, which is what the body
asks for; sender is the one on the From line. Both are copies of regex matches,
lowercased in code.
Phone: pick the mobile, normalize to E.164
Three numbers, none of them carrying a country code. TypeSafe picks the mobile and
reads the country from the text; phonenumbers combines those two answers into E.164,
the international format that starts with a + and the country code.
PHONE_DOC = """Reach our San Francisco office at these numbers: main desk (415) 555-0199,
billing fax (415) 555-0142, and my direct cell (415) 555-0177. Call the cell if it's urgent."""

phones = find(PHONE_RE, PHONE_DOC)
mobile = pick(PHONE_DOC, phones, "Which of these is the direct mobile / cell number?")
region = classify(
    PHONE_DOC,
    "In what country is this office located?",
    ["US", "GB", "DE", "FR", "CA", "AU"],
)

# code copies the picked value and normalizes it with the model-supplied country
parsed = phonenumbers.parse(mobile["choice"], region["choice"])
e164 = phonenumbers.format_number(parsed, phonenumbers.PhoneNumberFormat.E164)

print("candidates :", phones)
print(f"mobile  -> : {mobile['choice']}  (conf {mobile['confidence']:.2f})")
print(f"country -> : {region['choice']}  (conf {region['confidence']:.2f})")
print(f"E.164   -> : {e164}")
candidates : ['(415) 555-0199', '(415) 555-0142', '(415) 555-0177']
mobile -> : (415) 555-0177 (conf 1.00)
country -> : US (conf 0.90)
E.164 -> : +14155550177Nothing in the digits says which number is the mobile or what country it is in; the
words around them do. TypeSafe reads those words, and phonenumbers formats the picked
number as +14155550177.
Money: pick the amount, classify the currency, flag credit vs charge
An invoice with four amounts on it. TypeSafe picks the total due and the credit, reads
the currency, and flags each picked amount as a charge or a credit. The code copies each
picked string and parses it into a Decimal.
MONEY_DOC = """Invoice INV-2087.
Subtotal: $1,200.00
Sales tax: $115.50
Total due: $1,315.50
A $50.00 courtesy credit from last month has already been applied."""

amounts = find(MONEY_RE, MONEY_DOC)
currency = classify(
    MONEY_DOC,
    "What currency are these amounts in?",
    ["USD", "EUR", "GBP", "JPY", "CAD"],
)
total = pick(MONEY_DOC, amounts, "Which amount is the total the customer must pay?")
credit = pick(
    MONEY_DOC, amounts, "Which amount is the courtesy credit that was applied?"
)


def to_decimal(value: str) -> Decimal:
    """Copy the picked value and parse the number in code (US grouping/decimal here)."""
    return Decimal(re.sub(r"[^\d.]", "", value))


for label, chosen in [("total due", total), ("credit", credit)]:
    is_credit = is_true(
        MONEY_DOC,
        f"Is the amount {chosen['choice']} a credit or refund to the customer, not a charge?",
    )
    kind = "credit" if is_credit > 0.5 else "charge"
    print(
        f"{label:<10}: {chosen['choice']:<10} -> {to_decimal(chosen['choice'])} {currency['choice']} "
        f"({kind}, P(credit)={is_credit:.2f})"
    )
print("\ncandidates :", amounts)
total due : $1,315.50 -> 1315.50 USD (charge, P(credit)=0.01)
credit : $50.00 -> 50.00 USD (credit, P(credit)=0.99)
candidates : ['$1,200.00', '$115.50', '$1,315.50', '$50.00']The total due is $1,315.50 and the credit is $50.00, both in USD. The credit-or-charge
Noul answers 0.01 on the total and 0.99 on the credit, so the code knows the
sign of each Decimal it parses.
to_decimalassumes the comma groups thousands and the dot is the decimal point. That holds for$1,315.50; in€1.315,50it is the other way round. Ask aNoulquestion which convention the document uses, and branch on it in code.
Open it in the TypeSafe playground
A share link that opens the email thread in the browser, with the receipt question on it and the four addresses the regex found among its options.
receipt_criteria = {e: None for e in emails} | {
    NONE: "None of these is the requested value."
}
playground_link = make_playground_link(
    EMAIL_DOC,
    {
        "receipt": Choice(
            instructions="Which email address does the sender want their receipt sent to?",
            criteria=receipt_criteria,
        )
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this thread + selection in the TypeSafe playground]({playground_link})"
    )
)
Open this thread + selection in the TypeSafe playground →
Two limits
- A
Choicequestion allows at most 255 options. With more candidates than that, narrow in two stages: pick the section first, then the span inside it. - Finding the candidates is the part that takes work. Emails, phone numbers and amounts have regexes that cover them; a name does not, so its candidates have to come from a roster you already have, or from a named-entity recognizer or an LLM that proposes them. TypeSafe then picks the one the question asks for.