 JevCode
预解析值提取
使用正则表达式查找候选电子邮件、电话号码和金额,然后由 TypeSafe 选择所需的文本片段,以便代码对原始值进行规范化处理。
本文由机器翻译自 en,未经人工校对,仅供快速参考。

正则表达式用于查找候选值,TypeSafe 根据问题选出目标值,代码则将其原文复制出来。
这里的 find 和 pick 配对机制可应用于你自己的文档,以下三个具体案例展示了其用法:发件人希望收据发送至的地址、格式为 +14155550177 的电话号码,以及标记为费用的发票总额 1315.50 USD。
TypeSafe 会从你提供的选项中选择一个,因此必须先找到候选值。具体流程分为三步:正则表达式查找候选值,TypeSafe 进行选择,代码执行复制操作:
- 正则表达式在文本中查找候选值。调整正则表达式以尽可能多地匹配(宁可多找,不可漏找)。
- TypeSafe 选出问题所询问的候选值,并读取下游代码所需的任何属性(如货币、国家、金额是贷方还是借方)。
- 代码复制选定的值并进行标准化处理。
由于 TypeSafe 仅在正则表达式找到的片段中进行选择,因此你得到的返回值就是这些片段之一,且未经任何修改。它不会凭空捏造值,也不会颠倒数字顺序。
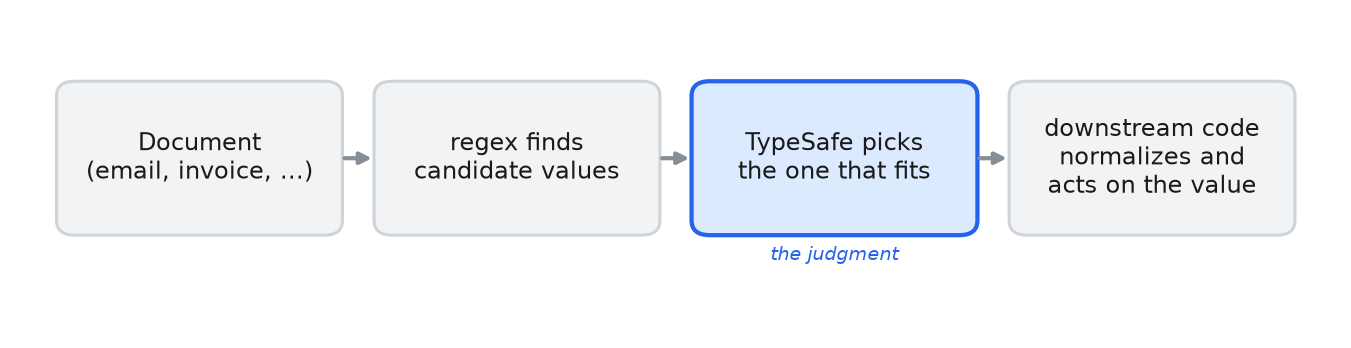
正则表达式在文档中查找候选值,TypeSafe 选出其中一个,下游代码对其进行标准化处理并执行相应操作。
设置
pip install ipython phonenumbers "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/然后设置 TYPESAFE_API_KEY。
import os
import re
from decimal import Decimal
from pathlib import Path

import phonenumbers
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Choice, Noul, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
NONE = "none"  # the escape hatch on every selection: "none of the candidates fits"

# base_url defaults to https://api.typesafe.ai/ ; the env override points at another deployment.
ts = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # cached re-renders need no key
    base_url=os.environ.get("TYPESAFE_BASE_URL"),
    timeout=30.0,
)
json_cache = JsonCache(Path("json_cache.json"))
辅助函数
find 运行一个经过调优的正则表达式,以确保尽可能多地匹配结果,并对匹配项进行去重。pick 是一个 Choice 问题,其选项由 find 返回的文本片段(spans)构成,因此它的答案将是这些片段中完全匹配的一个,或在没有合适候选项时返回 none。classify 是一个基于固定标签集的 Choice 问题,在此处用于识别货币和国家。is_true 是一个 Noul,在此处用于询问某个金额是否为贷方(credit)。
每次调用都会缓存到 json_cache.json 中,因此重新渲染时不会发起任何 API 请求。
EMAIL_RE = re.compile(r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}")
PHONE_RE = re.compile(r"\(?\+?\d[\d\s()\-.]{6,}\d")
MONEY_RE = re.compile(r"[$€£¥]\s?\d[\d,]*(?:\.\d{2})?")


def find(pattern: re.Pattern, text: str) -> list[str]:
    """Code-side candidate finder: recall-tuned regex, deduped, in document order."""
    seen: set[str] = set()
    out: list[str] = []
    for match in pattern.findall(text):
        span = match.strip()
        if span and span not in seen:
            seen.add(span)
            out.append(span)
    return out


@json_cache
def pick(document: str, candidates: list[str], question: str) -> dict:
    """TypeSafe selects which found span plays the role. Returns {choice, confidence}.

    The options ARE the candidate spans, so ``choice`` is a verbatim copy of one of them (or the
    ``none`` hatch) - the model chooses, code owns the string."""
    criteria = {c: None for c in candidates} | {
        NONE: "None of these is the requested value."
    }
    answer = ts.system_one(
        state=document,
        questions={"pick": Choice(instructions=question, criteria=criteria)},
        model=TYPESAFE_MODEL,
    ).answers["pick"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def classify(document: str, question: str, options: list[str]) -> dict:
    """A small Choice over a fixed label set (currency, country, ...). Returns {choice, confidence}."""
    answer = ts.system_one(
        state=document,
        questions={
            "q": Choice(instructions=question, criteria={o: None for o in options})
        },
        model=TYPESAFE_MODEL,
    ).answers["q"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def is_true(document: str, question: str) -> float:
    """A yes/no Noul. Returns P(yes)."""
    return (
        ts.system_one(
            state=document,
            questions={"q": Noul(instructions=question)},
            model=TYPESAFE_MODEL,
        )
        .answers["q"]
        .noul
    )
邮件:根据角色选择合适的地址
邮件头中包含四个地址。正文要求将收据发送至个人地址,而非 To: 字段中的账单别名,因此答案取决于对正文的阅读。这里涉及两个问题:收据应发送至哪个地址,以及消息是由哪个地址发送的。
EMAIL_DOC = """From: Dana Whit <[email protected]>
To: [email protected]
Cc: [email protected]
Reply-To: [email protected]

Hi team - please don't use the billing alias for this one. Send my receipt to my
personal address instead. Thanks, Dana."""

emails = find(EMAIL_RE, EMAIL_DOC)
receipt = pick(
    EMAIL_DOC, emails, "Which email address does the sender want their receipt sent to?"
)
sender = pick(
    EMAIL_DOC, emails, "Which email address did this message come from (the From line)?"
)

print("candidates :", emails)
# code copies the picked value verbatim and normalizes (lowercase); it never re-types it
print(
    f"receipt -> : {receipt['choice'].lower():<28} (conf {receipt['confidence']:.2f})"
)
print(f"sender  -> : {sender['choice'].lower():<28} (conf {sender['confidence']:.2f})")
candidates : ['[email protected]', '[email protected]', '[email protected]', '[email protected]']
receipt -> : [email protected] (conf 0.98)
sender -> : [email protected] (conf 1.00)receipt 是 Reply-To: 行上的个人 Gmail 地址,这也是正文所要求的内容;sender 是 From 行上的地址。两者都是正则表达式匹配的副本,在代码中已转换为小写。
电话号码:选择手机号码,并规范化为 E.164 格式
有三个号码,其中均不包含国家代码。TypeSafe 会选择手机号码,并从文本中读取国家代码;phonenumbers 将这两个答案组合成 E.164 格式,即以 + 和国家代码开头的国际格式。
PHONE_DOC = """Reach our San Francisco office at these numbers: main desk (415) 555-0199,
billing fax (415) 555-0142, and my direct cell (415) 555-0177. Call the cell if it's urgent."""

phones = find(PHONE_RE, PHONE_DOC)
mobile = pick(PHONE_DOC, phones, "Which of these is the direct mobile / cell number?")
region = classify(
    PHONE_DOC,
    "In what country is this office located?",
    ["US", "GB", "DE", "FR", "CA", "AU"],
)

# code copies the picked value and normalizes it with the model-supplied country
parsed = phonenumbers.parse(mobile["choice"], region["choice"])
e164 = phonenumbers.format_number(parsed, phonenumbers.PhoneNumberFormat.E164)

print("candidates :", phones)
print(f"mobile  -> : {mobile['choice']}  (conf {mobile['confidence']:.2f})")
print(f"country -> : {region['choice']}  (conf {region['confidence']:.2f})")
print(f"E.164   -> : {e164}")
candidates : ['(415) 555-0199', '(415) 555-0142', '(415) 555-0177']
mobile -> : (415) 555-0177 (conf 1.00)
country -> : US (conf 0.90)
E.164 -> : +14155550177数字本身无法表明哪个号码是手机号码,也无法说明其所属国家;这些信息由周围的文字提供。TypeSafe 会读取这些文字,并将选定的号码格式化为 +14155550177。
金额:选择金额、分类货币、标记信用卡与借记卡
一张包含四个金额的发票。TypeSafe 会选出应付总额和信用卡金额,读取货币类型,并将每个选中的金额标记为借记卡或信用卡交易。代码会复制每个选中的字符串,并将其解析为 Decimal 类型。
MONEY_DOC = """Invoice INV-2087.
Subtotal: $1,200.00
Sales tax: $115.50
Total due: $1,315.50
A $50.00 courtesy credit from last month has already been applied."""

amounts = find(MONEY_RE, MONEY_DOC)
currency = classify(
    MONEY_DOC,
    "What currency are these amounts in?",
    ["USD", "EUR", "GBP", "JPY", "CAD"],
)
total = pick(MONEY_DOC, amounts, "Which amount is the total the customer must pay?")
credit = pick(
    MONEY_DOC, amounts, "Which amount is the courtesy credit that was applied?"
)


def to_decimal(value: str) -> Decimal:
    """Copy the picked value and parse the number in code (US grouping/decimal here)."""
    return Decimal(re.sub(r"[^\d.]", "", value))


for label, chosen in [("total due", total), ("credit", credit)]:
    is_credit = is_true(
        MONEY_DOC,
        f"Is the amount {chosen['choice']} a credit or refund to the customer, not a charge?",
    )
    kind = "credit" if is_credit > 0.5 else "charge"
    print(
        f"{label:<10}: {chosen['choice']:<10} -> {to_decimal(chosen['choice'])} {currency['choice']} "
        f"({kind}, P(credit)={is_credit:.2f})"
    )
print("\ncandidates :", amounts)
total due : $1,315.50 -> 1315.50 USD (charge, P(credit)=0.01)
credit : $50.00 -> 50.00 USD (credit, P(credit)=0.99)
candidates : ['$1,200.00', '$115.50', '$1,315.50', '$50.00']应付总额为 $1,315.50,信用额度为 $50.00,两者均以 USD 计价。Noul 对总额给出的答案为 0.01,对信用额度给出的答案为 0.99,因此代码能够知晓其解析的每个 Decimal 的符号。
to_decimal假设逗号用于分隔千位,而点号是小数点。这适用于$1,315.50;在€1.315,50中则相反。请提出一个Noul问题,询问文档使用的是哪种约定,并在代码中据此进行分支处理。
在 TypeSafe 游乐场中打开
一个分享链接,可在浏览器中打开电子邮件线程,其中包含收据问题以及正则表达式在其选项中找到的四个地址。
receipt_criteria = {e: None for e in emails} | {
    NONE: "None of these is the requested value."
}
playground_link = make_playground_link(
    EMAIL_DOC,
    {
        "receipt": Choice(
            instructions="Which email address does the sender want their receipt sent to?",
            criteria=receipt_criteria,
        )
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this thread + selection in the TypeSafe playground]({playground_link})"
    )
)两个限制
- 一个
Choice问题最多允许 255 个选项。如果候选项超过此数量,请分两个阶段进行筛选:先选择部分,再选择其中的范围。 - 查找候选项是工作量所在。电子邮件、电话号码和金额有正则表达式可以覆盖它们;而姓名没有,因此其候选项必须来自你已有的名单,或者来自命名实体识别器或提出候选项的 LLM。TypeSafe 随后会选出问题所要求的那个。