 JevCode
函数调用
通过将函数名称和闭集参数映射到具有置信度感知的 TypeSafe 问题,将自然语言交易请求转换为对普通类型化函数的调用。
本文由机器翻译自 en,未经人工校对,仅供快速参考。

当您点单“大杯冰燕麦拿铁,不加糖”时,咖啡师并不会将您的整句话写下来,而是直接在杯子上勾选四个选项。本 cookbook 对交易 API 也采用相同的机制:输入是一句自然语言描述,输出则是函数名称及其参数(以评估后的枚举形式呈现),并附带每个选项的置信度。
"plot rolling correlation between nvda and spy for the past month"
    rolling_correlation(symbol='NVDA', benchmark='SPY', window='1mo')   confidence 0.91

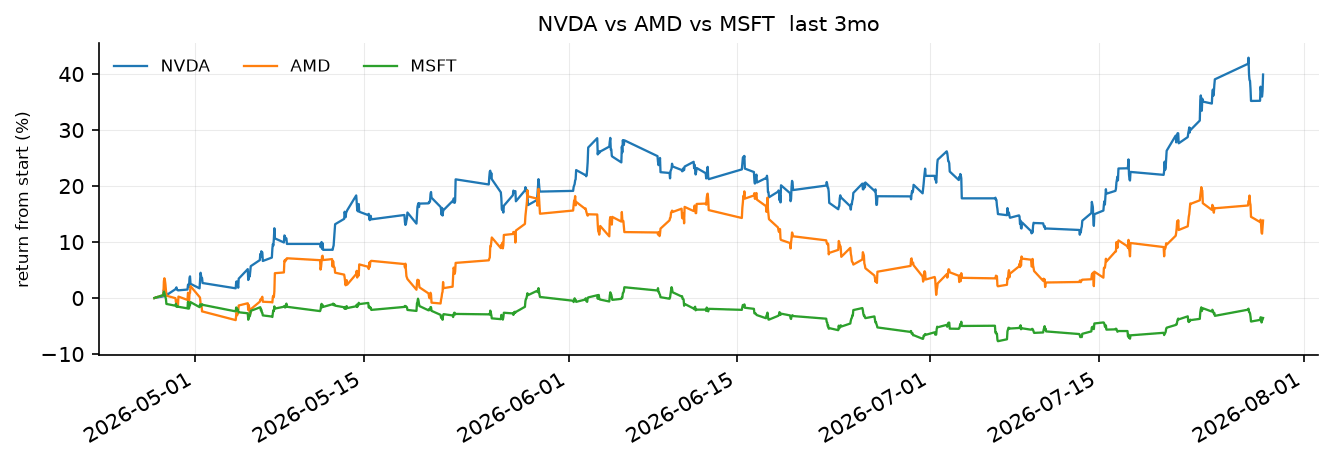
"compare nvda amd and msft over the past three months"
    compare_returns(symbols=['NVDA', 'AMD', 'MSFT'], window='3mo')      confidence 0.94

"show me apple daily with volume"
    plot_price(symbol='AAPL', resolution='1d', include_volume=True)     confidence 0.75

"what tickers do you have"
    list_symbols()                                                     confidence 1.00
这些调用指向交易助手中的十个普通函数。它们的参数取值来自固定列表,因此它们已经是 Literal 类型:
def plot_price(
    symbol: Literal["SPY", "NVDA", "AMD", "AAPL", "MSFT", "TSLA"],
    style: Literal["line", "candles"] = "line",
    resolution: Literal["1m", "5m", "15m", "1h", "1d"] = "15m",
    window: Literal["1d", "1w", "1mo", "3mo"] = "1w",
    include_volume: bool = False,
    moving_average: Literal["9", "20", "50"] | None = None,
    log_scale: bool = False,
): ...
一个其值来自固定列表的参数是一个封闭集。当它从该列表中选取一个值时,它会得到一个针对这些确切值的 Choice 问题,因此到达函数的值必然是函数所接受的。你无需改动函数本身。你所添加的是一个规范,用通俗的语言说明每个参数的含义。最终,你将拥有一个 Dispatcher,可以将其指向你自己的函数。
环境配置
pip install ipython polars matplotlib numpy "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/设置 TYPESAFE_API_KEY。该文件旁边有两个模块。trader.py 包含十个函数以及一个 TypeSafe 客户端,该客户端从缓存中读取答案,因此重新渲染时会重现上述数值,而无需调用 API。dispatch.py 包含读取签名和规范并发起调用的代码。
import json
from pathlib import Path

from cooksafe import make_playground_link
from dispatch import ROUTE, Dispatcher, closed_sets
from IPython.display import Markdown, display
from trader import TOOLS, client, load

TYPESAFE_MODEL = "jev-1.12"
print(f"{len(TOOLS)} functions over {load().height:,} one-minute bars")
10 functions over 156,780 one-minute bars在签名中查找封闭集
类型提示已经说明了哪些参数来自固定列表,以及每个列表中包含的内容。closed_sets 读取一个签名,并将这些参数归类为三种形态:choice(Literal,即从列表中选择一个值)、set(list[Literal[...]],即任意数量的值)或 flag(bool,即开或关)。所有十个函数均在 trader.py 中定义。
for name, fn in TOOLS.items():
    shapes = closed_sets(fn)
    print(
        f"  {name:<20}{len(shapes)}  "
        + ", ".join(f"{a}:{s}" for a, (s, _) in shapes.items())
    )
print(
    f"\n{sum(len(closed_sets(fn)) for fn in TOOLS.values())} fillable arguments in total"
)
list_symbols 0
market_summary 1 window:choice
plot_price 7 symbol:choice, style:choice, resolution:choice, window:choice, include_volume:flag, moving_average:choice, log_scale:flag
intraday_pattern 3 symbol:choice, window:choice, metric:choice
compare_returns 3 symbols:set, window:choice, normalize:flag
rolling_correlation 4 symbol:choice, benchmark:choice, window:choice, resolution:choice
summary_stats 2 symbol:choice, window:choice
volatility 3 symbol:choice, window:choice, annualized:flag
top_movers 2 window:choice, direction:choice
drawdown 3 symbol:choice, window:choice, plot:flag
28 fillable arguments in totaltop_movers 展示了被排除在外的内容。它的三个参数中,有两个是封闭集合。第三个参数 limit 是 int 类型,因此它不会收到问题,并保持其默认值 3。自由文本、数字和日期的处理方式相同:没有对应的问题,且函数的默认值生效。
编写规范
Literal 提供了字符串 "1mo" 和 "3mo"。它并未说明用户输入“this quarter”时指的是后者。规范中定义了这一点。规范为每个参数包含一个问题,为每个选项包含一行,为每个函数包含一个描述,并包含一个用于在函数之间进行选择的问题。它位于 spec.json 中,LLM 可以根据函数签名为您生成该规范。
SPEC = json.loads(Path("spec.json").read_text())
for argument in ("style", "moving_average"):
    print(
        json.dumps(
            {argument: SPEC["functions"]["plot_price"]["arguments"][argument]}, indent=2
        )
    )
{
"style": {
"question": "Does the user want a plain line or candles?",
"stated": "Does the user say how the chart should be drawn, such as a line, candles, or OHLC bars?",
"options": {
"line": "a simple line through the closing prices",
"candles": "a candlestick or OHLC chart, showing each bar's open, high, low and close"
}
}
}
{
"moving_average": {
"question": "How many bars should the moving average cover - nine, twenty, or fifty?",
"stated": "Does the user ask for a moving average or a smoothed line over the candles?",
"options": {
"9": "a nine-bar moving average, a fast one",
"20": "a twenty-bar moving average",
"50": "a fifty-bar moving average, a slow one"
}
}
}选项键是函数接收的字符串,因此无需在事后将标签映射回参数。stated 使参数变为可选。它提出第二个是/否问题,询问命令是否对该参数有任何提及。如果答案为否,则调用时省略该参数,并应用函数自身的默认值。
集合参数的每个成员都会获得一个问题,其中 {} 代表成员名称。"Does the user want {} in the comparison?" 会为每个股票代码生成一个问题。
针对概念而非用户可能选择的措辞来编写每个问题,因为匹配是基于语义的:“is amd tracking nvidia lately” 能够匹配到 rolling_correlation,尽管 spec.json 中既没有 tracking 也没有 lately。避免以参数名称命名问题,例如 "Which resolution?" 会让命令缺乏可匹配的参照。
将规范转换为问题
Dispatcher 根据规范一次性构建问题。随后,每个命令都是一个请求,包含所选函数及其所有函数的参数,而调度器仅读取所选函数的答案。
assistant = Dispatcher(SPEC, TOOLS, client)
print(f"{len(assistant.questions)} questions per command, among them:")
for qid in (
    "__tool__",
    "plot_price.style",
    "plot_price.style?",
    "compare_returns.symbols.NVDA",
):
    question = assistant.questions[qid]
    print(f"  {qid:<30}{question['type']:<8}{str(question['instructions'])[:64]}")
54 questions per command, among them:
__tool__ choice What is the user asking the trading assistant to do?
plot_price.style choice Does the user want a plain line or candles?
plot_price.style? noul Does the user say how the chart should be drawn, such as a line,
compare_returns.symbols.NVDA noul Does the user want NVDA in the comparison?运行十四条命令
每个请求占据一行,其 confidence(置信度)是该调用背后最不确定的判断。
COMMANDS = [
    "show nvda 1h",
    "plot rolling correlation between nvda and spy for the past month",
    "when during the day does nvda trade the most",
    "what moved today",
    "what tickers do you have",
    "how did the market do this week",
    "candles for tesla with a 20 period moving average",
    "compare nvda amd and msft over the past three months",
    "how volatile is tsla",
    "biggest losers today",
    "worst drawdown for nvda this quarter, and chart it please",
    "spy stats for the last month",
    "show me apple daily with volume",
    "is amd tracking nvidia lately",
]

CALLS = {command: assistant(command) for command in COMMANDS}
for command, call in CALLS.items():
    print(f'  "{command}"')
    print(
        f"      {str(call):<66}confidence {call.confidence:.2f}"
        f"   tool {call.tool.probability:.2f}"
    )
"show nvda 1h"
plot_price(symbol='NVDA', resolution='1h') confidence 0.78 tool 1.00
"plot rolling correlation between nvda and spy for the past month"
rolling_correlation(symbol='NVDA', benchmark='SPY', window='1mo') confidence 0.91 tool 1.00
"when during the day does nvda trade the most"
intraday_pattern(symbol='NVDA') confidence 0.53 tool 1.00
"what moved today"
top_movers(window='1d', direction='gainers') confidence 0.90 tool 0.90
"what tickers do you have"
list_symbols() confidence 1.00 tool 1.00
"how did the market do this week"
market_summary(window='1w') confidence 0.96 tool 0.99
"candles for tesla with a 20 period moving average"
plot_price(symbol='TSLA', style='candles', moving_average='20') confidence 0.69 tool 0.97
"compare nvda amd and msft over the past three months"
compare_returns(symbols=['NVDA', 'AMD', 'MSFT'], window='3mo') confidence 0.94 tool 1.00
"how volatile is tsla"
volatility(symbol='TSLA') confidence 0.96 tool 1.00
"biggest losers today"
top_movers(window='1d', direction='losers') confidence 0.98 tool 0.98
"worst drawdown for nvda this quarter, and chart it please"
drawdown(symbol='NVDA', window='3mo', plot=True) confidence 0.84 tool 0.84
"spy stats for the last month"
summary_stats(symbol='SPY', window='1mo') confidence 0.88 tool 0.88
"show me apple daily with volume"
plot_price(symbol='AAPL', resolution='1d', include_volume=True) confidence 0.75 tool 0.85
"is amd tracking nvidia lately"
rolling_correlation(symbol='AMD', benchmark='NVDA') confidence 0.82 tool 0.82两个长命令都按预期生成。“plot rolling correlation between nvda and spy for the past month”(绘制过去一个月 NVDA 与 SPY 之间的滚动相关性)从一个句子中填充了四个参数。其中两个参数 symbol 和 benchmark 从相同的六个股票代码中抽取,每个股票代码都正确落入对应的参数中,因为问题明确说明了角色:被测量的对象,排在前面 与 排在后面的对象,作为基准。“compare nvda amd and msft over the past three months”(比较过去三个月 NVDA、AMD 和 MSFT 的表现)将三个股票代码放入集合中,而排除了其他三个。
运行其中三个:
for command in (
    "plot rolling correlation between nvda and spy for the past month",
    "compare nvda amd and msft over the past three months",
    "when during the day does nvda trade the most",
):
    print(f'"{command}"  ->  {CALLS[command]}')
    display(CALLS[command].run())
"plot rolling correlation between nvda and spy for the past month" -> rolling_correlation(symbol='NVDA', benchmark='SPY', window='1mo')
"compare nvda amd and msft over the past three months" -> compare_returns(symbols=['NVDA', 'AMD', 'MSFT'], window='3mo')
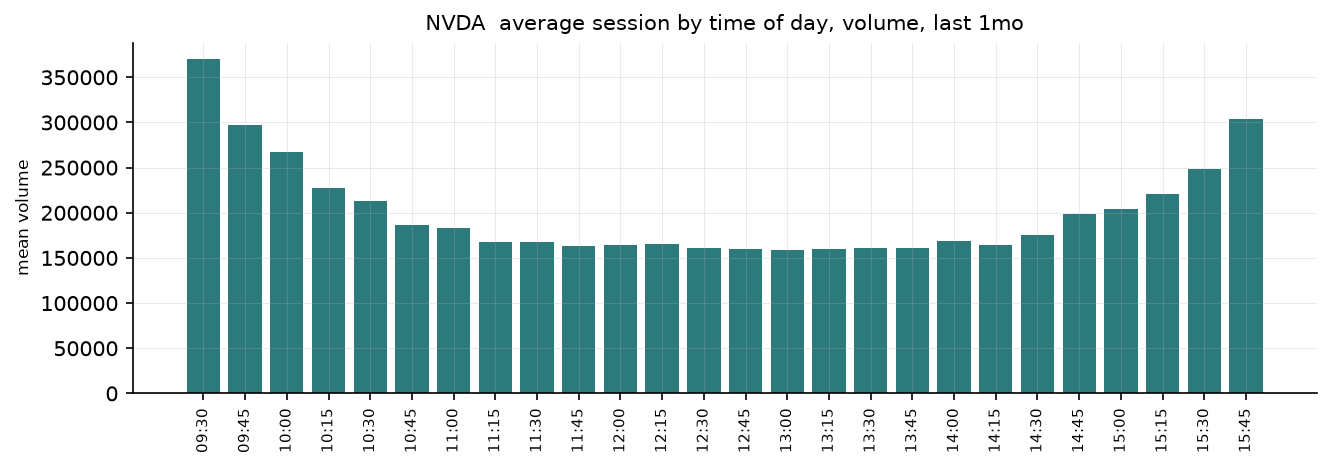
"when during the day does nvda trade the most" -> intraday_pattern(symbol='NVDA')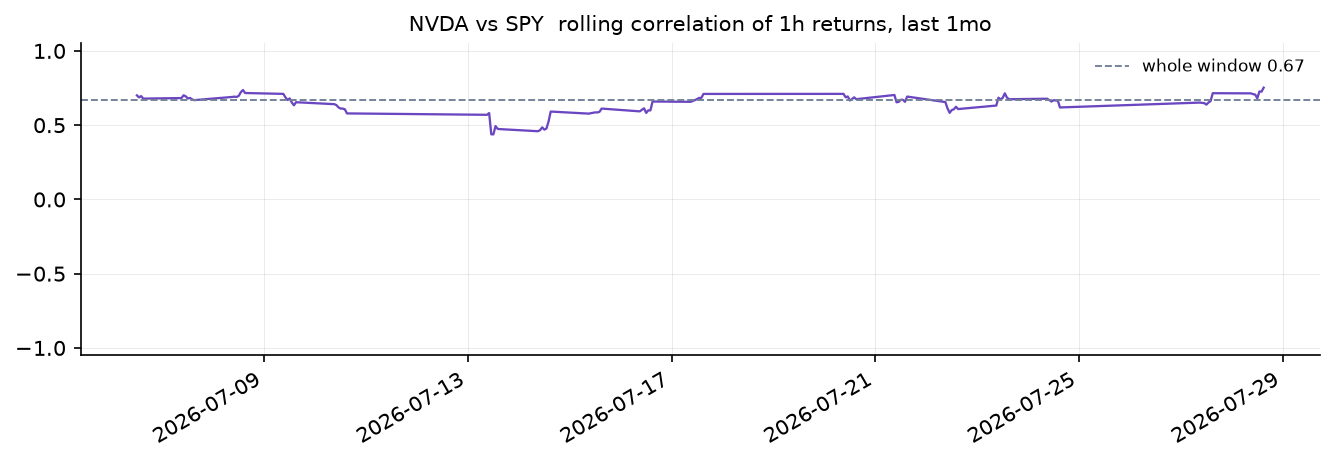
以及那些以文本形式作答的:
for command in ("how did the market do this week", "biggest losers today"):
    print(f'"{command}"  ->  {CALLS[command]}')
    print(CALLS[command].run(), "\n")
"how did the market do this week" -> market_summary(window='1w')
the board over 1w
NVDA 254.12 9.62% 389,465,563
AMD 184.20 1.51% 182,740,497
AAPL 258.71 0.97% 223,818,998
SPY 664.86 0.40% 138,617,365
MSFT 451.35 0.26% 113,427,173
TSLA 320.22 -0.97% 266,317,023
"biggest losers today" -> top_movers(window='1d', direction='losers')
top 3 losers over 1d
AMD -0.57% -> 184.20
MSFT 0.67% -> 451.35
AAPL 1.40% -> 258.71 读取置信度
confidence 报告的是调用中置信度最低的判断,而非所有判断的乘积,因为一个错误的参数就足以破坏结果。乘积回答的是另一个问题(“每个部分是否都正确”),并且随着函数参数数量的增加,乘积值会下降,无论其中任何一个判断是否可靠。
该数值是如何逐个参数得出的:
call = CALLS["is amd tracking nvidia lately"]
print(f'"is amd tracking nvidia lately"  ->  {call}   confidence {call.confidence:.2f}')
for name, argument in call.arguments.items():
    top = sorted(argument.distribution.items(), key=lambda kv: -kv[1])[:3]
    shown = "omitted, default stands" if argument.omitted else repr(argument.value)
    print(
        f"  {name:<12}{shown:<26}p {argument.probability:.2f}   "
        + "  ".join(f"{k} {v:.2f}" for k, v in top)
    )
print(f"  weakest argument: {call.weakest().name}")
"is amd tracking nvidia lately" -> rolling_correlation(symbol='AMD', benchmark='NVDA') confidence 0.82
symbol 'AMD' p 0.87 AMD 0.87 NVDA 0.13 AAPL 0.00
benchmark 'NVDA' p 0.78 NVDA 0.92 AMD 0.08 AAPL 0.00
window omitted, default stands p 0.96
resolution omitted, default stands p 0.99
weakest argument: benchmark此处省略了 window 和 resolution,因为“最近”(lately)并未说明回溯的时间范围或基于何种时间粒度,因此 rolling_correlation 将使用其默认值:一个月和小时级 K 线。这正是 stated 问题的作用所在。如果没有它,该选择就必须明确指定某个窗口,并且会以较高的置信度指定一个。
在游乐场中打开
下面的链接包含一个命令以及该函数所对应的问题:即从十个函数描述中做出的选择,以及 rolling_correlation 的四个参数。编辑其中的命令,参数也会随之改变。
COMMAND = "plot rolling correlation between nvda and spy for the past month"
picked = CALLS[COMMAND]
playground_link = make_playground_link(
    COMMAND,
    {ROUTE: assistant.questions[ROUTE]}
    | {q: v for q, v in assistant.questions.items() if q.startswith(f"{picked.name}.")},
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open the command and its questions in the TypeSafe playground]({playground_link})"
    )
)